Everything we ship, in plain language. Updated every week. Highlights shows the biggest changes first; All changes has every improvement and fix.
31 changes
New feature
Reuse an answer from an earlier activity, or from another study
Participants no longer get asked the same thing twice. In the Piping window you can now reuse an answer from an earlier activity in the same study, or from another study in your organisation. If someone said Cape Town in activity 1, activity 2 skips "Which city do you live in?" and goes straight to "Have you seen the adverts in Cape Town?". Anyone who never answered is asked once and carries on. It is off until you switch it on, and it works on the first question of an activity too.
New feature
Edit the automatic WhatsApp replies a study sends
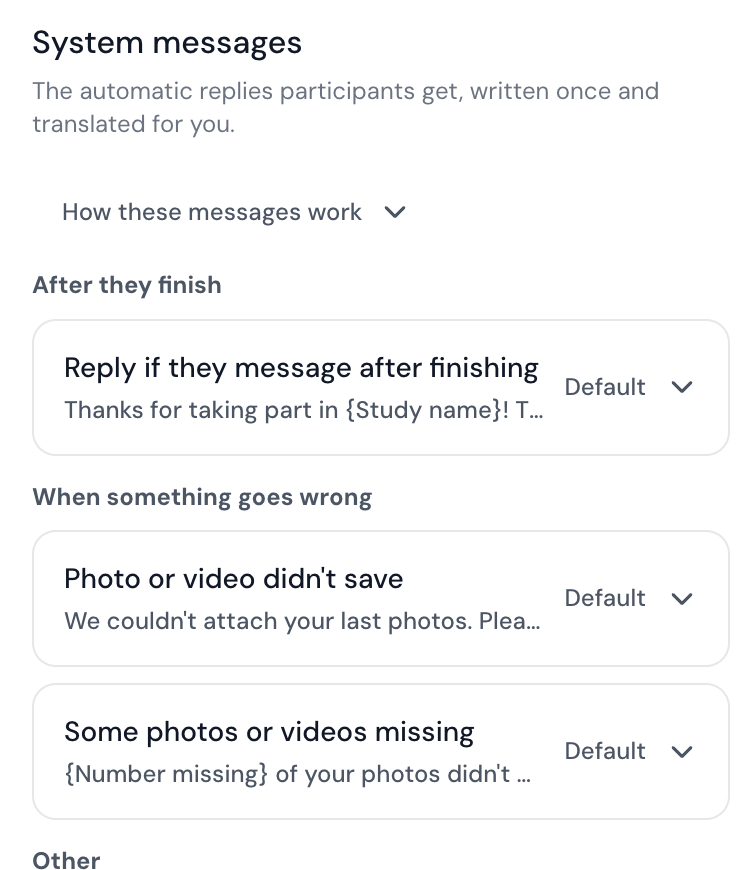
Every study, and every standalone activity, now has a System messages section. You can rewrite the replies Yazi sends on its own, like the thank you when someone finishes, the "please come back later" note between diary entries, the next activity prompt and the reply to someone who messages after the study is over. Write it once in your default language and the other languages fill in automatically, and hand-edited translations are kept. Leave a message blank and the standard wording goes out, so existing studies behave as before. You can also just ask Ask Yazi to change one for you. Diary participants now always get a "please wait" message between entries instead of silence.
System messages: the automatic replies a study sends, each editableNew feature
Check any single answer, then screen out or flag
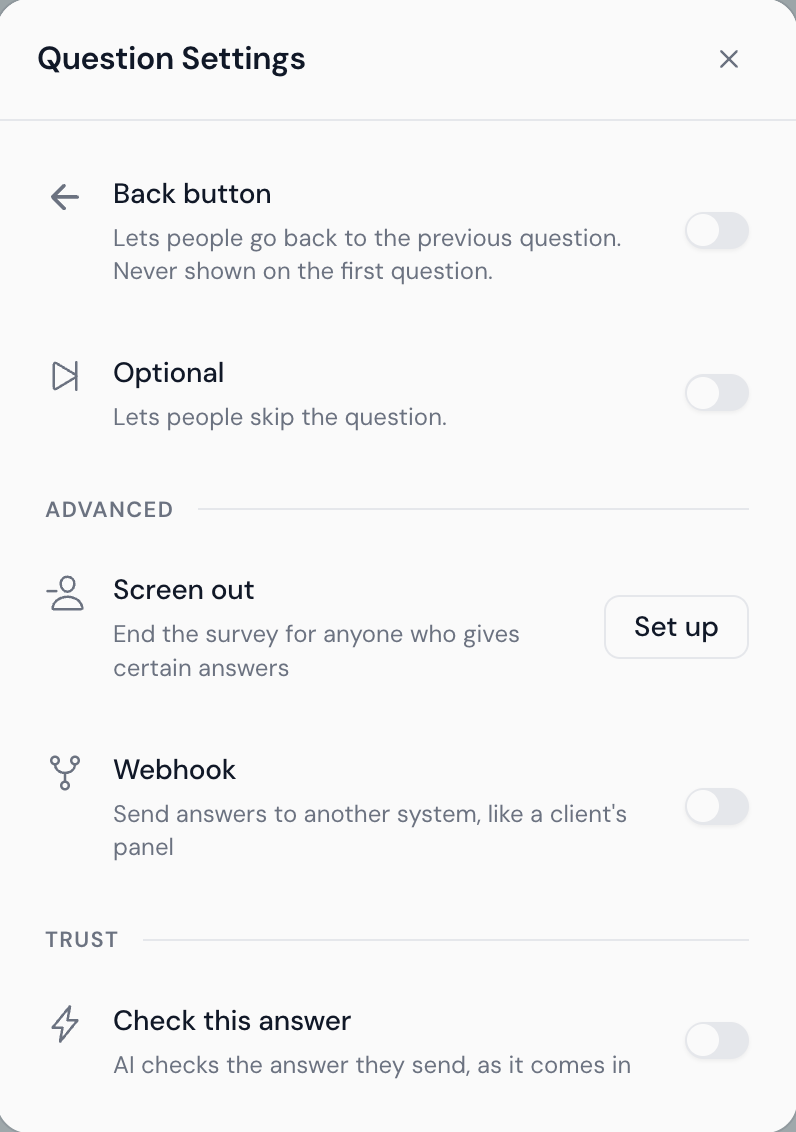
You can now switch on an AI answer check for one question, in that question's own settings, without turning anything on for the whole study. Choose what happens if the answer still doesn't fit after the retries: screen the person out with the question's or study's goodbye message, or flag them and let them carry on. Flagged people show "Failed check" in your results and in the CSV download. Handy for a photo question where you need the right photo, or a screener you want to hold firm.
Question Settings with Screen out and the new Check this answer switchNew feature
Build, launch and edit studies from Claude
If you work in Claude, you can now do almost all of a study there. Claude can create a draft survey, AI interview or recurring survey with its first questions, set up skip logic, "only show if" rules and answer piping, read and change study settings, delete a question from a Draft or Testing study, open and edit the report, and launch the study. Anything that goes live, changes a live study or deletes something is shown to you first and only happens when you say yes. After a launch Claude gives you a direct link to the study's Share page so you can add people straight away. Rewards, Flow, schedules and anything that spends money stay in the web app.
New feature
New WhatsApp numbers keep their message data in the UK
Every WhatsApp number a client connects is now set up on Meta's UK data storage from day one, with no manual step. If Meta won't confirm UK storage the number isn't connected and our team is alerted, and a daily check flags any number that isn't UK based. We can show you Meta's own confirmation for your security review.
Improvement
Build with AI shows you what it built and why
When you build a study from a brief, you now watch it take shape instead of staring at a loading screen. The builder appears straight away and Ask Yazi opens beside it with your brief and its steps as it works. When it's done you get a short "What I built" card, one line per activity with its type, number of questions and tags for screener, logic, piping and languages. Ask Yazi then walks you through its guesses one card at a time, you pick "That's right" or "Change this", and it makes every change in one go. Renaming the study on the proposal screen now works too.
Improvement
Excel downloads are much easier to read
Excel exports of study results now look the same for every study type. The header row is coloured and stays put as you scroll, each chat reads message by message with the speaker in bold, status is colour-coded, voice notes and videos are clickable links in their own columns, and empty columns are hidden. AI interview exports also no longer drop the odd transcript, and pictures on copied studies get a permanent link instead of one that stops working after a week.
Improvement
Tighter privacy for client security reviews
The web app no longer loads any third-party trackers for logged-in users, only our own analytics. Organisations can now be set to require two-step login for their members alone. Our internal alerts show only the last four digits of a participant's number, AI service logs are deleted after 30 days and no longer hold survey answers, and participant messages are no longer passed to an old partner server. The location map in moderator takeover now uses Google Maps.
Improvement
Pin columns in Table Data
On wide tables you can now hover a column header and click the pin to keep it on the left while the rest scrolls. Participant ID is pinned by default and your pins are remembered per study, so you always know whose answer you are reading across 50 or more columns.
Improvement
WhatsApp multi-select stops answers that contradict each other
When a multi-select question has "None of the above" or "All of the above" switched on, the WhatsApp form now greys out options that can't go together. Tick "None of the above" and the rest grey out, tick a real answer and "None" greys out. Participants no longer find out after pressing Submit, and your data stays clean.
Improvement
Statements can be up to 1,000 characters
A Statement question now holds up to 1,000 characters, up from 500, so you have room for longer intros and explanations. Long translated Statements are split into extra messages so they still send. Other question types stay at 500.
Improvement
Voice notes in AI interviews get quicker, smarter replies
Voice notes now come back in about 2 seconds instead of 9, and none take longer than 25. If someone messages while their voice note is still loading, they get a short "I'm going through your voice note now" reply and then one proper answer, and that holding reply shows in the transcript too. The interviewer also no longer tells people their voice note "didn't play" when it came through fine.
Improvement
The AI interviewer follows up properly
The interviewer won't wrap up while a Must cover topic still lacks a real answer, and it uses any spare questions to dig into the topics that matter most. It now remembers a participant's survey answers for the whole interview, not just the first question. Participants get one goodbye, not two, the closing questions come last, people already asked for a photo aren't also asked for a voice note in the same message, and its private notes never reach a participant.
Improvement
Words light up as you play a voice note or video
When you play a voice note in a participant's transcript, the words underneath light up as they are spoken, and clicking any word jumps to that moment. This now also works for videos that didn't support it before, and opening a clip full screen pauses the one behind it so you only hear it once.
Improvement
"Continue or start over" when someone rejoins an interview
If a participant taps the study link or sends the starter phrase again partway through an AI interview, they now get "Welcome back! Continue or start over?" instead of the survey restarting on top of their interview. This also works for one activity's own link in a multi-activity study.
Improvement
The quality check stops flagging people for answering quickly
The response quality check no longer flags people just for tapping through quick questions at a normal pace, and it judges whether someone tried to answer rather than whether they got it right. On one study the speed flags went from 94 people, nearly all genuine, to 5 who really were two to three times faster than everyone else.
Improvement
Broadcast Send History shows the real result
When a broadcast message fails for a moment and our automatic resend gets through, Send History now shows that person once with their real result, instead of counting the failed attempt too. A genuine failure with no reason from WhatsApp now says it was a temporary WhatsApp error, not "Unknown", and long failure reasons have a "Show more" button.
Improvement
A clearer path to your own WhatsApp number
The "Get your own WhatsApp number" screens are simpler. "Continue with Meta" unlocks once you confirm you have the three things Meta asks for, "Use Yazi's number for now" is always there, and the guide flags the two steps people most often get wrong in Meta's window. If your account has no payment method yet, you see a calm note that replies keep working and only broadcasts and invites need a card, instead of a red billing error.
Improvement
Every Prolific filter, and feasibility you can trust
The Prolific filter picker now shows Prolific's full list of around 500 filters, searchable, and only hides one when Prolific itself limits it to a single country. For PureSpectrum, Check Feasibility and Create recruitment now use the same incidence rate you typed, so a sample that looks reachable can actually be created.
Improvement
One phone number question type
There used to be two question types for collecting a phone number. Now there is one, Mobile number: you pick the countries respondents can be in, or All countries, and their number is checked against those. Existing Phone questions keep working as they are.
Improvement
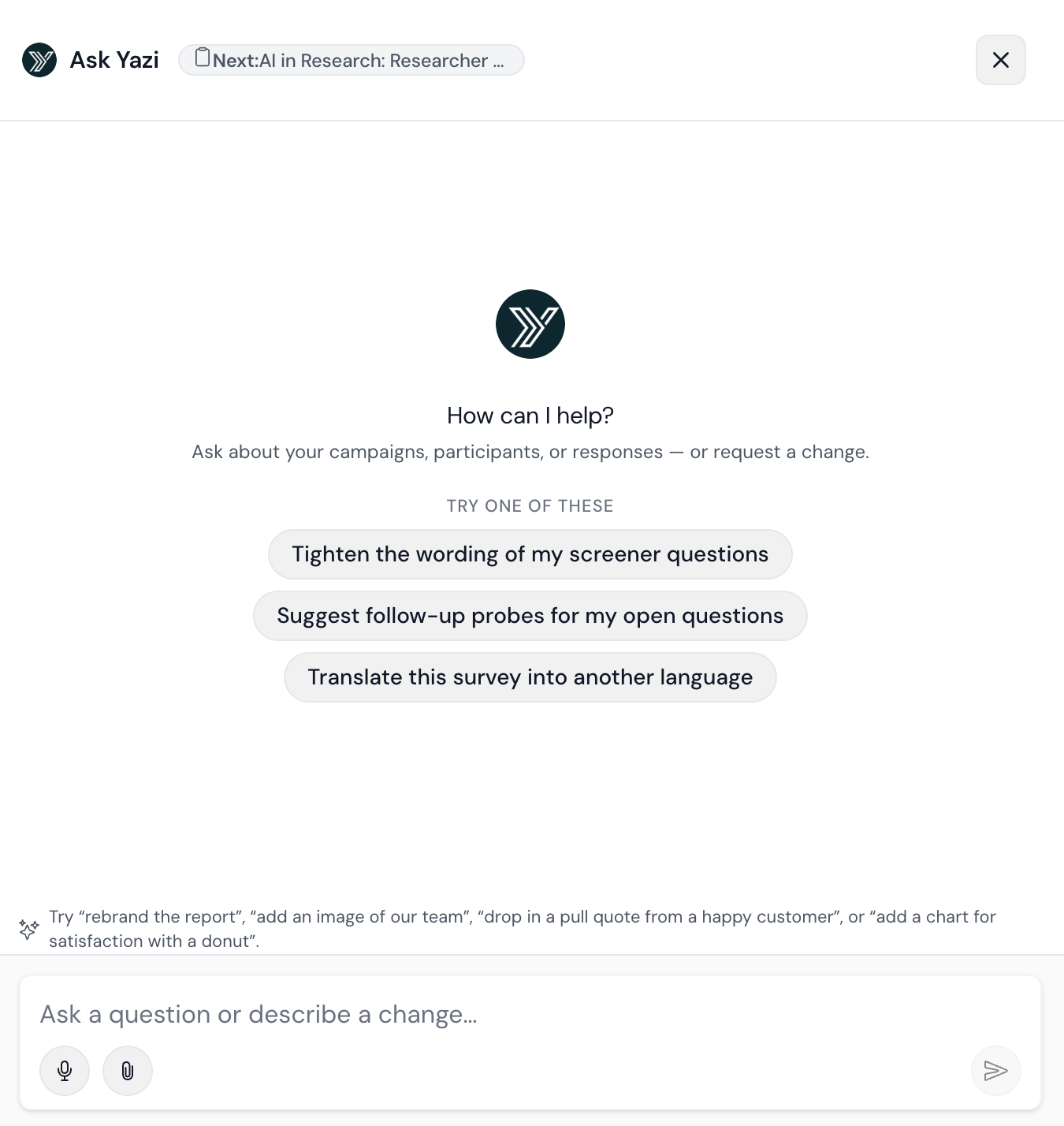
Ask Yazi is easier to follow
Ask Yazi now shows one short grey line above each reply saying what it did, like "Checked your organisation's numbers", and you can click it to see each step. It no longer uses internal setting names, it shortens over-long titles while planning so you see the exact name that will be built, and you can keep it open beside the builder without your questions getting squashed. The close button is now an X.
Improvement
Yazi works better on a phone
On a phone, the bottom of every screen now sits above Safari's toolbar, the page bar on card lists is a small floating pill, broadcast names show in full with filters folded into one row, the People page fits the screen, and you can open Interview configuration from an interview's Build tab.
Improvement
A quicker, tidier study builder
The study settings panel opens instantly and takes up less room when collapsed. Pop-up messages are back in the bottom-right corner on a computer so they never cover the Build, Share and Responses tabs. Hover hints on question icons show faster and say what Settings, Logic, Piping and Preview do.
Improvement
Each study keeps its own interview prompt
The old organisation-wide Interview Prompt has gone from Settings. Every interview study now runs on the prompt saved in its own interview setup, and a new study starts with our standard prompt and a research objective box that matches what the interviewer actually uses.
Improvement
Receipt reading returns more detail, for less
Receipts read from diary studies now come back with purchase occasion (breakfast, lunch, dinner and so on), store name, store address and province, alongside the existing columns, so nothing that reads the file today breaks. Each receipt also costs less to process, which makes very large receipt panels practical.
Fix
Participant names are back in Table Data and exports
Participant names, first and last names and date of birth were coming through blank in Table Data and downloads, even when we had them. They show again on every study.
Fix
Invites and sign-in codes always arrive
People who already had a Yazi account could get stuck on an "enter the code we emailed you" screen when no email was sent, for example when opening a workspace invite. Existing users are now taken to log in with their email filled in and get a clear "You already have a Yazi account" email. Broken invite links say why.
Fix
Pictures on AI interview questions reach WhatsApp, including in copied studies
A must-ask interview question with an image, like an emotions wheel, now arrives on WhatsApp with its picture. Before, the image could fail and take the question with it, and copied interviews sent the question without the picture.
Fix
Multi-language studies keep their languages
Changing a study's default language no longer removes the old one, switching Multi Language Support off and on keeps your list, ticking two languages quickly keeps both, and studies built by Ask Yazi translate themselves when they go to Testing or Live. Studies with more than 10 languages now show a "More languages" option so nobody gets silence at the language picker.
Fix
Transcripts show the right messages in the right place
A transcript on a study's Share tab now shows only that study, even if the person took part in another. In survey-then-interview studies, survey messages sit in the Survey tab and the AI Interview tab starts at "AI interview started". Stickers show on the participant's side, and "Survey completed" no longer appears after a finished interview.
Fix
Smaller fixes this week
One over-long question no longer blocks saving the rest of a study, and save errors say which question and what to do. "Update test version" keeps a study in Testing. Diaries start from their starter phrase again. Panel sign-up no longer stops at the recap screen. Matrix questions no longer get stuck on the shared WhatsApp number. The end-of-study card opens even if its WhatsApp template was deleted. Settings shows the Menu Campaign's name instead of a code, and Share is always clickable while a notification shows.
18 changes
New feature
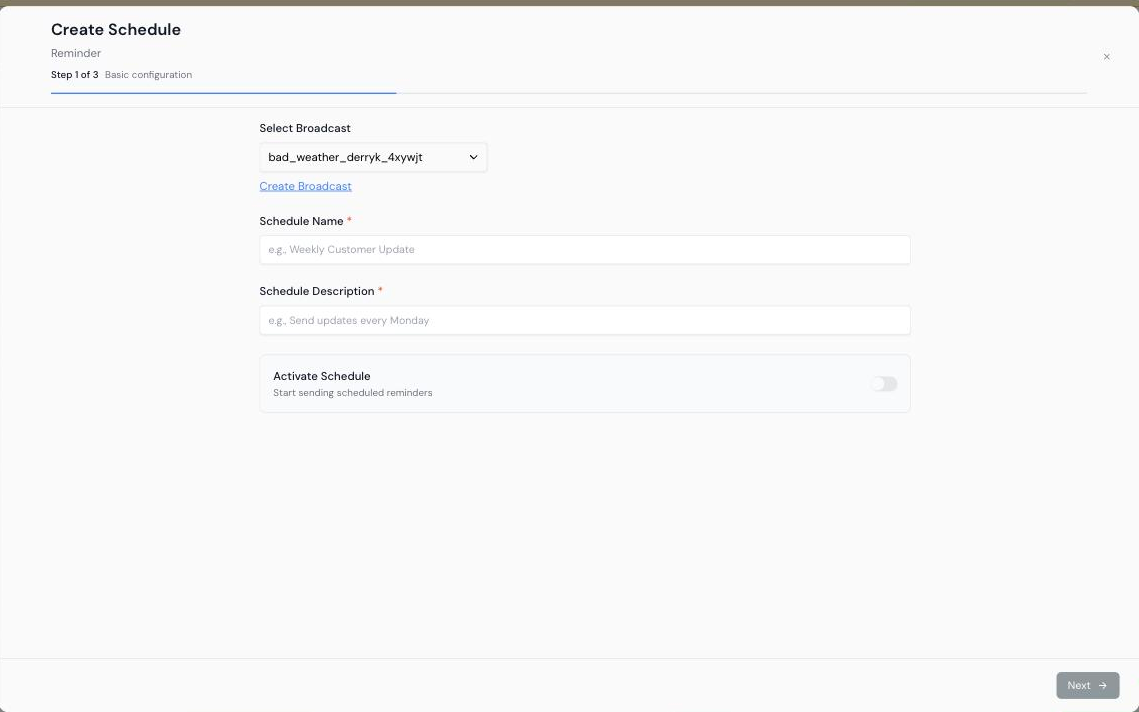
Send schedules and reminders in any time zone
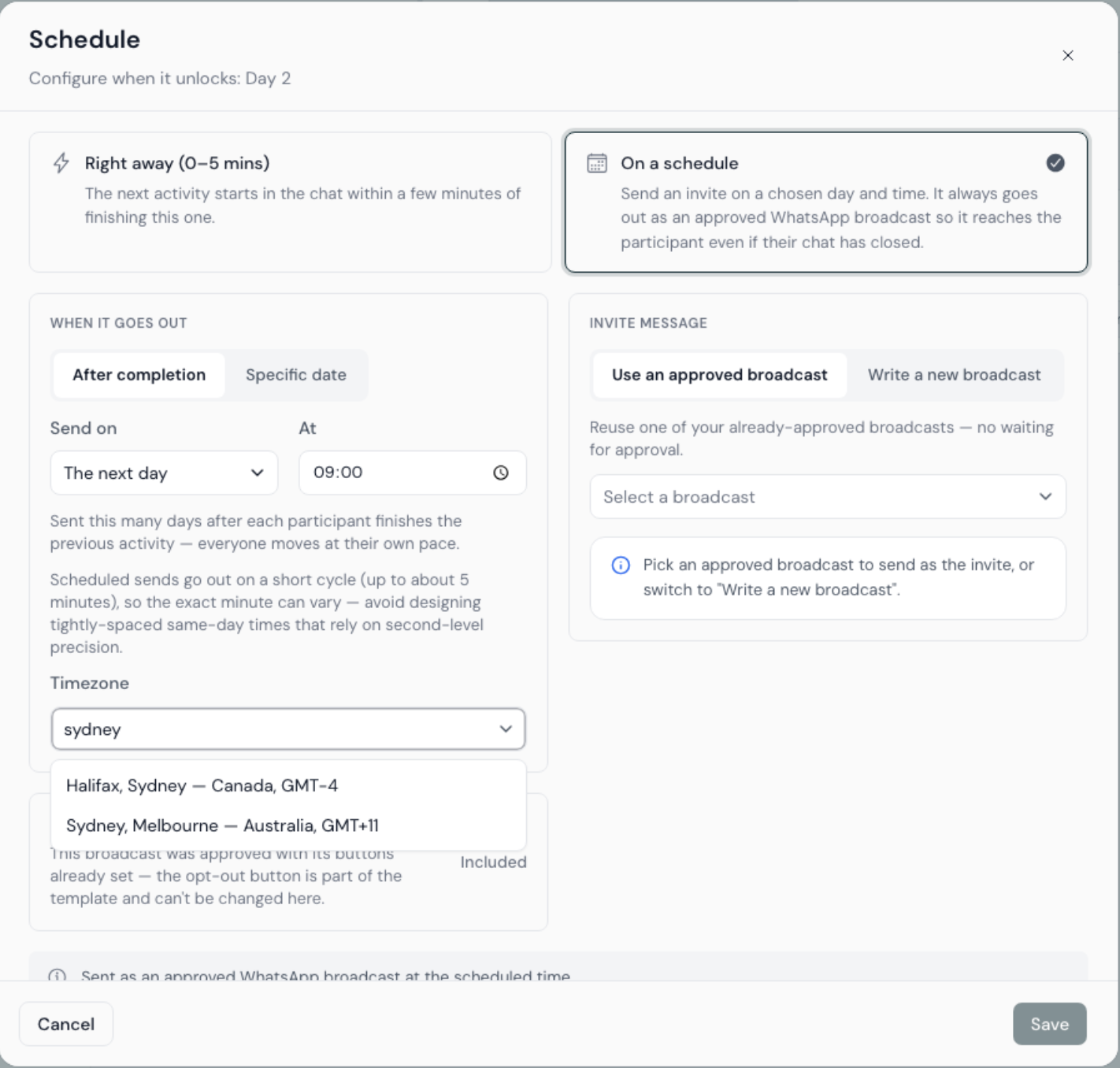
Schedules and reminders can now use any time zone in the world, and you can search for it. Type "sydney" and pick "Sydney, Melbourne, Australia, GMT+11". Before, the Timezone box had nine fixed options and nothing east of Japan, so a diary in Australia or New Zealand could not send at 9am local time. It can now.
Schedule window with the searchable Timezone box, Sydney foundNew feature
Run an AI interview inside the WhatsApp Flow
An AI interview can now run as screens inside the same WhatsApp Flow as the survey, so participants never leave the Flow to answer interview questions. Surveys that mix structured questions with an interview feel like one continuous experience.
New feature
A simpler AI interview setup page
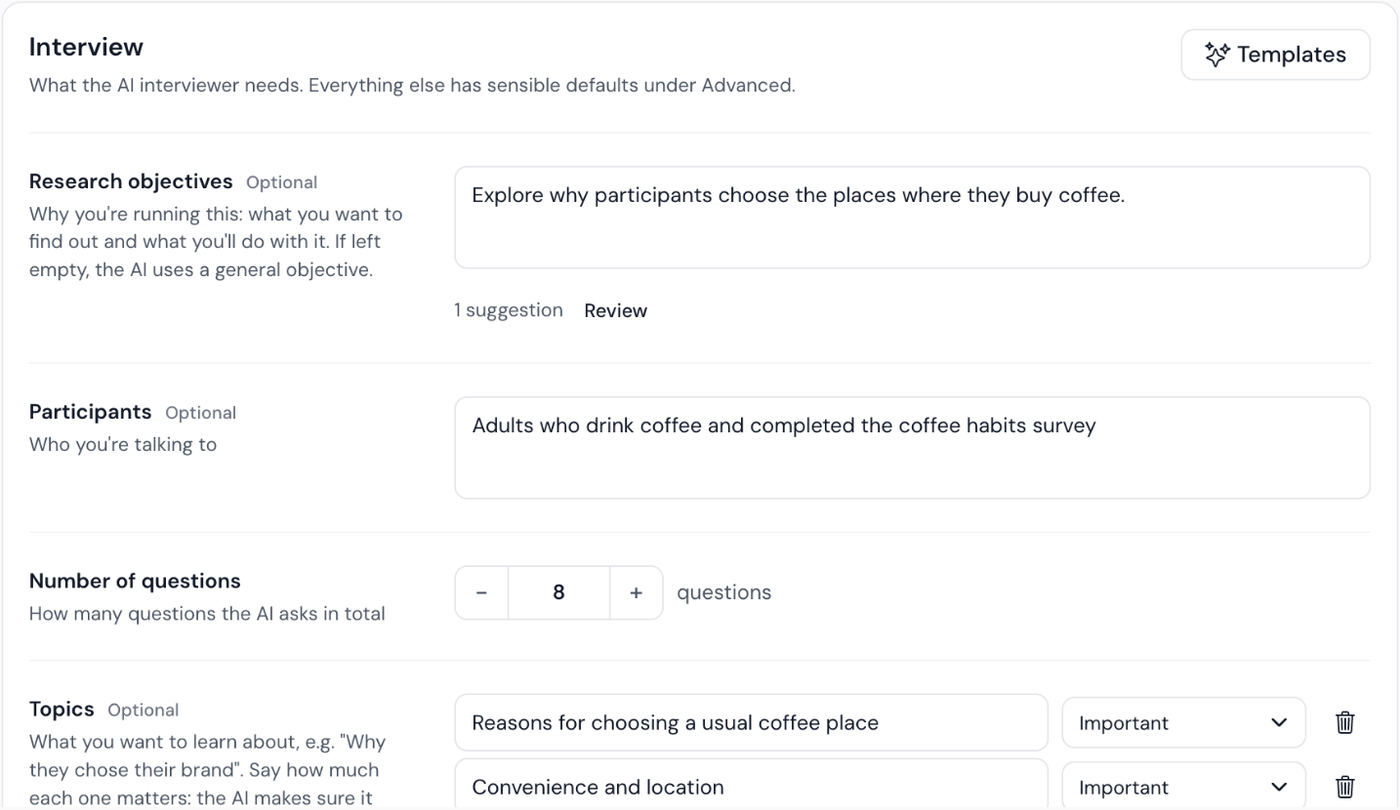
New interview studies open on one card with the essentials: research objective, participants, number of questions, topics and how people answer. Tone, question style, must-ask questions, background and the full instructions sit under Advanced. The AI also suggests clearer wording for your research objective, and the review takes about five seconds. Existing studies keep the old page.
The AI interview setup card: objective, participants, number of questions and topicsNew feature
Fake and wrong photos are now caught by Response Trust
If a survey asked for a photo and someone uploaded something unrelated, like a picture of their cat when asked for a race-day photo, the trust checker used to notice but let them through when their written answers sounded fine. It now counts a wrong photo against the response. The checker also does the sums on number answers (price per box, kg per person, spend against income) and flags answers that cannot be true, shows its working with each score, reads each question as the respondent saw it with their earlier answers filled in, and gets the true share of people who picked each answer on translated studies and tick-all-that-apply questions.
New feature
Choose which activity to export
On a study with more than one activity, Export now opens an options pop-up where you pick which activity to download. It starts on the activity you are looking at, and "All activities" still gives the full study. Studies also get the same answer options single campaigns already had: answer text or numeric codes, and short column names.
Improvement
Mark each interview topic as Must cover, Important or If it comes up
On the interview setup page, topics are no longer given a number of questions. Each topic is marked Must cover, Important or If it comes up. The interviewer digs in where it matters and makes sure it gets a real answer on the Must cover ones. New interviews also start on a warmer tone with updated interviewing instructions.
Improvement
The AI interviewer sounds less scripted
The interviewer no longer repeats a person's answer back before every question, uses their name once instead of on every message, and stops opening nearly every question in the Provocateur tone with a guess. It invites a voice note, or a voice note or short video when both are welcome, in one short line instead of asking over and over. It still plays things back when someone vents. If it keeps starting questions the same way it gets a nudge to word the next one differently. New studies get this now, existing studies get it when they are next saved.
Improvement
Export shows when it is working
After you click Export on an Excel download the button now greys out with a spinner until the file is ready, so nobody clicks it again and again.
Improvement
A clearer Study configuration panel
The Study configuration panel in Build now groups settings into seven clear sections with plain names and short explanations, and shows what participants will receive.
Improvement
Graph Data summaries add up
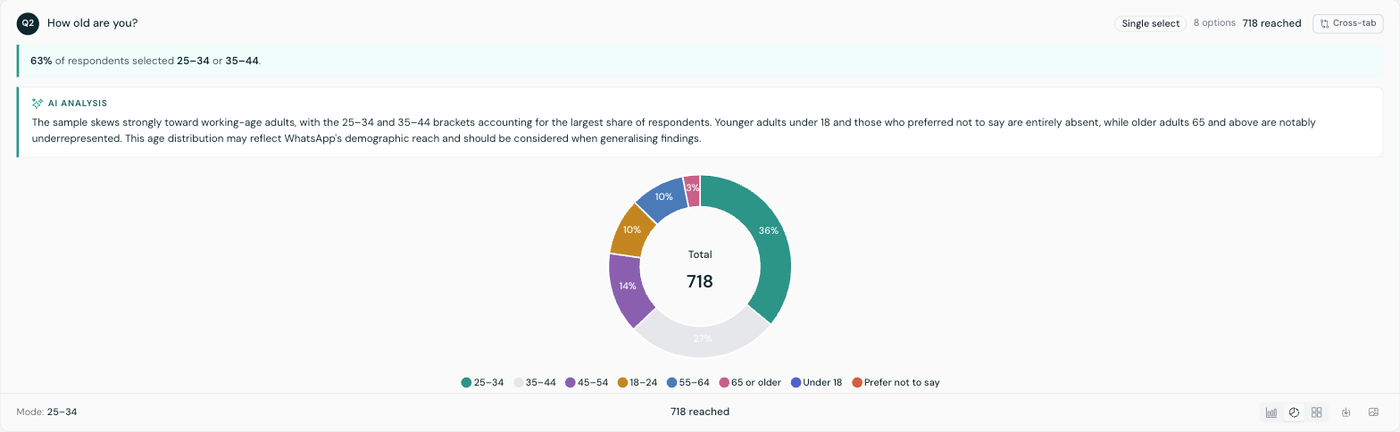
The one-line summary above each chart no longer adds the top two answers together (a 70% Yes and 30% No question no longer reads "100% selected Yes or No"). Tick-all-that-apply questions always show as bars, never a donut or pie, so the chart agrees with the summary above it.
Improvement
"Other" comes before "None of the above"
When a question has both switched on, "Other" now comes first and "None of the above" is always the last choice, so people whose answer is not listed reach "Other" instead of tapping "None" by mistake. This applies in the builder, the preview, WhatsApp and Live Forms.
Improvement
Moving from the shared WhatsApp number to your own is a full flow
Upgrade from Sandbox is now a guided flow instead of a small pop-up, and its Meta step scrolls so all six step cards can be read. The sidebar shows a client's own number as soon as they upgrade, and the dashboard Status column shows its real labels again after onboarding.
Improvement
Panel recruitment is created at the provider straight away
Create Recruitment now creates the PureSpectrum survey or Prolific study as a draft straight away, instead of only when you press Launch, so a failed launch no longer leaves a half-made study at the provider and you can see and check it before going live.
Improvement
Removing someone from one activity keeps their other activities
Removing someone from one activity in a study no longer wipes their answers in the others, and removed people no longer get invites sent automatically. Before, removing someone from Week 6 so they could redo it wiped Weeks 1 to 6 and then triggered fresh invites. Removing someone from the All activities view still removes them from the whole study.
Improvement
Thank-you message edits at go-live now save
When you take a study live, the thank-you message, scoring, reward and language settings you change in the review pop-up now save to that activity. Before, they looked saved but were thrown away.
Improvement
Statement screens in Flow surveys are just text and Next
In a WhatsApp Flow survey a Statement screen now shows its text and a Next button. Participants no longer have to tick "Continue" first.
Fix
AI interviews no longer ask the same closing question twice, or switch language
When the AI asked a closing question and the participant answered, Yazi sometimes decided the question had not been asked and asked it again. That is fixed. The AI interviewer also no longer switches to a language the study does not offer, for example Portuguese because the person answered an earlier study in it.
Fix
Smaller tidy-ups this week
Test links ending in "-TEST" let you retake a campaign again, Ask Yazi no longer says a Live study has no responses when it does, dropdowns move with their button when you scroll, the Ask Yazi tab shows its arrow when tucked away, new customers get a full-screen welcome tour, and the phone preview looks the same across the platform.
22 changes
New feature
Add a welcome message to surveys and diaries
You can now set a welcome message that participants see before the first question, then tap Continue to start. Turn it on under Welcome & completion, next to the completion message, or use the new "Add a welcome message" row at the top of the question list. It works for AI interview studies too, where there was no way to see or edit the welcome before. In testing, three of nine people looked for this setting and could not find it.
New feature
Mobile number question with country checks
A new Mobile number question type lets you choose which countries are allowed. If someone types a landline or a mistyped number, they are asked again with an example. Valid answers are saved in one clean format, so you do not have to tidy the data afterwards. Existing questions are unchanged.
Mobile number in the add question menuNew feature
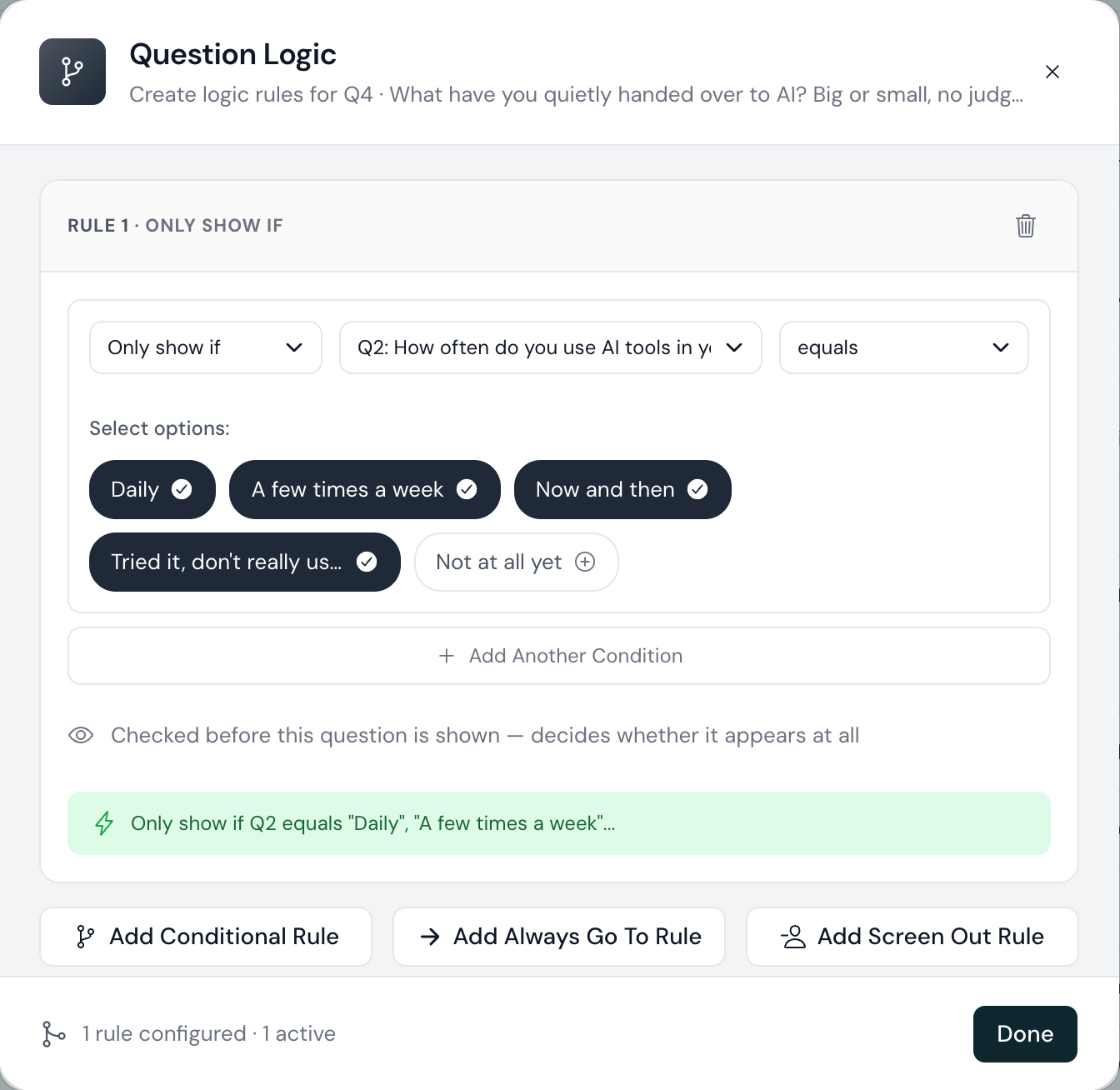
Screening now lives in Question Logic
Screen-outs are now a Screen Out Rule in Question Logic. You pick the answers that screen people out, and the question stays where you put it instead of jumping to the top of the survey. Question settings has a Screen out button that opens the rule.
Question Logic with an Only show if rule and the Add Screen Out Rule buttonNew feature
Panel recruitment on Prolific shows who they are
Researchers recruiting through Prolific now see Prolific's own demographics next to each participant in Table Data and in every export: age, sex, ethnicity, country, nationality, language, student and employment status and more where Prolific has them. You no longer download a file from Prolific and join it by hand in Excel, and the data stays in Yazi after Prolific's own retention runs out. People recruited in earlier rounds of a reopened study are included, and Web Survey respondents (Live Forms) get the same columns, with the real channel in "Recruited from".
New feature
People who hide their phone number on WhatsApp now get replies
WhatsApp lets some people use a username instead of a phone number. Yazi now keeps every number and username for each participant, per WhatsApp business account, and sends to the right one. Before this, a username starter phrase or answer was dropped and the person saw two ticks and no reply.
Improvement
Set the reward, the data question and quotas on Prolific
On a Prolific recruitment you can now set the reward per participant (the cost estimate updates as you type, and launch is blocked below Prolific's minimum). You answer Prolific's personal data question yourself and edit the privacy notice, which now arrives with the research consent paragraph already in. Quotas by sex and age now work on Prolific, so the sample fills to the split you asked for. A relaunch asks only for the places still missing, and the credits taken follow the smaller number.
Improvement
Study exclusions on Prolific keep people out
If a study excludes other studies, anyone who took part in those can no longer see it, even when studies are reopened for more people or launched later. Over one weekend, 20 people had done more than one of four linked studies before this was fixed.
Improvement
Clearer recruitment status and a tidier Share tab
When Prolific or PureSpectrum refuses to start a recruitment, it now shows Failed or Paused with the plain reason, such as not enough funds, instead of looking live. Reopening an older recruitment keeps its audience, a live recruitment can have its sample raised, and Duplicate is now on every recruitment. The progress card is about a third of the height, with completes, spend and cost per complete on one line, and the tabs and title row stay in view as you scroll.
Improvement
Add a button to the completion message from the Build tab
You can now add a button to the completion message straight from its card in the Build tab: no button, a link button that opens a web page, or a quick reply. Before, you had to leave the question list and open the settings panel.
Improvement
Web survey links no longer show your survey id
New Live Form links carry a short random code instead of the survey id, so respondents and panel partners cannot read or guess it from the address bar. Every link already sent keeps working.
Improvement
One panel link, one response
A finished Live Form link can no longer be reused by someone else on the same panel ID. The person who finished still sees "already completed" and their return link. This stops inflated counts and extra incentive costs. Open share links and WhatsApp are untouched.
Improvement
Live Forms handle photos, video and busy moments better
Voice notes, videos and photos on a Live Form are now transcribed or described on their own within about a minute, the same as WhatsApp answers. Open-text questions can take a photo or video. When the server is busy, participants see "One moment..." while the form retries, and a resent answer is never recorded twice. Pausing a Live Form now stops only new people, so anyone halfway through can finish.
Improvement
Translated Live Forms stay in the participant's language
Matrix rows, rating columns and answers show in the language the participant picked. A form reopened in another language comes back in that language with its welcome message, and questions that repeat an earlier answer keep showing it after going back or picking Other. A language question is now saved the same way whatever language the person started in, so reports no longer count one answer as two.
Improvement
Switch a live survey to a web form from the top menu
You can switch a live survey to a web form from the top menu, the same as from Study configuration. Both ask you to confirm and say what happens: people already answering on WhatsApp can finish there, new people get the web form, and automatic reminders stop.
Improvement
AI interviews are cheaper to run and follow your brief
Every AI interview now runs on the newer Claude models, and replies cost about a third less with no slowdown, because your study brief is no longer repeated four times in the instructions. The interviewer also reads all your study settings (topics, target audience, probing, cultural notes) and not just the research objective, and if one AWS region is busy it retries in the other. Question writing, reports, translations, reels, photo checks and trust scoring moved to the newer models too.
Improvement
Draft studies can always move to Testing
A study with unfinished questions can now move from Draft to Testing, so you can share work in progress with testers. The checks that protect real participants still apply at Go Live, where the review panel lists each problem.
Improvement
The platform stays up when it is busy
After the 24 Oct overload, each service now has a limit on how many copies of itself can run at once, and requests fail fast with a "busy, try again" answer after 10 seconds instead of waiting up to 2 minutes. Live Forms retry quietly. WhatsApp entry has no limit, so incoming messages are never turned away.
Fix
Saving the AI interviewer prompt now saves it
Editing the prompt in Settings, then AI Settings and pressing Save showed "saved", but the change was gone after a refresh. It is now stored, and if a save fails you are told.
Fix
Status filters and exports work on large studies
Choosing a status filter such as Completed on a large study, or exporting with one selected, was failing with a 504 error, which showed up on a study of about 3,000 people. It now runs in under half a second.
Fix
Deleted questions leave Graph Data straight away
When you delete a question in Build, it disappears from Graph Data and Table Data without pressing Refresh. Removing simulated responses also removes the simulated people from the Share tab.
Fix
Test Simulator picks the option you were shown
With Randomise options on, typing a letter in the Test Simulator now saves the option you were shown, not the one at that letter in the unshuffled list. Real WhatsApp participants were never affected.
Fix
Smaller tidy-ups across Build and results
Welcome and completion cards, the question Settings icon, the add-question button on interviews, option cards on Create Research, Show more on long transcripts and the Trim button on video reels all behave or look better, and you can now delete an activity or study that has already paid an incentive.
27 changes
New feature
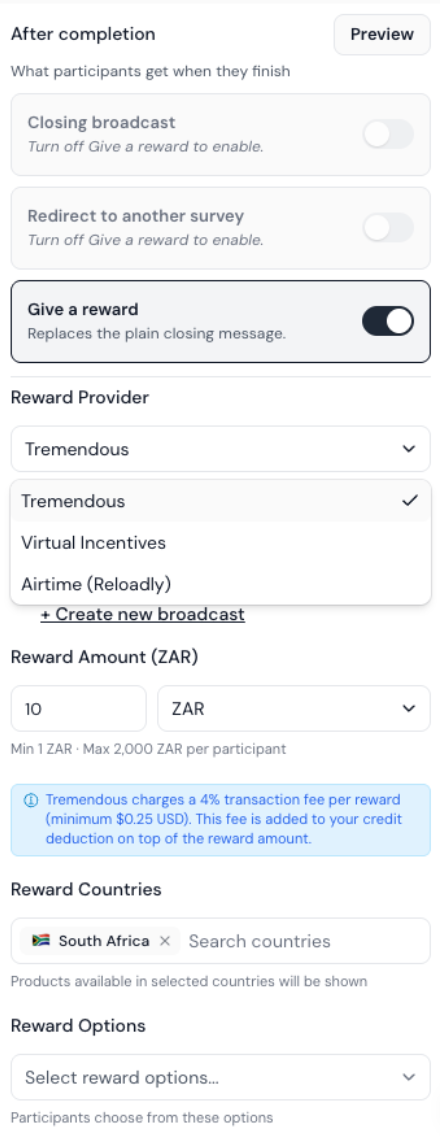
Reward participants with gift cards or cash through Virtual Incentives
You can now reward participants through Virtual Incentives. Pick a country (South Africa, Kenya, Nigeria, UAE, Saudi Arabia or India), then a gift card such as Takealot, Woolworths or Amazon, or cash paid straight into the participant's bank account. Participants get the claim link on WhatsApp as soon as they finish, and there is no message template to set up. Set it under Completion and follow up, Give a reward.
Virtual Incentives in the Reward Provider listNew feature
Reward participants with airtime and data bundles through Ding
Ding is now a reward provider. Pick a country, then airtime or a data bundle per mobile network. When a participant finishes the survey the reward lands straight on their phone, with nothing to sign up for or redeem, and Yazi sends them a thank you message in their language. It lets you reward people in places our other providers do not cover, such as Angola. Tested end to end on a real MTN number.
New feature
Send an image that disappears after a few seconds
A survey question's picture can now go out as a one-time link instead of straight into the chat. The respondent taps a button, keeps a finger on the image to see it, and when the time runs out it is gone for good. Opening the link again just says they have already viewed it. The question is held back until they have looked, so nobody can answer without seeing the stimulus. You write the message and the button wording, pick how long the image stays up (2 to 30 seconds) and decide whether holding is required. The switch now sits on the picture itself, and only shows when the question has exactly one picture. Useful for concept tests under NDA.
New feature
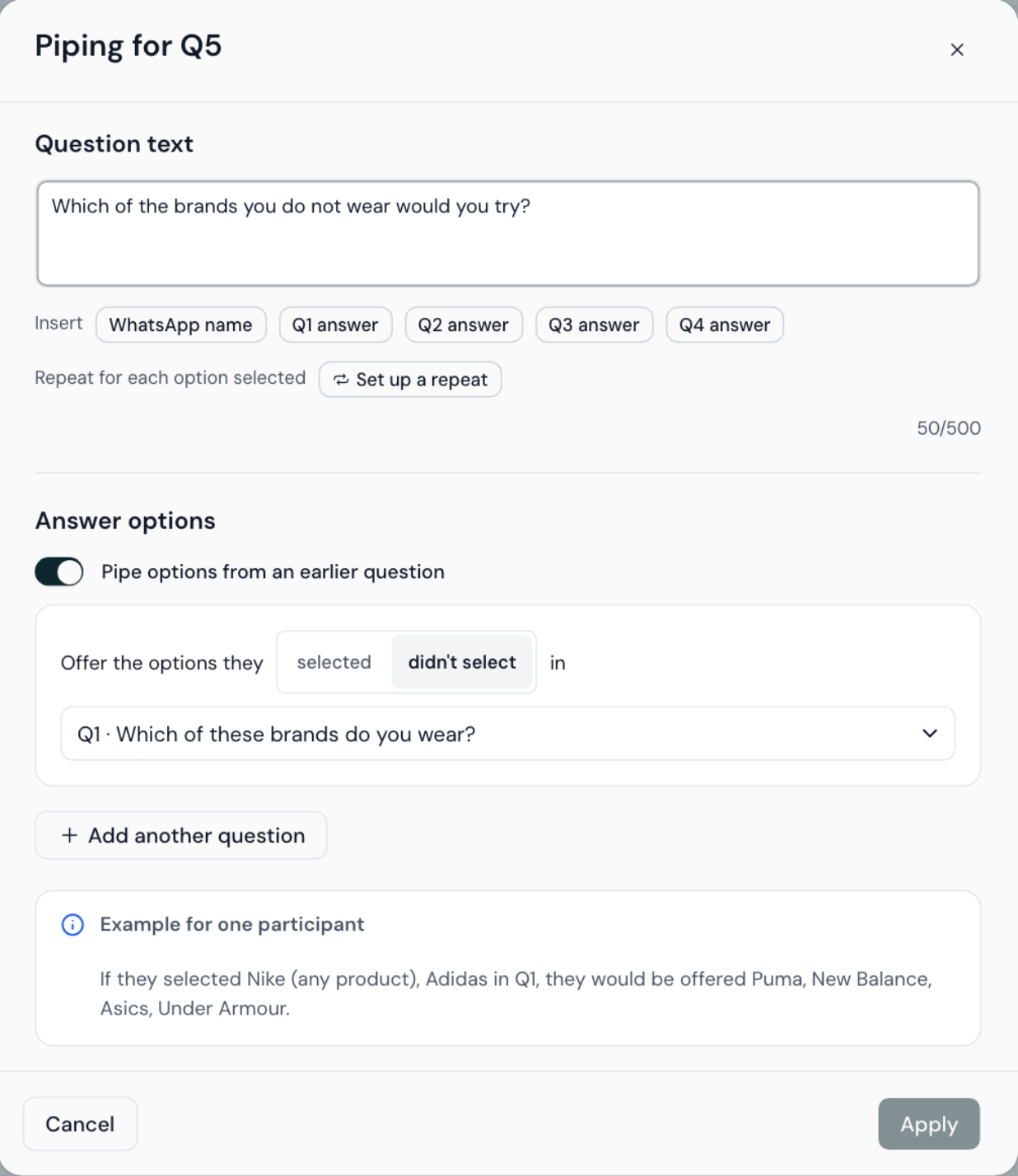
Pipe the answers someone did not pick, and pipe from more than one question
In a question's Piping window you can now carry over the options a participant did not choose, for example favourite brand, then least favourite of the rest. It also chains, so each question leaves out everything picked before it. A question can take its options from more than one earlier question too, such as brands they have heard of but have not bought, choosing selected or did not select for each. One click suggestions cover the common combinations. Questions that pipe from a single question work as before.
Piping window: offer the options they didn't select, with Add another questionNew feature
Limit repeat answers on Live Forms
Live Forms have a new tick box in the setup: one answer per device, and at most 3 from the same internet connection. The same phone or laptop cannot answer twice, even in a private window, and a household or office on shared Wi-Fi is not blocked. People who start from WhatsApp are not affected, and anyone caught sees a short message saying the survey has already been answered. It is off by default. It is a safety net for reward studies shared as a plain link. WhatsApp is still the safest route for high value rewards.
New feature
Reopen a closed study
A closed study now shows a Reopen button where the status button sits. One click puts it back live and it accepts responses again. Before, a study closed by mistake, or one where a client wanted another 50 respondents, had to be duplicated and started over. Group discussions are the one exception: once the room closes it stays closed.
New feature
Music under highlight reels
Highlight reels can now carry music. There are nine tracks to choose from (calm, upbeat and epic). Each plays under the whole video and gets quieter when someone speaks, and it is cut or extended to end exactly on the last frame. There are also short sounds on the opening card, each chapter card and the closing card, with the words fading in alongside. Pick a sound on the Theme step, where you can play any track before choosing it, or choose No sound to keep reels as they were.
Improvement
Panel recruitment now uses your credits
Recruiting through PureSpectrum or Prolific now draws on the same credits as rewards. Launching takes the estimated cost, or your spending cap if that is lower. If you do not have enough, a short Not enough credits window lets you request more.
Improvement
Matrix questions on Live Forms show as a proper grid
On a Live Form the whole matrix now appears under the question, with the scale across the top and the statements down the side. Participants tap one circle per row, can change their mind, and see how many rows they have answered. Send unlocks once every row is done. Before, the statements came up one at a time with the scale stacked underneath like a list. Answers save exactly as before, so results and exports do not change.
Improvement
Live Forms handle pictures, video, audio and other languages properly
Pictures, videos and audio attached to questions now show in Live Forms. Before, participants saw Couldn't load this file. The welcome message is now translated with the rest of the study, so a Portuguese participant is greeted in Portuguese. Live Forms also look better on a phone: questions with many options fit the screen, ticked boxes are clearer, message times sit on the same line as the text, and the Rejoin code bar at the top is gone.
Improvement
Live Forms can show earlier answers, and a paused survey can become a Live Form
A Live Form question can now show only the answers someone picked earlier. Before, the editor blocked this. A survey that is paused or closed can also be switched to a Live Form, so recruitment can change part way through fieldwork. A live survey is still blocked and the message now says to pause or close it first.
Improvement
Prolific recruits can take a Live Form and get paid
People recruited from Prolific can now land on a Live Form and finish it. Before, Prolific's link sent them to an error page. The last screen gives them the button back to Prolific to claim their payment, and that final message now shows in their transcript for everyone sent back to a panel.
Improvement
Translate responses into now works on multi activity studies
Studies with several activities have the Translate responses into setting on the Study tab, and the language you pick applies to every activity. The language settings in Study configuration now say plainly which option translates the survey for participants and which translates their answers for you.
Improvement
Piping opens in its own window, and piped numbers keep up
Piping in the survey builder now opens in a window like question logic: edit the question text, drop in earlier answers and choose which options to carry over, with an example of what participants will see. When questions are added, deleted or moved, piped answers update their question numbers by themselves, in the builder and by Ask Yazi. A piped answer that is not connected to an earlier question shows in red and blocks going live until it is fixed.
Improvement
Routing rules follow when you rename or delete an answer option
When you rename or delete an answer option, the routing rules that use it now update to match, and the pre-launch checklist names any rule still pointing at an option that is gone. You no longer find out about it after going live.
Improvement
The WhatsApp cost estimate uses your country
The cost estimate before publishing used to show South African prices to everyone. It now uses your organisation's own country, with real Meta prices for India, Spain, the Netherlands, Saudi Arabia and the African countries Meta prices separately, such as DR Congo and Mauritius. WhatsApp number health from Meta now refreshes every 5 minutes instead of up to 2 hours, so a warning shows almost straight away.
Improvement
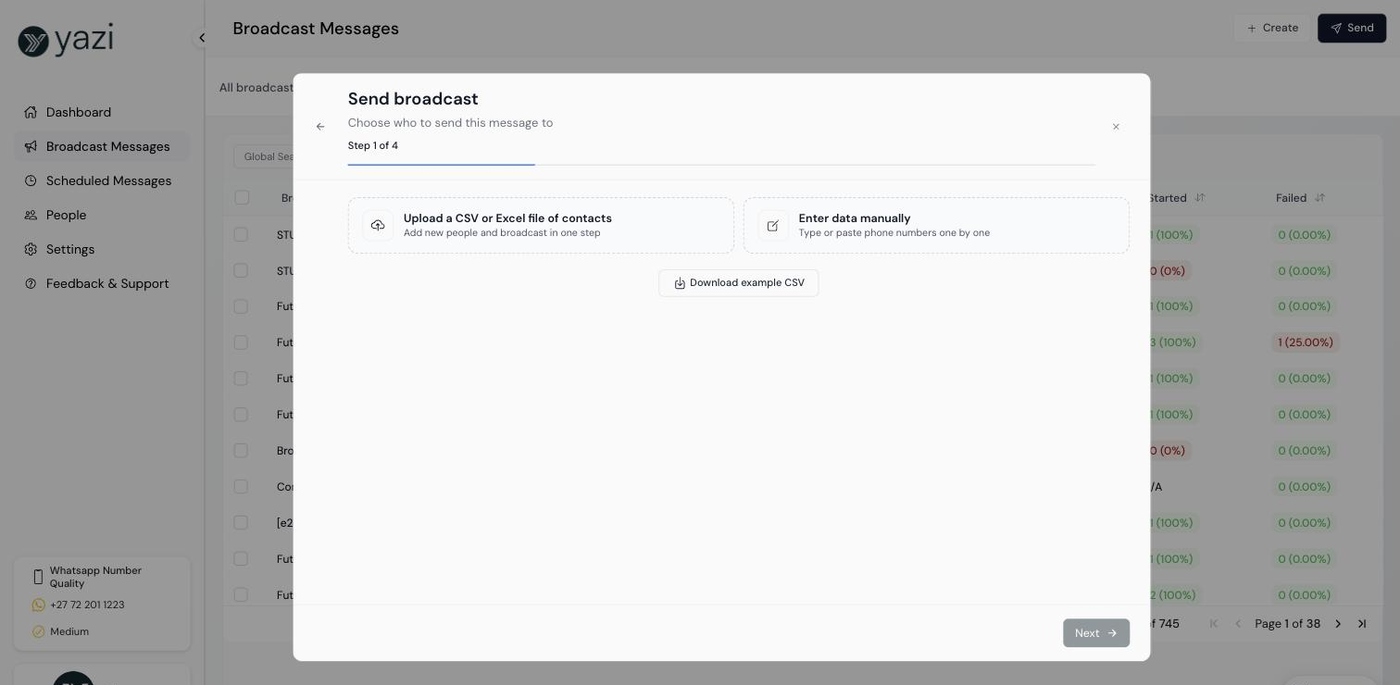
Broadcast Messages table is cleaner
The broadcast name is now a link that opens Edit, like campaign names on the dashboard. Each row has three actions instead of six: Send, Analytics and Delete. Rename lives inside Edit and does not resubmit the template to WhatsApp, so its approval stays untouched. Only the friendly template name shows now, not the technical WhatsApp name.
Improvement
Voice notes play right in Table Data
Voice notes in a study's Table Data now play in the table instead of showing as a link.
Improvement
Reels come out at the length you choose, and quiet voices are lifted
Reels used to come out about 20 seconds shorter than the length chosen. They now land as close to it as possible, which can be a few seconds over. Very quiet recordings are turned up to match everyone else, with background hiss reduced. The editor shows the same name the video prints under each quote. Reels from hand picked videos no longer freeze before the closing card, reels with videos or stock footage share the theme of voice note reels, and regenerating a reel without changes reuses the clips it already made.
Improvement
Ask Yazi knows about the new features
Ask Yazi now explains and points you to where to set up Virtual Incentives, Ding, answer option piping, Limit repeat answers, reopening a closed study, disappearing images, Translate responses into and panel recruitment credits. Asking who is in your organisation, or for an organisation overview, works again.
Fix
Rewards no longer get stuck, and arrive in the right language
Airtime rewards no longer sit on Sending reward while the provider is slow. They are retried after an hour, with no risk of paying twice. If the provider keeps failing, we stop after 5 tries, mark the reward Failed and alert the team. Reward links sent more than 24 hours after finishing now arrive in the participant's own language, including on Yazi's shared WhatsApp number.
Fix
Diary studies handle moving people between days properly
Moving a participant to a later day now removes the queued day they skipped, so nothing arrives out of order. Reset to Activity 1 sends Activity 1 straight away instead of waiting for a Push. Pushing someone ahead and moving them back no longer loses their next day, and the next day is now decided in the timezone you picked in the Schedule window, so someone finishing at 9pm in Brazil no longer gets it a day early.
Fix
Response quality scores fill in for Live Forms and diary studies
With Response quality turned on, the column stayed empty for Live Form studies and for Diary and Recurring Survey studies. It now shows the result, such as Approved, All checks passed.
Fix
Translated surveys show piped answers, screen out messages and completion notices in the participant's language
A Portuguese participant used to see piped answers and repeated sentences in English. Piped answers, screen out messages and the already completed message now follow the language the participant chose. DNA's Arabic translation, which failed during a short outage at our translation provider, is sorted.
Fix
Editing a Live Form no longer hides answers already collected
Changing even one word in a Live Form and clicking Update used to make Responses show nothing. Live Forms with Only show if or end the survey rules can be edited again. A participant who leaves a Live Form and comes back on a question using earlier answers now sees the proper wording and options, and switching a survey to Flow only says enabled when it really saved. Please still avoid editing a Live Form that is already live.
Fix
Transcripts and search behave on every study
Searching a phone number on the Transcripts tab now finds people however far down the list they are, not just the first 25. Surveys built by the AI assistant show their full conversations again, a brand new study no longer says all transcripts have been deleted, and empty Out of 24hr placeholders no longer sit above active chats.
Fix
Multi select answers with commas no longer split in Graph Data
With a filter applied in Graph Data, such as Completed only, options with a comma in the name were split into separate pieces. They now count as one option, and a question that shows earlier picks counts each option once whatever language people answered in.
14 changes
New feature
Recruit paid participants from Prolific and PureSpectrum without leaving your study
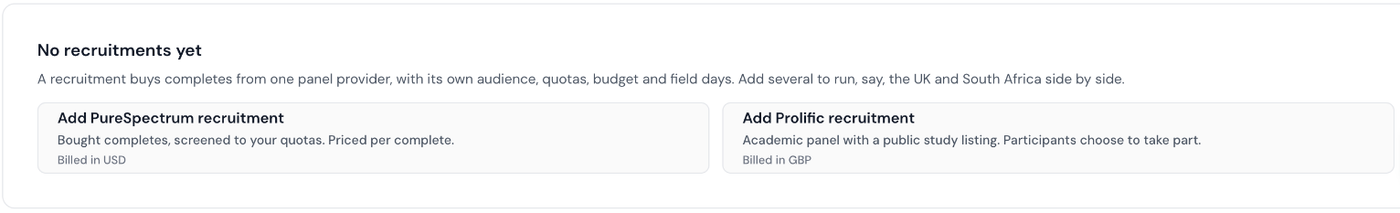
The Panel Recruitment epic is live on production. From a study's Share tab you can recruit paid participants from Prolific, PureSpectrum or Meta ads, and run several recruitments on one study, including several from the same provider, each with its own name, audience and budget. Audience options now come from each provider's own list, country by country, with costs in the provider's real currency (Prolific in pounds, PureSpectrum in US dollars). You set one incentive in the study builder: Prolific uses it as the reward and warns you if it is below their minimum pay. Prolific completes are approved automatically and the participant gets a get paid button as their last message. People without WhatsApp are filtered out on a handoff page before they cost you anything, and you can exclude earlier participants so a second wave does not recruit the same people. The Responses table shows Recruited from and Recruitment for every participant, including in the CSV export.
Panel Recruitment on the Share tab: add a PureSpectrum or Prolific recruitmentNew feature
See what Meta will charge before you publish
Before you publish or update a survey or study, you now see what Meta will actually charge for the WhatsApp messages, split into the broadcast invite and the survey questions. When a study can run as a WhatsApp Flow, there is a one click option to switch to the cheaper Flow format. It covers the US, Canada, the UK, South Africa, Germany and Brazil, and says plainly when it is giving a rough figure for anywhere else. It also now works for multi day studies, not just single surveys.
New feature
Send a voice note from a takeover
During a human moderator takeover you can now record a voice note, play it back and send it. The participant gets it on WhatsApp as a normal playable voice note, not a file. It is a slim recorder in the message box, and you send either a voice note or text, never both at once. Held chats also now sit in a slim strip at the top of the takeover list and the dashboard, with Open chat and Release right there, instead of an Active Sessions pop up. The Out of 24hr badge in the chat list now reflects what the participant actually sent, so you can trust the list without opening each chat, and someone who has just messaged a study's starter phrase can be chatted to straight away.
Improvement
Voice note transcripts follow along word by word
When you play a voice note or video on the results page, in a participant's transcript, in the full screen player, on a shared results link, in the Media Library or in the reel preview, the transcript now highlights each word as it is spoken, and clicking any word jumps the recording to that point. It works for voice notes recorded from 7 October onwards. Older ones show the plain transcript as before.
Improvement
Highlight reels: your own colours and wording, and they build twice as fast
You can now mix your own colours for a reel, a background for the heading cards and for the voice note clips, with light or dark text and a live preview. On the Theme step you can also write the opening title, a short description and the closing title, rename chapter headings and put up to three logos on the reel. Reels built with stock footage no longer carry the question card on every clip, and reopening a hand picked reel keeps your headings. The Left out list says Not picked instead of calling nearly everything Low signal. A clip with nothing audible in it is now skipped with a note instead of leaving the reel stuck on Processing. Reels now build in about half the time, 9m51s down to 4m29s on a real reel, and uploaded logos show at the same size whatever the file size.
Improvement
Run Simulation tests WhatsApp Flows the way a phone does
Run Simulation used to quietly test a chat version of a Flow survey, so Flow problems could not show up. It now builds the screens a participant would see, fills them in and checks every step is a real screen, including studies that mix chat and Flow steps and Flow surveys that lead into the AI interview.
Improvement
Surveys with many follow up questions now send as Flows, and failures say why
Surveys with a lot of follow up questions in a row could not be sent as WhatsApp Flows at all, so everyone got the slower question by question chat. They now send properly, and follow ups that do not apply to someone are left out rather than asked. When a survey is still too complicated for a Flow, the app now names the questions causing it instead of saying the update failed. On single form Flow surveys, answer options are now shuffled for each participant when Randomise options is on, and a custom None of the above wording comes through in the participant's own language. A study picks this up the next time it is published.
Improvement
Participants choose their language once in a multi day study
In a multi language study, participants picked their language on day 1 and were asked again at the start of every later activity. They now pick once and every later activity starts straight away in that language. If an activity does not offer their language they are still asked. A study that had translations on and its own language question also no longer asks twice in a row.
Improvement
Building long multi activity studies is quicker
Clicking into an activity with 80 or more questions took 6 to 7 seconds. It is now well under a second on a normal laptop. The question preview in the Build tab is also taller, so you see around seven answer options at once instead of two and a half, and it sits inside the phone frame like it does on a real phone.
Improvement
Receipt and menu photos are read by Claude in the EU
The service that reads diary receipts and menu and price photos now uses Claude, running in our own AWS account in the EU, instead of Google Gemini, which is being retired on 16 October. It is about five times faster per image. CSV exports and price data keep the same format.
Fix
The completion message arrives before the next activity starts
In a multi activity study, the Survey completed successfully message for the activity a participant had just finished could arrive after the next activity's first question, so it looked like the new question was already completed. Participants now see their activity confirmed first, then the next one begins.
Fix
Translate to English exports are right
Exporting an AI interview with Translate to English gave the same file as Leave as written. It now gives English answers in the main answer column, in CSV and Excel, with or without a filter. For closed questions (pick one, pick many) the export now uses the study's own scripted wording in every language instead of running it through AI translation, so Self-employed no longer comes back as a different phrase in each country and results line up across countries. Open answers still get AI translation. The fraud column that showed [object Object] in every cell is gone, replaced by a readable trust status (Approved, Flagged, Rejected, Not yet scored) with the reason where there is one.
Fix
A failed WhatsApp link no longer strands a half finished survey
When a survey link failed to send, the participant got nothing and their half finished survey was parked with nobody told. That hit 37 people on one Tuesday. Their survey is now put back exactly as it was, the team is alerted with the real reason from WhatsApp, and the step that moves someone between activities retries instead of skipping them. Removing someone from a whole study now also works for people who were only added to individual activities.
Fix
Smaller fixes
Text typed right after adding a question is no longer lost. The Classifying themes message on the Responses table stops as soon as the system knows the answer, and a study with only test responses says so plainly. The Test Simulator's buttons and instructions now show in the participant's language across all 20 platform languages. A highlight reel on an organisation with AI turned off now says so straight away instead of failing with no reason. New organisation names are tidied automatically so they are all named the same way.
15 changes
New feature
Request to chat: reach a quiet participant after 24 hours
WhatsApp only lets us send free text within 24 hours of a participant's last message. After that, a moderator could still type in the takeover screen, but the message never arrived. When a chat is outside that window the takeover screen now shows a Request to chat card. One click sends the participant an approved WhatsApp message with two buttons, Accept and Opt out. If they accept, you see it straight away and can connect. Opt out is a real opt out. If your organisation does not have the message yet, Yazi creates it in English or Portuguese, waits for WhatsApp to approve it, and sends it for you.
New feature
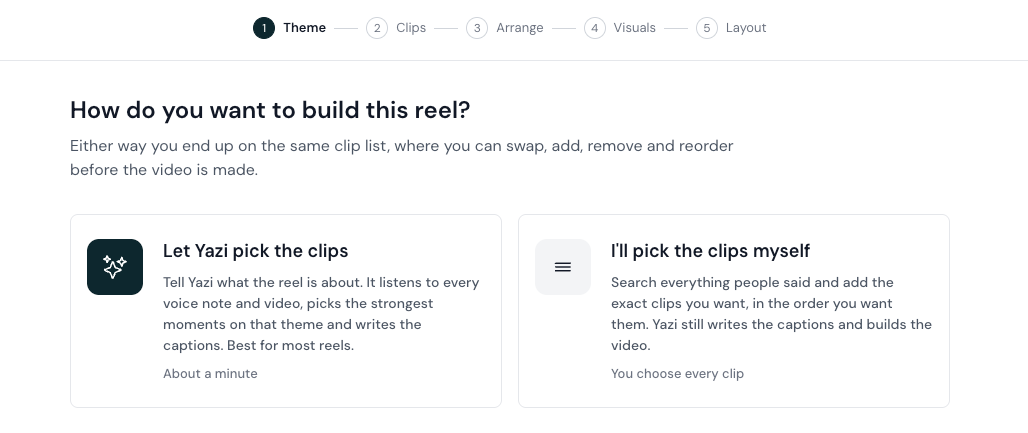
Video reels in a designed theme
When you build a reel by hand there is a new step asking how it should look: a theme, or stock footage as before. A theme puts the whole quote on screen and fills it in word by word as the person speaks, over a clean dark or cream design. There is nothing to set up and it comes out the same way every time. Reels made entirely from voice notes now use the theme automatically. Where a study hides participant names, no name appears on the video.
Improvement
Human moderator takeover is steadier
Takeovers no longer get stuck or cut you off. Starting a survey, tapping a start button or typing the study code now ends an old takeover automatically, so a participant is never left talking to a screen nobody is watching. A takeover now hands the chat back after 60 minutes with no moderator activity, with a warning at 45 minutes for each chat. The old blunt two hour timer is gone, so you are not cut off mid conversation. A short wifi drop reconnects by itself with a Connection lost banner, a hidden browser tab keeps the takeover alive, and updates to the chat service no longer end live takeovers. While you hold a chat, everything the participant sends reaches you, never an automated reply. Buttons, list choices, forms and stickers show as readable text instead of a blank bubble, and the Handed back notices are one compact list.
Improvement
Reels keep your clips and tell you when a video is on its way
If you hand pick the clips for a reel, it now keeps every clip you chose. Before, it could quietly drop all of them and give you a 5 second video with your clips listed as left out. Adding a clip to a reel you already made now saves instead of throwing an error. Pressing Generate video now shows a message that it is on its way, with a button that takes you to it. A reel that said render failed when it had worked is fixed. New reels get a real name written for them, such as "Borrowing to Bet: Gambling's Debt Spiral", instead of every reel being called Standout voices, and trimming a clip can be undone when you come back. The question caption no longer sits on top of the person speaking, the bars around the player are black so full screen looks like a normal video player, and renaming a reel no longer empties the player.
Improvement
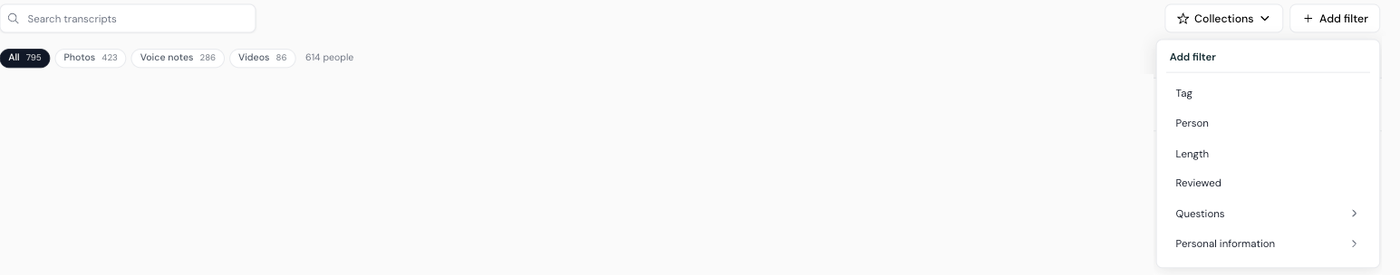
The Media Library shows every photo, and you can refresh it
When a participant sent four photos in one answer, the Media Library showed one tile and counted one. It now shows every photo with the right count, and each photo can be tagged and starred on its own. Nothing already tagged or starred was lost. Counts in the Media Library will read higher than before for studies with multi photo answers. There is also a Refresh button at the top right, next to Add filter and Download, that pulls in anything that arrived since you opened the page while keeping your filters and stars, and an empty library has a Check for new media button that says when it last looked. A new first photo or voice note now shows up in seconds instead of up to five minutes. Clips carry the person's WhatsApp name straight away instead of "Participant 3fa4b1c2" for the first half minute, and Show transcript now appears on studies with anonymous respondents.
Improvement
Translations keep up when you change the wording
If you reword a question, an answer option or a text only question, its translations now refresh when you publish, and only the questions that changed are redone. Before, respondents kept getting the old wording in other languages with no warning. Publishing a study in several languages is now quick: one multi country survey timed out 13 times in two days because publishing redid all the translation work each time. If one language fails, the others are kept and the status reads Partly Translated, rather than losing all of them. The Translating box names every language at once, adding a matrix column gets it translated, the Generate translations button works after you reword a question, and the false "translations out of date" warning on photo, voice note and number questions is gone. Pasting a batch of translations into Ask Yazi no longer fails part way. Hand written translations are never overwritten.
Improvement
A clearer Send history for Scheduled Messages
Send history, under the clock icon on a scheduled message, has been redesigned. The old version broke a send into hundreds of small batch tags that pushed everything else off screen. Sent, Delivered, Read, Awaiting, No receipt and Failed now show as cards in the same style as Broadcast history on a campaign's People tab, and clicking a card shows only those people. One coloured bar shows the whole send at a glance, batches show as a small chart with failures in red, and failure reasons are in plain English. The recipient list is bigger, 25 people a page, with the full reason on each row. People WhatsApp will not deliver to now show a plain Not delivered warning that says retrying will not help and to share the link another way, in English and Portuguese.
Fix
Photos and videos sent together land on the right question
When a participant sent several photos, WhatsApp sometimes delivered them a few seconds apart. The survey had already moved on, so the later photos were turned away and never saved. Late photos now join the photo question they belong to, counted from the moment the participant pressed send rather than when our system got round to it. A video sent in the same upload as late photos is saved as the answer to the video question instead of being lost. Photos no longer get saved twice against the wrong question, and every late photo gets its written description. If one photo in an album does not come through, the participant is told exactly that and can resend it, instead of getting "Sorry, we couldn't read that" in the middle of the upload. We also recovered 27 photos and videos that had been lost earlier, so no one is asked to resend.
Fix
"Only show if" works in WhatsApp Flow studies and uploaded questionnaires
In Flow studies, "Only show if" conditions were never checked, so every participant saw every screen. Flow studies now skip screens that do not apply, the same way chat surveys do. Separately, when an uploaded questionnaire or an Ask Yazi edit said "Ask Q19 only if", the rule was placed on Q19 itself, so it ran only after the participant had seen it, and rules covering several earlier questions were cut down or dropped. Those rules now go on the right question, cover every earlier question they name, and take effect straight away without saving the study in the builder first.
Fix
Hindi, Turkish and other languages get their own wording on system messages
A handful of survey messages came through in English for Hindi and Turkish respondents, such as "you've already completed this study" and the prompt after picking an option that is not on the list. They now show in the respondent's own language, and the same fix covers Zulu, Xhosa, Afrikaans, Arabic and Swahili. A custom "None of the above" or "All of the above" wording now shows in the respondent's language too, where before it forced English. The Hindi and Turkish wording was written in house and has not had a native speaker check yet.
Fix
Changing the list on a scheduled broadcast no longer breaks the send
If you change the uploaded list on a scheduled broadcast, the app now checks that the new file still has the columns your message needs and tells you which are missing. Message variables that pointed at a column the new file does not have are cleared, with a note saying which ones to pick again, and you cannot move on until you have. Variables that still match are left alone. Before, it kept the old column names and quietly turned them into fixed text, so a message meant to greet someone by name would have sent the word "name". A schedule already stuck in that state now stops with a clear reason instead of retrying a send that cannot work.
Fix
Sent only means sent, and transcripts show the real broadcast
When WhatsApp refused one of our messages we were still recording it as sent: rejoin codes, form links, completion messages, campaign invites and room closed notices. A participant who never got their link looked like they had. We now only report sent when WhatsApp accepted it. All five of those messages are now recorded against the participant and the study, and when you open a participant's transcript the broadcast we sent shows the real heading, wording and button instead of a small note that something was sent. A question the bot sent that the participant never answered now also shows on the takeover screen, and stickers in AI interviews show their picture. Counts of sent messages can read lower than before where WhatsApp had refused them.
Fix
The AI interviewer no longer sends its own notes or invents languages
About one in a thousand AI interviews opened with a note meant for the research team, such as "Here's a natural opening question to kick off the interview:", and the participant saw it on WhatsApp. The interviewer now treats everything it writes as going straight to the participant, and a safety check removes any leftover note before a message is sent. Separately, short or quiet voice notes in AI interviews were sometimes transcribed as Japanese, Chinese, Hindi or Arabic text the participant never spoke. Voice notes are now matched only against the languages the campaign uses, plus English, Afrikaans and Zulu for South African participants.
Fix
Studies no longer vanish from your dashboard
Studies were sometimes disappearing from the dashboard and coming back on refresh, and a few people hit it over two weeks. When the app briefly could not confirm who you were signed in as, it treated that as an account with nothing in it and showed the new user welcome screen. It now keeps showing what you already had.
Fix
Smaller screen fixes
The first time someone opens a survey's Build tab, the seven step walkthrough now moves on with one click per step instead of two or more. The Responses table fills the width of the screen and the search box lines up with the rest of the page. Long labels on button style tabs, such as in Portuguese, wrap instead of overlapping, and the AI study creator's proposal card no longer squeezes its settings. The Tell Yazi what to change box in the AI study creator grows as you type, up to about six lines. The Transcripts list no longer shows blank rows on tablet and phone widths.
36 changes
New feature
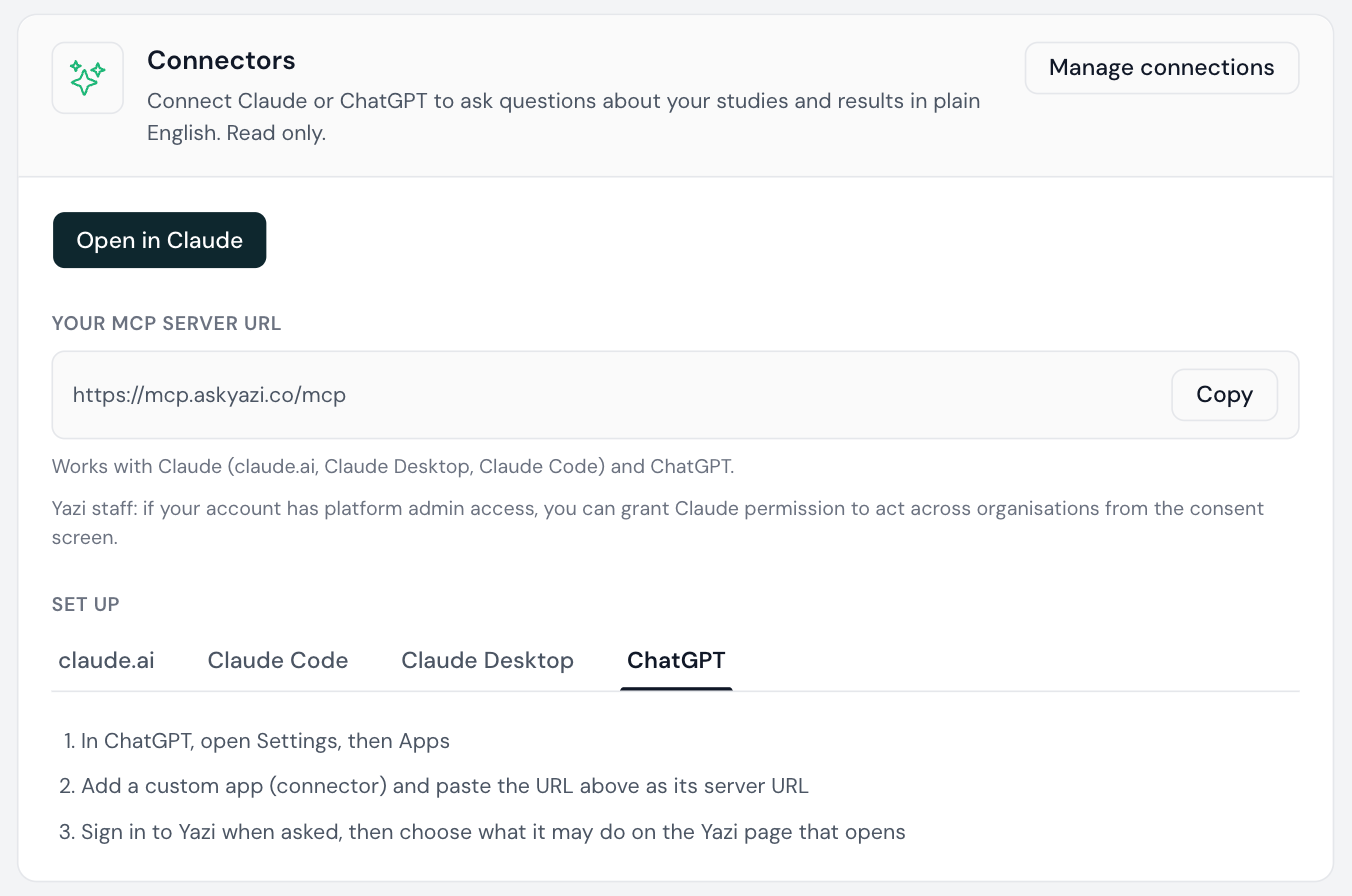
Connect ChatGPT and Codex to your Yazi data, not just Claude
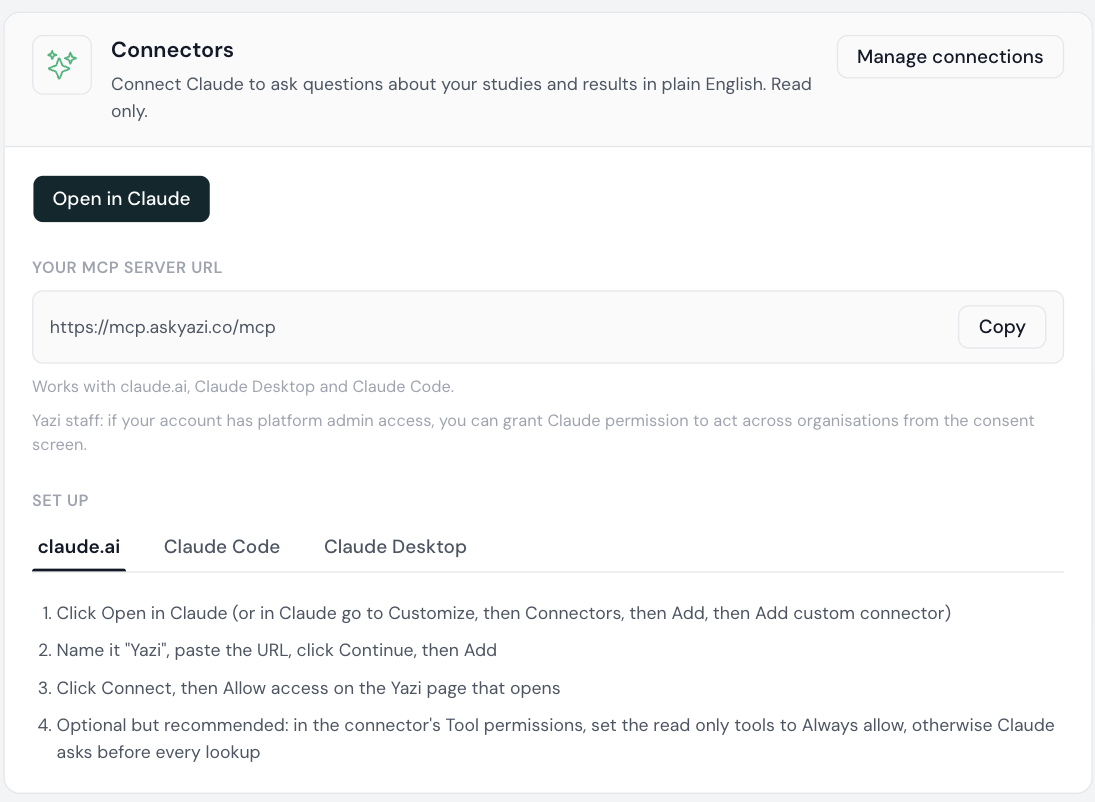
The Yazi connector used to work with Claude only. You can now connect ChatGPT and Codex the same way and ask questions about your studies and results in plain English. Settings, Integrations has a ChatGPT tab with three steps: open Settings then Apps in ChatGPT, add a custom app with the Yazi server address, and sign in to Yazi to choose what it may do. The sign in page now names the app you are actually connecting, rather than always saying Claude. Access stays read only, you can revoke it any time, and no security protections were loosened to make this work.
Settings, Integrations, the Connectors card with the MCP server address, the note that it works with Claude and ChatGPT, and the ChatGPT set up tab with its three stepsNew feature
Let Yazi make the whole video
"Let Yazi make the video" used to stop at a list of clips you had to come back and finish yourself. It now does the whole job: it listens to the voice notes, picks the strongest moments, adds stock footage, writes the captions and renders the finished video in one go. You can still open it afterwards and change anything. Long videos are now made in two shorter steps, so a long reel can no longer time out halfway and leave you watching a spinner, and if the second step hits a problem the first step's work is kept. Editing a finished reel, swapping a backdrop, changing the layout or reordering clips, is much quicker because only what changed is rebuilt. Reels where you hand pick the clips now get a proper AI written title too, the same as the ones Yazi picks.
New feature
See exactly what happened to every scheduled message
Each scheduled message now has a Send history view, under the clock icon in the Actions column of Scheduled Messages. It shows how many messages were sent, delivered, read and failed, and how many are still waiting, broken down by send batch or by day. Failures are grouped by reason, and clicking a reason shows who it affected. There is a searchable list of every recipient with their status, and a CSV download. The Progress column also shows failures now, as a red "N failed" beside the sent count. Before this a schedule could read 3,019 of 3,019 sent while 505 of those had failed, with no way to see who missed out or why. It is visible to anyone allowed to export personal data, and organisations that hide phone numbers see participant IDs instead.
Improvement
Build reels from videos, and add clips to a reel you already made
Highlight reels can now be built from videos in the Media Library, not just voice notes. Before, picking videos left the button greyed out, and a mix of videos and voice notes quietly dropped the videos. A question answered only with videos now shows up in the list of questions you can build a reel from. There is a new Add to reel button, so a selection can go into a reel you have already made instead of only starting a new one, and pressing Create a reel on files you ticked now opens straight on "Put them in order" rather than showing the whole library again. Building a reel from someone's very long answer no longer fails outright, and the clip editor shows the first 300 words with a "show all" link. A few smaller fixes went with it: the layout buttons read in full, a backdrop you picked shows its picture again when you come back, Yazi remembers you asked for stock footage even if you close the editor while the reel is building, and long transcript text stays inside its box.
Improvement
Transcripts now show the whole WhatsApp conversation
Until this week Yazi only stored half of every conversation. We saved what participants said, and the app rebuilt the questions around it by guessing. Transcripts now show what was actually sent and received, at the time it actually happened. The bot's questions are saved with their real send time, so you can see how long someone took to reply, which on one participant ranged from 6 seconds to 4 minutes where it all used to read as zero. Broadcasts are saved and look the way WhatsApp showed them, with the logo, long messages folded behind "Read more", and the button the person tapped greyed out as used. Broadcasts sent before July also show their real text now, 6,760 of them. The code someone texts to join, the answer they typed when it was rejected, the bot's "please reply with a number" message, thumbs up reactions, round video notes and stickers all appear where they happened, in their own speech bubbles, and in the right order. Duplicate copies of invites and questions are gone, and the "Added to campaign via Link" note is gone because the joining message now speaks for itself. Our messages are green on the right and the participant's are white on the left, the way WhatsApp does it, everywhere a conversation is shown. None of this changes answer counts or exports. Older conversations keep their gaps where those messages were never stored.
Improvement
The Transcripts list is a table, and big studies open quickly
The Transcripts list on campaigns and studies now reads like a table rather than a stack of cards, and each row leads with the participant's name where you are allowed to see it. Studies with Privacy Protection are unchanged. On a 1,300 person study the list used to put over 200,000 elements on the page and could hang; it now puts about 22, however long the list is, and rows start showing in under 20 seconds instead of sitting blank for a minute. Hovering a row now highlights the whole row and the time no longer gets cut off. On a multi activity study the transcript also shows the date each activity started, above "Activity 1" and again whenever the next activity begins on a different day.
Improvement
Reach people outside WhatsApp's 24 hour window on any step
When someone has not replied on WhatsApp in the last 24 hours, the normal in-chat message for the next step of a study cannot be delivered. You can now set a backup broadcast message on any step of a study, not just scheduled ones, and it is used automatically when the in-chat message cannot get through. If a broadcast really cannot reach someone, because the window is closed and no backup is set, it now says so instead of claiming it was sent. Sending someone an activity they have received before now actually goes out again.
Improvement
Scheduled activities wait for the participant to tap Continue
When a scheduled next activity started, participants used to get "Your next activity is ready" and its first question at the same moment, so the Continue button did nothing. Outside WhatsApp's 24 hour window Meta also rejected that question, and inside it the question could arrive twice. A scheduled activity now sends only the invite, and the first question arrives once, when the participant taps Continue. That holds for diary days, people already partway through a study and late joiners. A study can no longer go live with a scheduled invite that has no Continue button, and the invite picker only offers ones that do. Activities set to start straight away are unchanged.
Improvement
Question logic can send people to the start of a block
A question logic rule can now route a respondent straight to the start of a block. Before, sending someone to a whole section meant finding and naming its first question by hand. Nothing else on the Question Logic screen changed.
Improvement
Send a broadcast to one activity in a study
When sending a broadcast from a study, you can now pick any single activity in it, such as Activity 2. Before, only the whole study showed up. Adding someone to a study without reaching out to them yet no longer breaks the Push and Set activity buttons.
Improvement
The Build page warns before Meta account problems reach participants
Matrix, multi select and rating scale questions reach people as interactive WhatsApp forms, which only work when the WhatsApp account is fully verified and in good standing with Meta. When it is not, a matrix question never arrives and the person is stuck on the question before it, with nothing in the builder to explain why. The Build page now warns you the moment you add one of those questions on an affected account, names the ones you have used, explains what people will actually receive, and shows in red where a question cannot be sent at all. It is a warning, not a gate; you can still publish.
Improvement
Test simulations are useful end to end
Simulated people are now built from the study's own screening rules, so they qualify instead of being screened out on the first question; on one Cape Town study 136 of 142 had been answering that they lived elsewhere. They fill in matrix questions properly instead of looping on them until the run timed out. A simulation shows in the study's own progress panel and walks the whole study, simulated people count as completed in the Participants view, and nothing is ever sent to anyone. Simulated responses now show in the results table with a switch to hide them, the AI write up hides and returns with them, diary studies get the same switch, and a study whose responses are all simulated can be exported, with a "Simulated" column on any file that includes them. Runs from before this week stay as they were; remove the simulated data and run again to see it.
Improvement
The AI interviewer hears the survey's last voice note
When a survey ended on a voice note question and handed over to an AI interview, the interview started a second after the voice note arrived, but the transcript took another 5 to 15 seconds. So the interviewer's first message went out before it could hear the answer, usually the richest one in the survey. The interview now waits up to 45 seconds for the transcript and picks up from what the person actually said. If transcription fails, the interview still starts.
Improvement
Read any participant's transcript from a study's Share tab
On a multi activity study you could only read a participant's transcript after filtering the Share tab to one activity. Now you click a participant and each activity they took part in has a View transcript button. The transcript opens grouped by activity, with buttons across the top to jump between them.
Improvement
Choose a reward country by typing
Picking the reward country on a campaign is now a search box. Type a few letters to find the country, each shown with its flag and dialling code. The list of countries is the same and existing campaigns are untouched.
Improvement
Recurring Survey results load like every other campaign
On a Recurring Survey, the Responses tab showed a progress bar that always froze at 98% while it loaded. It now shows the same placeholder as every other campaign type, and Refresh keeps the table on screen while it reloads instead of blanking the page. The Group by dropdown has gone; on recurring surveys it did nothing except switch off search and column filters.
Improvement
No more floods of "sent immediately" emails
When a participant reached a scheduled activity after its send time, the study owner got an email. On multi activity studies it fired again and again, eleven times in one day on one study. It is switched off. Participants are unaffected and the warning on the study page stays; a single batched summary will replace the email later.
Improvement
A run of visual tidy ups
The date box showing when the next activity starts no longer cuts the date off. The Inputs and Tracking tabs in quota settings are no longer half hidden behind the header. Share tab status labels use the same colours as the activity cards above them. The duplicate a study and duplicate a campaign boxes show the full title at a normal size. Loading placeholders on Transcripts, the dashboard and study panels now look like the screen they are about to become. The Settings search box and the tabs above a transcript are back to full size. Dropdowns no longer flash blue, search boxes show one clear button instead of two, long dropdown lists show a scrollbar, and the Participants tab no longer shakes on Macs set to always show scroll bars.
Fix
Searching inside answers on Transcripts gives the full answer
Searching inside answers on the Transcripts tab could quietly come back short. If one of the requests that loads the participant list failed, the app treated it as the end of the list and answered from whatever had loaded. On a 1,300 person survey it reported 40 matches when the real answer was 1,044, and the number changed every time. It now retries, loads everyone before answering, and tells you if it still could not. The same fault could hide the Load more button or blank the list entirely; those are fixed too. Searching is faster, reads a fraction of the data it used to, and searching by phone number no longer labels the result as a match inside someone's answers.
Fix
The Send broadcast screen does what it shows
Three ways the Send broadcast window could trap you are fixed. Creating a new template from inside the window used to leave you on a screen where Send did nothing; one client sat on it for hours. The window now closes, tells you the template has gone to WhatsApp for approval, which usually takes a few minutes, and keeps the people you picked selected. Clearing the Campaign or Study box used to leave the old campaign quietly selected, so a message could go to a campaign you thought you had removed; clearing it now clears it, and Next stays off until you choose one. The batch name field looks like something you can type in, the Broadcast Name box is wide enough to read, and you can type to find a template instead of scrolling the whole list.
Fix
Scheduled study invites go out once and show as one send
On multi day studies a scheduled invite for a later day was listed in Send History once per participant, so a cohort of 283 showed as 283 separate "Sent 1" rows, and participants got the invite twice a few seconds apart. Each scheduled invite now goes out once and shows as a single send with its real totals and delivery rate. Studies that ran between 22 August and 28 September have been tidied up the same way, and an Opt in or Opt out tap is now recorded against the exact message the person tapped. People who received a broadcast also appear properly in the campaign transcript afterwards, where a timing gap used to leave their entry empty.
Fix
Graph Data loads on the largest surveys
The Graph Data tab would not load on our largest surveys and showed an error instead. The same failure hit large pages 114 times in the past month, on most working days since 14 September. It is fixed, and other places where big result sets failed to load should be clear with it.
Fix
Photo heavy diaries sync in full to Excel and Google Sheets
On diaries with lots of photos, each photo's AI description was written into the spreadsheet cell alongside its link, which pushed cells past Excel's size limit so answers were cut off, and made Google Sheets reject the sync entirely. Photo cells now hold the short links and captions, nothing is cut off mid answer, and large studies sync in full to both.
Fix
Table Data downloads include what you are looking at
On a study's Table Data tab, searching, filtering or selecting rows and then downloading Excel or CSV used to refuse with "No data to export", even with matching rows on screen. Downloads now contain exactly the rows you are looking at. The participant profile columns, name, age, gender, city and so on, are also hidden by default on study results the way they already were on campaigns, so the answers are not pushed behind four empty columns. They are still in the column picker, and a column layout you saved yourself is left alone.
Fix
Interview activities in a multi activity study save again
If a study had more than one activity and one of them was an AI interview, nothing in that interview could be saved, not the title, not the completion message, not its settings. Every attempt failed with "Something went wrong". Surveys in the same study saved normally, which made it look intermittent. It is fixed on production, so anyone who could not save an interview activity this week can go back and try again.
Fix
The question percentage counts up the same way through survey and interview
On studies that run a survey into an AI interview, the two halves disagreed about the progress percentage. A participant could see nothing on the early questions and then "47% complete" once the AI took over, which reads like the conversation has restarted. It affected 192 live interview studies. Both halves now follow the one "Hide Question Percentage" setting in campaign Settings: the percentage either shows the whole way through and counts up steadily, or never appears.
Fix
A participant is no longer stuck after a human takeover
If someone took over a WhatsApp conversation from the AI and closed their browser without clicking End chat, that participant was stuck for good. Nothing they said reached a survey again and no campaign could reach them. The conversation now frees itself after two hours, and the team gets an alert long before that.
Fix
Completion messages arrive in the language the participant picked
On one study, English speaking participants received the completion message in Arabic. The study's default language had briefly been set to Arabic, the translator saved Arabic text as the English version, and nothing cleared it when the default went back. Participants now always get the message the researcher wrote, in the language they chose, a wrong language translation can no longer be saved, and a daily check alerts us before a participant could see one.
Fix
The "someone else is editing" warning means it
The warning that another person is editing a study kept appearing while people worked alone, on AI interview activities sometimes just while typing. The check behind it was tied to a timestamp that about a dozen unrelated things also change, such as translation status, quotas and AI analysis. It now moves only when the questions themselves change, so the warning only appears when a different person really is editing the same study.
Fix
Join codes for studies not yet live get a reply
Sending the join code for a study that was not set to Live got no reply at all, not even an error. 41 studies were in that state. A closed or paused study now says so, and one still in testing says it is in testing and then starts.
Fix
Privacy Protection holds in the combined study transcript
On studies with Privacy Protection, the single activity transcript hid participants' names and numbers, but the combined transcript across all activities, on the Responses and Share tabs, showed them. It now hides them for every protected activity, along with the transcript title, the export file name and the media viewer.
Fix
Signing in no longer leaves the app unusable
Our login cookies held the full sign in tokens, about 4 KB on every request. Add analytics cookies and some browsers crossed the size limit our hosting accepts, so people could log in and then nothing on the platform would load, with a "Request Header Fields Too Large" error. The tokens now stay on our servers and the browser keeps a short session id, so cookies dropped from about 4 KB to 123 bytes. Sign in works exactly as before and nobody was signed out. Separately, a busy office sharing one internet address could briefly be blocked from loading the app; that limit has been raised about fivefold.
Fix
The rewards approval list is easier to read
Ticking several people in the rewards approval list used to float the approve and decline bar over the names; it now sits at the top of the list. Each person's green tag reads "Trust score 64" instead of "Approved 64", so it is not mistaken for the payment being approved. Two side effects of last week's reward retry change are fixed too: simulated test people no longer retry over and over, and anyone who misses out on a first come voucher gets the "sorry, you were not in the first 100" message again. No real reward was affected.
Fix
The Participants list tells the truth
Around 380 people who had opened a survey link but not answered yet showed as "Unknown". They now show as "Delivered", which is what happened. The status counts along the top of the list could disagree with the table and now always describe the same people. Removing people from a study clears the selection straight away and confirms in the corner, instead of looking like nothing happened and then warning it was taking too long. A finished participant's progress bar is green rather than orange, and the participant list for a single activity in a study now has the Reason column that explains why someone was flagged.
Fix
Panel recruitment shows the provider you picked, and PureSpectrum completions count
Opening a provider's set up screen in Panel Recruitment, such as PureSpectrum, still offered a picker to switch to another provider, which made it easy to configure the wrong one. It now shows only the provider you clicked. Two PureSpectrum completion links were also missing the security signature PureSpectrum requires, which meant a completion could be silently rejected and nobody credited; both are now signed.
Fix
Dashboard and account fixes
The Dashboard sometimes showed the "create your first study" screen to people who already had studies, until they refreshed. That is fixed, and an expired session now signs you out cleanly instead of hanging half logged in. Someone who creates a new organisation now appears in its own Members list.
24 changes
New feature
The Media Library is rebuilt around how you actually review media
Every photo, video and voice note from a study now sits in one library on the Responses tab, grouped by activity and question, instead of a separate folder per question under Reporting. It works the same way on a single interview. You can tag a clip, star the ones worth coming back to and mark the ones you have been through, and the whole team sees the same tags and stars rather than each person keeping their own. Tags can be set up before you start and applied as you go. You can narrow to photos, voice notes or videos, filter by activity, person, tag, length or question, and filter down to just what you have reviewed or just what is still to check. Downloads cover exactly what you ticked or everything you have filtered to, and you choose how each file is named, by question, participant, activity and so on, before it downloads. Reels have moved to their own tab under Reporting. A blank caption icon that had been showing for everyone in the library is fixed too.
The Media Library toolbar: search transcripts, the All, Photos, Voice notes and Videos chips, Collections, and the Add filter menu open on Tag, Person, Length, Reviewed, Questions and Personal informationNew feature
A step by step editor for video reels
Making a highlight reel used to happen in one crowded pop up. The reel editor now walks you through it in five steps: the theme, the clips, the order, the visuals, then the layout. You choose up front whether Yazi picks the clips, by listening to every voice note and video for the strongest moments on your theme, or whether you search what people said and pick every clip yourself. Either way you land on the same clip list, where you can swap, add, remove and reorder before the video is made. If Yazi is picking, it hands you straight back to your list of reels while it works, instead of holding you on a loading screen. A follow up the day after launch fixed three controls that were showing as empty space, the drag handle for reordering clips, the Filters button and Open conversation, and the step labels that had no text colour.
Step one of the reel editor, with the Theme, Clips, Arrange, Visuals and Layout steps across the top and the choice between letting Yazi pick the clips or picking them yourselfNew feature
Hindi and Turkish are now full platform languages
You can now run a study in Hindi and Turkish alongside any other language. Pick them in study settings, translate into them automatically or with your own wording, and participants see हिन्दी and Türkçe in the WhatsApp language picker. Every system message a participant can receive, error prompts, progress, completion and invites, has proper Hindi and Turkish text rather than falling back to English, and voice notes in either language are transcribed in that language. Previewing a multi-language study also works properly now: the Test Simulator used to honour the language you picked on the first run only and quietly switch back to the study's default on every run after, so previewing Turkish straight after Hindi showed English and looked like a broken translation. Real participants were never affected by that.
New feature
Pick a theme for the app, including dark mode
Settings, Appearance now offers four light themes, five dark ones and a System option that follows your device. Everything follows the theme you pick, including tables, charts, pop ups, the WhatsApp previews and the Ask Yazi panel, and your choice is saved to your account, so it follows you to any browser or computer you sign in on. Nothing changes for anyone who leaves it on Light. Two related fixes: the progress box in the Ask Yazi panel had been drawn in exactly the same white as the panel behind it on every light theme, so it was effectively invisible, and a theme picked while the page was still loading could fail to save.
Settings, Appearance: the nine theme cards, Light, Paper, Mist, Solarized, Dark, Navy, Midnight, Slate and ForestNew feature
Ask for a Word or PDF document on any survey
The Document question type used to exist only on WhatsApp Flow surveys, so on an ordinary WhatsApp survey there was no way to ask someone to send you a CV, a signed form or any other file. You can now add a Document question to any survey and tick Word, PDF or both. If a participant sends something else, they get a polite message in their own language asking for the right kind of file, instead of the wrong file quietly landing in your results. Leave both unticked and any file is accepted, as before. A Word document sent over WhatsApp also used to be saved as though it were a PDF, and now keeps its real file type.
Improvement
Charts move onto one teal palette
Every chart in the app now draws from one set of colours, so survey results, cross tabs, word clouds and the Share tab legend agree with each other. Charts have moved off the brand green onto a teal, with a proper range of colours behind it for pies, cross tabs and word clouds, and dark mode gets its own version. The participants funnel no longer stacks green on green. Near duplicate greens and purples are now one of each, which means charts with several series look a little different from before. The Marketing and Utility tags on the Templates page, which had lost their colour, are back.
A Graph Data question card showing an age breakdown as a donut in the new palette: teal for the largest group, then grey, purple, amber, blue and pink, with the AI analysis above itImprovement
The AI interviewer waits for a slow voice note instead of asking again
When a voice note took more than about 25 seconds to transcribe, the participant was told "I didn't quite get that, can you try again?" even though their answer was perfectly clear, and the interviewer never responded to what they had said. That happened somewhere between 10 and 90 times a week. The interviewer now waits for the words and replies to them. "Try again" is only sent when a voice note really cannot be understood, which should mean fewer people dropping off mid interview.
Improvement
Piping is easier to see and set up
In the question builder, the piping icon used to light up on every question as soon as any one question piped an answer. On one survey that was 37 shaded icons for 2 questions that actually pipe. It now lights up only where piping is really set. "Configure repeating blocks" in a question's piping menu now opens the repeating blocks window instead of just closing the menu, and inside it "Pull answer from" names the question rather than showing an internal id. When Ask Yazi builds a survey from a brief and pipes an earlier answer forward, the variable it inserts now uses the same naming as the builder, so it shows as linked to its source question and editing it in the builder no longer breaks it. Surveys built before this keep their old variables and still work.
Improvement
New survey answers show up in about 30 seconds
When a survey had no answers yet, the results page could hold on to "no responses" for up to 15 minutes, so the first answers of a launch did not appear when you refreshed to look for them. It now checks again after 30 seconds, and a page refresh always pulls fresh results. Table Data also hides participant profile columns until you turn them on, which keeps a wide table readable, and the results screen now loads in in-app browsers and older webviews, where it could previously fail to load at all.
Improvement
Asking Claude about your organisation is now almost instant
When you connect Yazi to Claude and ask about your organisation, Claude's first move is to pull a summary of your studies, participants and responses. That summary took around 4 seconds and up to 8, because it read through every message on the platform rather than only your own, and it got slower for everyone as the platform grew. It now takes a quarter of a second and no longer grows as other organisations add data.
Improvement
A clearer first screen for new accounts
The dashboard someone sees before they have any studies is now one card that explains the four steps, choose a method, write your questions, send on WhatsApp, read the results, with a single Create Your First Study button.
Improvement
Colour and spacing tidy up across the app
A run of small visual fixes. Participant status chips such as Sent, Delivered, Completed and Screened out had lost their colour after a clean up and were showing as plain text; they are back. Text boxes that were still a slightly grey shade are now white like the rest of the app, light grey helper text is one shade darker so it is readable, and status greens, ambers and reds are the same shade everywhere. The small action buttons on campaign toolbars, Test, Share link, Add people, Send broadcast and the Build tab's Logic Map, Test and Export, are a touch taller and evenly spaced. Sortable columns on the dashboard show the hand cursor, deleting a campaign or study confirms with a message, and the Broadcast Messages tabs are back to their normal height.
Fix
Syncing results to Excel works again
From 20 September, syncing a campaign's results to a Microsoft Excel workbook failed for every organisation with a "400" error, so anyone using it was looking at a spreadsheet that had quietly stopped updating. It is fixed and the affected workbooks catch up on their next sync with nothing to reconnect. Nobody's spreadsheet was damaged while it was broken: an earlier safety check meant the syncs failed outright rather than writing partial data over existing rows, so the data was out of date, never wrong. Two related fixes: re-exporting a campaign to the same spreadsheet used to create another link to that file each time, and the sync then wrote the sheet once per link, eleven times over on one campaign, which is a large part of why some exports timed out. A repeat export now reuses the existing link, and follows your new choice if you pick a different worksheet tab. And when the app checks whether your Google Sheets or Excel account is still connected, a session hiccup or an outage now says so and offers a retry, instead of telling you your account was never linked.
Fix
AI interview voice notes no longer show as "[AUDIO]"
A growing number of voice notes in AI interviews were showing as "[AUDIO]" in the Transcripts tab, with no words behind them, even when the recording was perfectly clear. Since early August that was 181 answers across 38 interviews. A voice note whose transcription misses the first time is now retried automatically within 15 minutes, so the Transcripts tab and your exports hold everything participants said. The 162 stuck notes that had speech in them have been filled in; the rest were silent clips.
Fix
Taking over a conversation from the AI connects again
After clicking "I Understand, Connect Now" on the human moderator warning, the window closed and nothing happened, so the moderator was never connected to the participant. Anyone who had already accepted that warning was unaffected, because it only appears once per person, which is why it looked as though it only hit some people. For anyone new, or on a new computer or browser, it failed every time with no way around it. It now connects.
Fix
Questions stay in the order you put them
A question added to the middle or top of a survey could reappear somewhere else, usually at the bottom, the next time the study was opened. Two questions could end up claiming the same position and the builder had no reliable way to break the tie. 64 studies were carrying it, 60 of them live. Participants were never affected: the survey that went out was always in the right order, this was the builder showing the wrong one. Affected studies repair themselves the next time someone saves them. Asking Ask Yazi to add a question at a specific position also now moves the questions below it down, where before it put two questions in the same slot every time, and a duplicated question now stays where you put it instead of jumping to the end. Everywhere a list of questions is shown, exported, translated, copied or handed to the AI now comes back in a guaranteed order, which closed one case where a paged results list could show the same answer twice or skip one.
Fix
The "someone else is editing" warning only appears when someone is
Last week's safeguard against two people overwriting each other's questions was firing when you were editing a study on your own, often enough that the warning had stopped meaning anything. It now only appears when the study's questions really changed underneath you, and still appears every time they do. On studies that use piping, changes you made to the piping could also quietly disappear on save. That is fixed with it. Checked on production with three edits in a row, every save accepted first time and no warning.
Fix
Duplicating a campaign gives you a complete copy
Duplicating a campaign could produce a new campaign with no questions at all. Any survey where one question pipes into another, which is common in matrix questions, was rejected when copied and left empty, so the surveys most worth reusing were the ones that came out blank. And because the screen gave no sign that anything had gone wrong, the natural thing to do was click again, which quietly made another empty copy each time. Piped surveys now duplicate in full, a failure tells you it failed, and a failed attempt no longer leaves half made campaigns behind.
Fix
Matrix questions show how many people answered, and get an AI summary
On the Graph Data tab, Matrix question cards showed no participant count at all. On one study five Matrix questions all read "0 reached" while one of them had 1,200 answers, which made good data look empty. Location questions had the same fault. Both now show the real count. Matrix questions also never got the short AI written summary every other question card carries; they said the data was "not available for automated insight generation" even with hundreds of answers. They now get a real one.
Fix
Test simulations run through the whole study
A test simulation on a study with several activities used to stop after the first one, so simulated participants never reached Day 2, the diary or the interview. They now go through every activity in order. Simulated participants also used to answer Number questions in words, "about 3 times a week", which the survey rejects, so any Number question in a screener quietly failed the whole simulated participant. That is fixed too. Real participants were never affected.
Fix
A CSV broadcast no longer stalls when WhatsApp slows it down
When WhatsApp throttles a batch of a CSV broadcast, we pause the send for a while. That pause was never ending, because the check kept re-reading the batch it had already paused on, which stopped one diary study's daily send after its first 50 people. Now the pause happens once, the next batch goes out, and it only pauses again if that batch is throttled too.
Fix
Broadcast and schedule screens say what is actually true
When you set up a CSV Upload Broadcast and pointed its Start button at a campaign with nobody in it yet, a yellow warning said the schedule would not send anything. That was wrong: a CSV broadcast sends to the numbers you upload, and the campaign on the button is only where people land once they tap Start, so it is usually empty on purpose. The warning now only appears on a Reminder, where an empty campaign really does mean nothing goes out. Creating a broadcast with a name already in use now tells you so instead of silently doing nothing, and a leftover from a broadcast deleted on WhatsApp's side no longer blocks that name. On Scheduled Messages the linked column now reads "Linked Campaign / Study" and shows a study's name where it used to say "No campaign linked", and the paused banner spans the page instead of squeezing into a thin column. The "Approved" status on Broadcast Messages is a green chip again.
Fix
New sign ups get the right currency and land where they meant to go
Since a sign in change on 13 September, new organisations were all being recorded as British, so accounts from South Africa and Nigeria were set up in pounds on European pricing, and the reward options when setting up a study defaulted to the UK. New organisations are now billed in their own currency from the moment they sign up; the handful created in that window are being corrected separately. New customers signing up with a work email were also being asked for an access code that did not exist, which is fixed. And if you were signed out and followed a link into the app, you were sometimes dropped on the home page after signing in instead of where the link was taking you. That affected 13 screens, and on the Claude connector it meant the connection could not be finished at all.
Fix
Searching a study's Share tab by phone number finds people
On a study's Share tab, searching by a participant's phone number always said "No results". It now finds them. Searching by name is unchanged.
27 changes
New feature
Split a study into groups from the builder
The statement randomiser divides participants into groups so you can compare how each group responds, which is how you run an arm of a study against a control. It has worked for a long time, but there was no screen for setting it up, so the only way to configure it was to have a developer call the API by hand. There is now a Groups section in the study builder's settings panel: switch group allocation on, choose how many groups, set a target size per group, and pick how people get assigned, either least filled first, in sequence, or weighted. Setting up a split arm study is about thirty seconds of your own time instead of a request queued behind an engineer. Stated plainly so nobody goes looking for it: this is switched on for Yazi's own organisations first and is genuinely not rendered anywhere else yet. It is the first real use of a rewrite of how features get switched on, which now resolves at four levels, the individual person, a named group, the organisation, then the global default, with the most specific setting winning and an explicit off anywhere beating an on further out. That is what makes early access to one client's champion, or a pilot with a named handful of people across different organisations, possible at all.
New feature
Approve a study's rewards from its Share tab
A study with a reward on any of its activities now shows Reward approvals on its Share tab, between View broadcast history and Send broadcast, with a badge for how many are pending. If only one activity carries a reward the drawer opens straight onto it; if several do, you pick, and the drawer header names the activity you are in. Until now the approvals drawer only existed on standalone campaigns, so a reward sitting on an activity inside a study had no obvious way to be approved. Standalone campaigns are unchanged.
New feature
A partner integration that retries instead of losing the push
When we run an AI interview for a partner and push the results back to their own system, that push is the whole product for them. Until now it happened once. If their endpoint was down for even a moment the push was gone, nothing was saved anywhere, so it could not be resent and nobody, including us, knew it had happened. A failed push is now retried up to three times with a longer wait between each attempt, every push is saved before it is sent so anything that still fails can be resent by hand, and if all three attempts fail we get alerted rather than hearing about it from the partner. Each attempt is tagged so a partner can tell a retry from genuinely new data instead of guessing or double counting. Participants benefit too: the push used to happen while someone was mid conversation on WhatsApp, so a slow partner delayed their next question. It now runs in the background in about ten milliseconds. Tested end to end on production against a real partner endpoint rather than a simulation.
Improvement
A study's Table Data works like every other table
Table Data on a study's Responses tab has moved onto the same table the rest of the app uses. It scrolls continuously instead of paging a hundred rows at a time, so you can get to the last response without clicking through; it runs edge to edge under the tabs with the buttons on the same row as the search box; the footer tells you how many responses there are; and search and the status filter now run against the whole campaign on the server rather than only the rows currently on screen, which is why the counts in the dropdown and the footer finally agree. On a campaign with 41,000 answers a search now takes about 280 milliseconds where it used to take a second and a half. The Completed filter also actually filters now. Two things went deliberately: "Load all" is gone, because scrolling replaces it, and column pinning and reordering were dropped rather than rebuilt.
Improvement
Ask Yazi understands more of what you ask it
A run of work on the assistant. Asking for survey questions and an AI interview used to produce two separate activities that could not be used together or converted into one, which was reported repeatedly across four weeks; it now produces one activity holding both. The attach button advertised PDF, DOCX and XLSX and only ever accepted images, and is now wired to the reader that already existed. The study planner used to dead end about a quarter of attempts with an apology about a validation error, because it had no way to ask you a clarifying question; it can ask now. A campaign the assistant creates now comes with the normal "Send to start #CODE" phrase, its WhatsApp link and its language options, and goes live through the same launch step as any other. The microphone transcribes as you speak instead of eleven to fifteen seconds after you stop. And when the assistant has to stop, because the organisation has hit its AI spend limit or AI is switched off, it now says so once in the chat instead of going quiet and retrying in the background every minute, which it had been doing on every cancelled request since June.
Improvement
A study built from your brief carries the rules and languages the brief asked for
When Yazi builds a study from an uploaded brief, the screen outs, skips and piped answers in that brief are now actually built into the questions. Before, they only ever came through as notes on the side and the study let everyone through, which is the kind of thing you find out after fielding. The languages named in the brief are kept too: a brief asking for English, isiZulu and Kiswahili used to build an English only study. Tested with a seven page, three phase brief, where thirteen screening rules, two piped answers and three languages all came through with nothing dropped. Separately, adding a note in the box at the bottom of Create Research now shows your note and the assistant getting to work straight away, instead of looking frozen for a minute and a half while the response was drawn a full screen above where you were looking.
Improvement
One media viewer, wherever you open a clip
Media had grown three different viewers. Voice notes opened in a small white card headed "Image". PDFs showed a broken thumbnail, were labelled "Photo", and claimed the file was unavailable when it was perfectly fine. And when a participant sent several things at once, say two voice notes plus a photo and a video, the photo and video were dragged into the voice note card instead of opening properly. Everything now opens in the same full screen dark viewer with the right label and a working document preview, and "copy transcript" and "AI summary", which only existed on voice notes, now work everywhere they apply. A backdrop blur introduced with this work was taken back out after it made clips harder to read.
Improvement
Excel and CSV downloads are named after the study
Downloaded exports arrived with a string of random characters in front of the study name, like "Dzwcrg8dLPEEMyQ=-uk-global-financial-trust-security-survey.xlsx". Anyone saving several exports had to rename them by hand before the folder made any sense, and a file that starts with random characters looks broken to whoever you send it to. Downloads are now named after the study alone. The internal request id that was sitting in the filename is still doing its real job, keeping two people's simultaneous exports from overwriting each other, it has just moved somewhere the browser does not read. This covers the CSV download and the AI interview export as well, which are delivered the same way.
Improvement
Setting up a schedule no longer changes shape halfway through
Picking a schedule type opened a short, wide window, and then choosing a type jumped you into a much taller one, which made the first step of a routine task feel unsteady. Both steps now open at exactly the same size, and the three options sit centred in the window as three even squares in one row, each name on a single line, instead of being squashed into a two plus one grid with the names wrapping. This closes a run of work on the same area: the Create Broadcast window now keeps its header, step counter, progress bar, close button and Next button fixed in place while only the template list scrolls, where before you could never see where you were in a six step process and the button to continue at the same time; and the Scheduled Messages table shows proper column names instead of raw internal keys.
The New Schedule window, step one, with Reminder, Event Triggered and CSV Upload Broadcast as three even squares side by sideImprovement
Broadcast and schedule screens match the rest of the app
Broadcast Messages, Scheduled Messages and People now run edge to edge like the Dashboard, the loading placeholder on each page is shaped like the table it stands in for so nothing jumps when the data arrives, and the main button in the top right of each page is the same style everywhere. The Table and Cards switch is gone: on a desktop you get the table, on a phone you get cards, because that was never a choice worth making. After you send a broadcast, the recipient list, Successful, Failed and Total, now opens in that same table with search, filters and sortable columns and one scrolling list instead of pages, and the Download CSV button stays put at the bottom of the pop up instead of being pushed out of view. On a campaign, the Responses and Reporting sub tabs now use the same tab component as the Share tab, and in Create Broadcast each action button is a readable card with a proper delete button, where the delete icon had shrunk to a speck.
Improvement
The publish button tells you what is not finished
The Publish button used to be available whether or not a study was ready, so you found out what was missing by pressing it. It now greys out and explains what is incomplete. The pre publish Study Review panel has been narrowed to the two moments it is actually useful, moving a study from testing to live and updating a study that is already live, and it now reviews every activity in a study rather than only the one you have open. It never blocks you from publishing, it just tells you what it found.
Improvement
AI generated studies start with response quality checks on
A study created by Ask Yazi now arrives with Response Trust switched on, which is the setting that scores answers for quality and flags the ones worth a look. It was off by default, which meant the quickest way to create a study was also the way least likely to have quality checking on it. Existing studies are unchanged and still need the toggle set by hand.
Improvement
Wide tables scroll without freezing
A study's Responses across many activities, or an interview's Table Data, could freeze while you scrolled, and the table would nudge itself to a row edge when you stopped instead of staying where you put it. On the widest study we have, the slowest scroll frames went from about a third of a second to under thirty milliseconds. Nothing looks different. Two smaller things on the same screens: "Show more" on a transcript now opens only that transcript and the row is exactly that tall, instead of every row stretching to fit the longest transcript in it, and if you scroll faster than the table can draw, the rows still loading show placeholder lines instead of a blank white area.
Improvement
The app loads three to four times faster
The main file the browser has to download to run Yazi was going over the wire at 5.1 MB. It now goes at 1.4 MB, because it is compressed in transit and served over a newer protocol. First loads and the reload you get after a release are roughly three to four times faster. This is a setting rather than a rewrite, and nothing about the app changed to get it.
Improvement
A pass of security and privacy work
None of this changes how you use the product, and some of it is worth knowing if you have been through our security review. Participants can now have their data erased on request through a dedicated route, and the codes that stand in for participants in an export are now generated with a server held key, where the old ones could be reversed in about a hundred seconds on a laptop. A monthly retention report now goes to the team so data past its retention period is cleared deliberately; nothing is deleted automatically. Our connection to the production database now verifies the database's certificate rather than only encrypting, and the chat service's container now takes security updates, which moved it from three critical and seven high issues to none critical and one high. Three access gaps closed: an endpoint that moved users between organisations never checked who owned them, an unauthenticated route on Live Forms was still reachable on production despite having been removed, and internal services now identify themselves to the chat engine instead of arriving anonymous. Two housekeeping problems surfaced while doing it: 144 people who had signed up with Google existed in the sign in system but had no record on our side, so they could not be given a role, and those are now backfilled; and 110 organisations still have no owner, which we have deliberately not guessed at.
Improvement
The participants list on Share and People uses the shared table
The participants list on a campaign's Share tab and on a study's People tab now use the same table as the rest of the app, so they look the same as each other for the first time. You get faster scrolling through big lists, search and sort in the toolbar, tick all to select everyone, and hovering a status or a trust reason tells you what it means rather than leaving you to infer it.
Improvement
Every empty screen now says the same thing the same way
Every "nothing here yet" screen in the app, no responses, no people, no media, no matches for a filter, now uses one shared design, so they read the same wherever you meet them. That sits on top of a long run of consolidation work this week which is mostly invisible by design: the last of the old front end framework is out of the app and the stylesheet is about 15% smaller, corner rounding and colour now come from one shared scale, default buttons and page headings use the brand navy instead of an old dark grey, status colours sit one shade darker so text on them passes contrast, and about 16,600 lines of code and styling that nothing used any more are gone. What you will actually notice: controls are a touch tighter, dropdown filters open the app's own list instead of your phone's picker, action menus work with the keyboard, every button and step arrow shows the hand cursor when you hover it, table icons show our own tooltip instead of the browser's grey one, and side drawers open at half the screen width. Credit balances also stop showing a long tail of decimals, so $8.870000000000005 now reads $8.87, in the app, in the Slack alerts and in the API.
Fix
You stay signed in for three days instead of about an hour
Being logged out mid-task was the most common complaint about using Yazi, and it turned out to be one line of logic. The token that renews a session was set to expire at the same moment as the session it was meant to renew, so the renewal could never happen and everyone was dropped after roughly 55 minutes. A session now lasts three days and renews itself in the background. Four related faults went with it, because the first fix was not enough on its own: two other checks, one when you switch back to the tab and one that runs every five minutes, were still ignoring the renewal and quietly resetting the clock; the call that answers "who is this session" had no timeout at all, so a slow response hung the page for thirty seconds with nothing in the logs to explain it, and is now bounded at about three seconds with a real error; and in the cookie based path, five different places were each responsible for refreshing the token and one of them never did, so a slow sign in service could wipe every cookie you had. Nobody who was signed in had to sign in again for any of this. Signing in with Google or Microsoft also no longer asks you for an emailed code on top of the identity check you have already passed.
Fix
Signing up and accepting an invite works the whole way through
Getting a new person onto an account was broken in about nine separate places at once, which is why it kept reading as bad luck rather than a bug. Joining with an access code saved the membership and then bounced you back to the code screen. An invite link told signed out recipients the invite was unavailable. A successful join said "Successfully joined undefined!". Invitees saw the full signed in sidebar and a red "Organisation ID not found" before they had an account. The sign up form checked passwords against a weaker rule than the one the system actually enforces, so it accepted passwords that were then rejected. Create Account could hang on a spinner with the error rendered inside a decorative phone image where nobody would look. Someone who entered a correct emailed code landed on an empty login screen with the invite still unaccepted. Invited members were walked through setting a logo their organisation already had. And on a small laptop the password reset page cut off the Reset button, which is how one client's user got stuck part way through a reset. All of those are fixed and verified with real sign ups on production. Two things are worth stating rather than leaving to be discovered: for the nine organisations that share the askyazi.com domain, an invite can still name the wrong workspace, and that half is still open.
Fix
Study results no longer count the same participant twice
On a study that mixed activities with privacy protection on and activities with it off, the same person appeared as two separate rows in the results, once under their real identity and once under their protected one. On one diary study that meant 71 participants showing as 142 rows, and studies on three other accounts were in the same state. Nothing was lost and nothing was duplicated in the data itself, but anyone reading a participant count off that screen was reading a number that was up to twice the truth. One person is now one row. Three other faults on the same screen went with it: searching lagged about a quarter of a second behind every keystroke and now responds in single digit milliseconds, rows jumped in height as you scrolled and are now a fixed height with a "Show more" for long answers, and a first pass at this had emptied the transcript cells, which is restored. If you pulled a participant count off a multi activity study with privacy protection on any of its activities, re-check it.
Fix
The builder can no longer throw away your question edits
Four different ways the study builder could lose your work, all closed this week. Saving questions reported success and discarded the change on any study with more than a handful of questions, which meant you could spend an hour editing and have none of it reach the database while the screen told you it had saved. A question you had just typed vanished entirely if you switched browser tabs within about half a second, because the pending edit was thrown away before the save request went out. And when two people had the same study open, their saves overwrote each other's question lists; on one live survey that produced two questions both numbered "1". A save made against an out of date copy is now refused, refetched, merged and renumbered rather than winning by being last. The first time that happens in a session you get a plain amber notice saying someone else is editing the study and that your latest changes take preference, naming the question if you both changed the same one. Until now that merge happened silently, which is arguably worse than the overwrite, because nobody knew to go back and check.
Fix
Reward approvals show what the participant actually got
The Reward Approvals panel was showing the wrong amount for Tremendous rewards, for example "63.93 ZAR" against a reward the participant received as R1,000, because the system recorded what the reward cost us in dollars and then labelled it with the wrong currency. Participants were always paid the right amount. Only the record was wrong, which matters if you were reconciling incentive spend off that screen. New payouts record what the participant actually received. The 113 existing records, across three campaigns since 21 August, are corrected by a one off script, so until that has been run those older rows still show the old number.
Fix
Google Sheets connections need one reconnect, and the export dialog opens again
Two things closed here. Production was still asking Google for the broad Drive permission even after the narrower one was approved on 15 September, so anyone making a new connection hit Google's "unverified app" warning screen. We now ask only for the specific spreadsheets we create or you pick. And since a change on 14 September, dialogs were never repainting after they loaded, which meant the Google Sheets export sat on a spinner forever with no way to tell it apart from a slow export. Both are fixed. If you had a Google Sheets connection, it needs reconnecting once, which is one click in Settings, Integrations. The old connection had already expired so there is nothing to lose by doing it.
Settings, Integrations: the Google Sheets card showing Not connected with a Connect buttonFix
A blank white screen after a release now fixes itself
When we deploy, a browser holding the old version of a file could be handed something it could not read and would show a blank white page until you reloaded by hand. On one day this week we deployed five times and one file broke a tab within eighteen minutes of a release, so this was not rare. The page now reloads itself once, silently, and if that does not work it says so in plain language instead of leaving you looking at nothing. A follow up closed the obvious hole in that: the marker saying "I have already tried reloading" was never cleared, so a tab that hit the problem twice could be stuck on the failure screen forever. It now clears on every successful start. The underlying cause is a content delivery setting we are deliberately not touching, because the last attempt at it caused an eleven hour outage.
Fix
A multi select capped at one no longer breaks the WhatsApp form
If you set a multiple choice question to multi select and then set its maximum to one, the question went out as a WhatsApp Flow asking for at least one and at most one answer, which Meta's own client refuses to open. The participant saw "Something went wrong. Try again later." and could go no further. The builder now turns that field red with an inline explanation, holds it back from autosave with a clear "Saved, except" note, and blocks publishing until it is resolved. Worth knowing: existing questions already set this way are not rewritten, so if you have one in field it needs switching to single select or having its maximum raised. Single select and ranking questions were never affected.
Fix
Test responses show up in Table Data
With "show test data" switched on, the Table Data tab said there were no responses, while the Transcripts tab showed them correctly. Anyone testing a study through the Table Data view reasonably concluded their test answers had not been recorded. They had been the whole time. Both tabs now show them.
Fix
The Test Simulator opens an AI interview again
Since early September, an AI interview opened in the Test Simulator or in a study simulation came up blank, so simulated interviews failed at the first message. The interviewer's opening message is back. Two related faults in study simulations went with it: test personas logged an error every time they started, and a simulation would silently stop rather than get past a scheduled activity such as a Day 2 question.
45 changes
New feature
Connect Claude to your Yazi data
You can now point your own Claude at your Yazi research and ask questions in plain English. In Settings, Integrations, Connectors you copy one address into Claude, sign in to Yazi, and choose what Claude is allowed to do. Reading your research is always on; making changes to studies, seeing participant phone numbers and including demographics are each a separate permission you can revoke from the same screen at any time. Claude can pull respondent level answers, run cross tabs with significance testing and small cell suppression, filter results by other answers, read voice note transcripts, and ask for a full study export in the background. It can never delete or launch anything and it never sees another organisation. The protections are built in rather than bolted on: participant ids are pseudonymous per organisation, phone numbers are masked, contact details are scrubbed out of answers unless you explicitly allow them, participant text is labelled as data rather than instructions so it cannot steer the model, and every call is audited and rate limited. Two things landed with it in the same week. Interview answers and AI follow up probes were invisible to the connector at first, which was hiding roughly 450,000 messages across 601 studies, and that is fixed. And three connector tools failed for about twenty minutes on the afternoon of 8 September while that fix was corrected; it was a hard failure rather than a wrong number, so nothing it did answer during that window was wrong.
Settings, Integrations, Connectors: the Open in Claude button, the MCP server address with a Copy action, and the set-up steps for claude.ai, Claude Code and Claude DesktopNew feature
NPS questions are now tapped, not typed
The classic "how likely are you to recommend us, 0 to 10" question used to arrive on WhatsApp as an open text box. The participant read the scale, typed a number, and we then had to check they had typed something sensible. That is friction on the simplest question in a survey, and it is exactly where people drop out. Participants now get a tappable grid of every point on the scale and tap one. No typing, no format guessing, no validation failures. It took three services to do because WhatsApp's normal buttons cap at three options and its lists at ten, so an eleven point scale fits neither and had to be built as a Flow. Worth knowing what that turned up: before this, a reply from a scale question was being silently discarded, so the grid would have rendered perfectly and the participant's tap would have vanished. That was found while tracing the code rather than from a report.
New feature
Set up an AI interview by asking for it
Ask Yazi could talk about an interview campaign but could not change how the interview runs, so probing intensity, question style, interview flow, sensitive topic handling and the message cap all had to be set by hand in the builder. Eleven settings can now be changed by asking: those five, plus target audience, key topic areas, required questions, the multiple choice toggle, cultural notes, comparative brands, the end interview early description and cross campaign context. Ask it to probe more deeply and it does. Two guard rails are worth knowing about. On a Live or Paused campaign it shows you an approval card and waits, so it will not quietly change a study people are currently in. And it refuses to apply interview settings to a Survey or Diary campaign and says so, rather than reporting a successful change that could never take effect. One older fault went with it: asking it to set key topic areas used to fold them into the research objective instead, so the setting looked applied and landed in the wrong field. A setting the assistant silently gets wrong is more costly than one it refuses, because you have no reason to go back and check.
New feature
Drag any column wider
You can now drag the right edge of a column header to widen it, on every table built on the shared data table: Dashboard, People, Broadcasts, Send History, Scheduled Messages and Broadcast Recipients. The columns to the right give way, so the row keeps filling the card instead of jumping to a horizontal scrollbar. Widths are remembered per table and per browser and survive a reload, and double clicking the handle puts a column back. This is what fixes "I cannot read the full campaign name", where a long title was cut off with an ellipsis and no way to widen the column. Nothing is drawn at rest, so the tables look unchanged until you point at them, and hovering anywhere over a header now shows a faint line at its right edge so the handle is findable. The tick box and Actions columns are not resizable, and keyboard resize is not built yet.
New feature
Live Forms can end with a proper thank you
When someone finished a Live Form, the web link version of a survey, they got nothing. No thank you, no confirmation, no next step. The builder was actively hiding the completion message setting on Live Forms, on the basis that nothing gets sent to a web link survey, which was not true: the delivery was already wired up and working, nobody had ever been able to fill the message in. Every Live Form in production had no completion message. You can now write one and choose where it lands: shown in the form itself as the last thing the participant sees, sent to them on WhatsApp afterwards, or both. Template messages are supported for the WhatsApp route. This matters most on panel and paid studies, where people need to know they are finished and will be paid.
New feature
The Ask Yazi panel, rebuilt
The assistant drawer worked but was unpleasant to use. It was narrow, what it was currently doing was scattered across four places, tables were crushed into unreadable columns, several controls were invisible, and there was no way out of dark mode. The drawer now opens to about half the screen, everything the assistant is doing is docked in one place just above where you type, tables scroll properly, there is an explicit light and dark toggle, and approval prompts read as buttons rather than a wall of text. Four smaller things went with it. Questions the assistant adds now appear straight away instead of needing a page refresh, which was happening whenever the page was busy publishing or changing status at the same moment. New conversations name themselves as soon as the first answer finishes, so the sidebar is no longer a list of identical "New conversation" entries. Approving a change no longer shows a red error for something that actually worked. And you can drag the panel as narrow as it goes and still close it; the Minimise button used to disappear, which left you stuck with the panel open until you reloaded.
The Ask Yazi panelNew feature
Pick the survey format when you add an interview to a study
When you add an AI Interview to a multi activity study, you can now choose how the short survey that runs before the interview is delivered, as a conversational in chat survey or as step by step screens. That choice was missing from the Add Activity screen, so every interview added to a study silently used the in chat format, even though the same option had always been there when creating an AI Interview on its own.
Improvement
Adding an activity is one screen instead of four steps
Adding an activity to a multi activity study used to be a four step wizard, method, then format, then name, then confirm, with a green outline for one activity type and a teal outline for another. It is now a single scrollable screen: name the activity, pick the research method, then the format, which only appears when it is relevant. Selection is one consistent colour throughout. Recurring Survey now gets a format choice too, which it did not have before. Two bugs went with it: choosing Recurring Survey and Live Form together was being saved as a plain Recurring Survey rather than a Live Form, and Live Form activities were not showing their correct label in the study's activity list. The pop up also no longer asks you to choose a language for the individual activity. A study's language is set once, on the study, and every activity follows it, so the extra dropdown only made it possible to give an activity a language that disagreed with its own study. Creating a standalone campaign still has its own language picker, which is correct.
Improvement
Publishing a study is one action again
Getting a study live had quietly become a three step dance. You moved it to Testing, then flipped it to Live, then had to find and press a separate Publish Changes button. Worse, moving to Testing did not actually send anything, so your test respondents received nothing at all while the status went red telling you something still needed publishing. Pausing or closing a study did much the same, showing a Publish button for changes you had never made. Moving a study into Testing now publishes it as part of that move, so testers get it straight away, and the Publish button only appears when you have genuinely edited something that has not gone out yet. Three related things shipped with it. The pop up that appeared the first time you saved an edit on a live study is gone; the screen already tells you the same thing in three quieter places, and the dialog arrived at the moment you least want one, mid edit. The status control at the top of a study is now a single button in the standard dark colour with the dropdown joined onto it, instead of a bright green button, a separate darker green arrow box and a stray blue outline. And when a question error is blocking publish, clicking the button now opens a list of exactly what is wrong, question by question, in plain English, with a link that takes you straight there and highlights it, instead of a tooltip saying "fix 1 question error to continue" and leaving you to hunt through twenty questions.
Improvement
"Started" now means someone actually answered
Started used to mean a survey session existed, and a session is created the moment question one is delivered. So anyone who received a question and never replied was being counted as having started. Started now means the person answered at least one question. Underneath it, sixteen different places in the code worked out a started figure and only two of them shared the same rule, so the dashboard, Graph Data and the AI assistant could each give you a different number for the same campaign and all be defensible. They now read from one definition and cannot drift apart again. The numbers are smaller and they are correct: across the platform 487 of 1,582 campaigns were overstating it, about 11,686 people who had answered nothing. Expect completion rates to tick up slightly, because they are worked out against people who started and that group is now the real one. Two more numbers came into line the same week. The Responses tab's completed count now reads the same completion record the Share tab funnel and the campaign dashboard already read, which moves about 15,673 sessions across 292 campaigns from completed to in progress on that tab only; the funnel and dashboard never counted them, so no headline number changes. And the dashboard's count is called Started again rather than Opened, which was the wrong word because it reads as the message being opened.
Improvement
Voice notes and video answers now show what was said
When someone answered with a voice note or a video, the transcript often showed a player and nothing else. The words were in the database the whole time, transcribed the moment the clip arrived, but the transcript never asked for them. On production that was 43,230 answers. For a spoken answer the words are the answer, so a researcher reading a transcript, exporting a PDF or copying a quote was getting a playable clip and no text, and the only way to know what a participant said was to sit and listen to every clip one at a time. Those answers can now be read, scanned, quoted and exported like any typed reply, in the Transcripts tab, in CSV and Excel exports and in the exported PDF, which matters most because a shared PDF is often read by someone who cannot play the audio. This also explains why the same question's answers looked inconsistent from one participant to the next: one had a typed caption and the rest did not. Alongside it, the four different places a clip's transcription could appear were each drawing their own version of it, with their own headings, sizes and colours. They now all use one component, so a clip's words read the same wherever you meet them. Three things fell out of that: the headings were hardcoded English so Portuguese tenants read them in English, one version was dark grey text on a near black background, and the media modal's transcript was rendering smaller than the caption sitting next to it.
Improvement
Media links in your exports keep working
Media in a downloaded export was being written in as a temporary link that expires in days, so opening a Group Discussion export a week later gave you a transcript full of dead links. Researchers archive these and come back to them, and a transcript with nothing playable is not usable evidence. Live Room and transcript exports now use the same permanent, revocable short links every other export already used. Two related things went with it. Group discussion exports were dropping the download link entirely for documents, images and voice notes, which came out as bare text like "[document]" with nothing to click; video worked only by coincidence. Every media type now exports with a working link, and any caption on the message is kept too. And there is now an automatic check that blocks any new export handing back a raw link, which is the real fix: this exact problem had been reported and repaired three separate times on three different screens, each time because nothing forced the next export to do it properly. One gap stated rather than buried: interview media stored under one older location still falls back to the old style of link, because moving it is a bigger change and is tracked separately.
Improvement
Group Discussions look and behave like the rest of a study
Group Discussions let you run a moderated group chat on WhatsApp as an activity inside a study. The room had drifted from the rest of the platform, so moving between a survey and a discussion felt like moving between two products. The tab bar no longer jumps when you switch activity, the duplicate "Room closed" banner is gone, the text is on the same scale as every other screen, the people panel can now be minimised on a laptop and hands about 350px back to the conversation, the message box matches the transcript screen, and the room uses the full width of the screen while every other tab keeps its normal margins. Two behaviour fixes went with it. A group discussion was being listed on the dashboard as a "Live Form", the same label as the single participant web form, so two quite different things read as one; they now read Group Discussion, and the solo web form still says Live Form because that is what it is. And removing someone from a discussion now actually lets them move on. Previously the only thing that finished a discussion activity was the moderator closing the whole room, so a person removed at 10am sat frozen on that activity until somebody got round to tidying up, which might be hours later or never. The same now applies if someone is blocked or leaves the chat themselves.
Improvement
A pass of security hardening from the July penetration test
A batch of security work landed this week, none of it changing how you use the product. Sign in tokens no longer sit in browser storage that survives closing the tab, so a stolen token dies with the tab; the only thing you will notice is that a brand new tab no longer inherits an existing login for free. Organisation and user supplied names, study titles and activity names are now escaped before they go into an email, closing a way a crafted name could have injected markup into somebody's inbox. Three cross organisation gaps are closed: one organisation could read another's AI generated survey drafts by guessing a job id, any logged in user could pull platform wide signup numbers, and a download link for another organisation's feedback attachments could be minted by guessing a storage key. While fixing the last one we found two different companies whose names collapse to the same storage folder, so access now fails closed when a name is not unique rather than trusting it. Participant phone numbers and one time codes were being written to our logs in plain text and are now masked. A request to create an organisation used to trust whoever it named as owner, so a signed in user could have moved someone else's account into an organisation they controlled; that is refused now, on that route and its two siblings. And a testing only endpoint that fakes a broadcast send had a development only gate that treated production's internal label as development. It was never wired to the public production interface so nothing was exposed, but the gate itself was wrong and now uses the one shared signal for what counts as development.
Improvement
The People table pages, searches and sorts across everyone
The People table now runs on the shared data table. You get numbered pagination instead of previous and next, so you can jump to any page rather than clicking through, and search, sort and paging are handled server side, which means they work across everyone in the account rather than only the rows currently loaded. There is one consistent skeleton on every reload, so searching or sorting no longer flashes a differently sized loader. The phone privacy notice strip is gone, with that state now living on the header button and the Phone to Participant ID column relabel, which gives the table back the vertical space. Created now shows a time, matching the dashboard. A first load bug went with it, where the table rendered shorter than its card and clipped the last row until you changed page.
Improvement
Scheduled Messages gets search, filters and a working progress column
Scheduled Messages has moved onto the same table the Dashboard and Broadcast Messages use. It now has infinite scroll instead of pagination, plus the same search and Add Filter builder as the other tables. A bug went with it: the Progress column was rendering the literal text "[object Object]" instead of a progress bar for every CSV upload and event triggered schedule, and the same underlying problem meant searching or filtering for "object" matched every row that had progress data. On Broadcast Messages, clicking anywhere on a row now opens the edit modal, matching how Scheduled Messages already behaved; the Category and Type chips still open the preview.
Improvement
Big campaigns load again, and the platform is faster
Three performance problems closed this week. The campaign participants table was timing out with an error when sorted by Last activity on large interview campaigns, because the roster ran every per participant lookup across the whole campaign before paging, which took 93 seconds on an 8,149 participant campaign against a 30 second limit. It now works out the sort once per campaign and loads only the page of rows it returns, which takes under half a second when warm. Separately, the production database ran at 100% CPU for about two hours on the morning of 10 September, making the dashboard slow and, for accounts with a lot of campaigns, showing only studies because the campaign list timed out. The cause was a stats table being recalculated every time anyone started or finished a survey, which got much more expensive as an interview campaign grew. Nothing in the product reads that table, so the recalculation is switched off and every call to it has been removed. Survey answers kept saving normally throughout. And the production database itself has been given double the memory. It had been running on 2GB, had run out of room and was spilling to disk every day, which is a plausible contributor to the general slowness people have been reporting. The spilling stopped the moment the change went live. That took about 41 seconds of dropped connections at 23:11 on a Thursday, the quietest hour of the week, and it buys roughly three months at the current growth rate rather than being a permanent answer.
Improvement
The completion message is now part of the question list
The completion message used to sit in a separate panel below the add question button, which read as a different kind of thing from the questions above it. It now renders as the last row of the question list, with the same height, grip and badge as a question, a padlock in the grip slot, and a preview action. It expands on click and saves when you click away, and dragging it explains that it cannot be reordered. Six adjacent faults went out with it: 48px of dead space above the add question button, a question that could not be dropped into the last position, a completion editor whose text box did not match the question's, an add question picker that opened as a column taller than the screen, a popover that mis centred itself when wider than the thing it hung off, and AI interview activities with no questions showing a bare plus with no explanation.
Improvement
Warnings and errors now look like warnings and errors
Every notice box in the app was a plain white card with a coloured border, whatever it was saying, so a study telling you five participants are stuck looked the same as a tip about writing a broadcast. Errors, warnings and successes now sit on the lightest step of their own colour, so a problem reads as a problem at a glance. Information, neutral and brand notices are deliberately unchanged, because advisory notes should not shout, and the full width bars at the top of the app are untouched. The action button in a notice also now lines up with the sentence it acts on rather than sitting slightly below it, which was most visible on the "participants have been stuck" notice where the Review button was noticeably off. Behind it, every hand built notice in the app, 84 of them across 36 components, now comes from one place, so this was one decision rather than eighty.
Improvement
A sweep of small visual faults
A run of small things that each made a screen look broken. Campaign pages ran right up against the right edge of the window with nothing to breathe, and on a tablet the Send broadcast button sat on top of the Participants tab label and cut it to "Partic". The active tab underline on Study configuration and Plan and Usage was being clipped to a third of its width, which had been reported twice as its own bug. Every dropdown in the app was drawing two nested borders, on the Schedule modal, the Dashboard and Broadcasts filter bars, quota setup, survey filters, screener outcomes and the broadcast activity picker. Accordion headers were showing a grey band, a stray chevron and 26px of extra height, most visibly on question cards. The Responses tab rail stopped 24px short of the page edge while the divider above it ran the full width, and the table card below it had a notch cut out of its rounded corners. Toasts floated 48px above the bottom right corner with nothing beneath them, and on the study Build page one landed on top of a settings row. Chrome's saved entry popup was opening on top of the Send broadcast template picker and the campaign picker. Clicking Dashboard from a campaign's Share tab navigated away and then snapped straight back. The study title on a multi activity Build page rendered grey and smaller than the campaign equivalent. The Share tab's buttons read bigger than the Build tab's, with a different label size, icon size and text colour. And the "Or add manually" tiles in the Add people modal were drawing oversized, offset and clipped.
Improvement
AI interviews can be as short as two questions
The shortest an AI interview could be was three questions. It is now two. The three was not there for any real reason, it was a number someone picked, and it had already come down once before from five. Some studies genuinely need a question and a follow up, and researchers were padding them out. We tried allowing one as well and tested it on real WhatsApp conversations: it does not work, because with a limit of one the interview finishes before the AI asks anything and the participant answers the survey and then gets silence. So two is genuinely the shortest for now. No existing study is affected and nothing changes about how interviews run.
Improvement
The activity count is back on the dashboard
The per study activity count is back on the dashboard table, this time as a line under the study title rather than a second chip in the Type column, on the basis that an activity count is not a campaign type. A study row now reads as the title with "N activities" beneath it, and the Type column keeps its single Study chip. One visible consequence for everyone: dashboard rows are taller than they were, so roughly four fewer rows fit on screen, and that applies to campaign rows too because the table sizes every row the same. Other tables keep their previous row height. A follow up tightened it back up a little, and fixed a real bug where a long study name in a row with an activity count ran across into the Started column instead of ending in an ellipsis.
Fix
Broadcast analytics were inflated about tenfold
Opening the analytics on a broadcast showed 241 sent, 241 delivered and 181 read for a broadcast that actually went to 25 people. Every figure was roughly ten times too big, and it affected any organisation looking at broadcast analytics, not only the one where it was spotted. These are the numbers you use to judge whether a broadcast worked, and a read rate built on a made up denominator is worse than no number at all because it looks authoritative. Anyone who reported on a broadcast recently was reading fiction. Those screens now match the database exactly. Worth saying openly: the first fix for this shipped on a wrong diagnosis and did not work, and was caught on production.
Fix
Multi-select questions were dropping every option past the tenth
If a multi select question had more than ten options, everything after the tenth was quietly dropped before the participant ever saw it. No error, no warning, nothing in the app. The researcher saw all their options in the builder and reasonably assumed participants did too, so a question offering twelve options was only ever asking ten. On production that affected 220 live campaigns and 659 answer options that had never been shown to anyone; one live recruitment screener had 26 options and was showing ten. The cap was never a real WhatsApp limit, it was a constant borrowed from a different question type. Questions up to twenty options now show every option as tappable buttons, and anything larger falls back to a lettered list, which has no limit at all. The builder was also refusing to publish anything over ten with a red error that claimed WhatsApp did not support it, which blocked a live study outright; it now says plainly how the question will be delivered instead. Four other places in the builder were describing the wrong thing about how a question would look on a phone, and those were corrected too. One thing we cannot fix: an option that was never offered looks exactly like an option that was offered and not chosen, so responses already collected on those questions are missing choices participants never had. Anyone with a long multi select in field before this week should have their data looked at before it is used.
Fix
Completion messages now send after every activity, not just the last one
The study builder showed the completion message switched on and filled in with default wording. The backend quietly disagreed: it only treated the message as real if a researcher had typed their own custom text, so if you left the default, the message was thrown away every time a participant moved straight on to the next activity. In practice participants only ever saw a completion message at the very end of a study, and researchers had no way of knowing, because the screen told them it was on. Across the last 120 days, activities relying on the default wording delivered a message on only 80 of 867 completions, so roughly 787 confirmations that should have gone out never did. Participants now get the confirmation they were promised at the end of each step, and researchers get what the builder shows them. One limit stated plainly: this covers survey activities. AI interview activities and group discussions close down a different route and are not fixed yet.
Fix
Google Sheets exports are working again
Google Sheets exports stopped working on 30 July and nobody knew. Anyone trying to link a sheet just saw "No spreadsheets found in your Google Drive", which looks exactly like having no spreadsheets, so it never got reported as a bug. Six weeks, nothing working, no complaints. Exports and syncing are back. Separately we found something worse while in there: if Yazi ever failed to read a linked sheet, it would overwrite that sheet with only the new rows, wiping any columns the researcher had added themselves. That could have quietly destroyed client work, and it now refuses and reports the failure instead. One thing to know: everyone connected to Google Sheets needs to reconnect once. The existing connection had already expired so there is nothing to lose, and the app now tells you to reconnect rather than showing an empty list. It is one click in Settings. There is a side benefit worth knowing if you have been through our security review: we were asking Google for access to your entire Drive, and we now ask only for the specific spreadsheets we create or you pick.
Fix
Privacy protection now covers every screen
Privacy protection is the setting you turn on when a study must not expose who said what. Two screens were still showing real participant names with it on. The Media Library's People tab was listing 305 people's real names on one live study, across 21 pages, and seven protected studies on production had media in them, so it was not a one off. And when an operator took over a WhatsApp chat on a protected study, hovering the participant chip showed the real name anyway, even though the same screen already hid it elsewhere. Both are fixed and verified on production: those names now read "Respondent #xxxxxx", and studies without privacy protection are unchanged. This is a POPIA obligation rather than a cosmetic setting. A client turns the toggle on because they were told identities would stay hidden, and any place that still shows a real name breaks that promise.
Fix
Airtime rewards now reach more networks, and participants hear about them
Three separate airtime problems closed this week. Rewards were failing for every participant in Côte d'Ivoire and Benin whose WhatsApp number is still in the older eight digit format, because our airtime provider rejected them; they are now converted before sending. Moov Africa Togo and Moov Benin participants were failing with "could not auto detect operator" while participants on other networks in the same campaign were paid normally. The operator was never missing, only the provider's automatic lookup could not map those prefixes to it, and we were treating that lookup failing as the payment being impossible. When it draws a blank we now resolve the operator from the national numbering plan and carry on. And participants were getting their airtime with no WhatsApp confirmation at all, because we defaulted to a template that only exists on one account, so for every other organisation the confirmation was blocked and then logged as sent successfully anyway. Confirmations now go as a normal message if the participant messaged us in the last 24 hours, which is true right after a survey, using your campaign's reward wording if you have set one. If you have failed airtime rewards sitting in Reward Approvals, they need a Reprocess.
Fix
"View full transcript" on an insight now opens the transcript
Clicking View full transcript on any citation in Reporting, Insights showed "Could not locate the transcript for this response" and never opened the drawer. Every citation, every interview campaign, for seven weeks. The cause was not the Insights screen. The piece of data the drawer needs has been sent since 21 July, but a middle layer was silently discarding it because the key was not declared in its schema, and an undeclared key is a quiet delete rather than an error, so nothing failed loudly. Fixed. The same one line change fixed something worth knowing about separately: the raw responses export had been writing the campaign id into every row's Interview ID column and keying Question ID on the individual message rather than the question. Any raw export pulled between 21 July and 8 September carries that flattened data, and re-pulling it now returns it correctly. If any client analysis was built on one of those exports, it is worth a look.
Fix
Questions missing from Table Data and exports
Some questions were quietly missing from Table Data and from the CSV export even though they showed up fine in Graph Data. The columns were built from whatever answers happened to be on the page you were looking at, so any question nobody on that page had answered got no column at all and simply vanished. It hit market specific questions hardest, because only a fraction of respondents ever reach those. Every question in your survey now appears in Table Data and in the export, every time, and a question nobody answered shows as an empty column instead of disappearing.
Fix
"is not" routing rules were firing for everyone
A rule like "if the answer is not Difficult, jump to question 12" was firing for everyone, including people who answered exactly the thing it was meant to exclude. The rule looked correct in the builder and was effectively ignored, so participants could be routed down the wrong path or skip questions they should have been asked. That is fixed, so "is not" rules behave the way they read. We checked every campaign in production: only one was affected, and it had already finished and was paused as a precaution, so no live study needs re-running.
Fix
A brand new account's first study would not start
For a brand new organisation, the very first question of their first study was never actually delivered. The study looked live in the dashboard while the participant's phone stayed empty, and every attempt to restart it looked broken too: setting the study back to testing and live again got as far as a "there is a study currently running" prompt, and Continue and Start Over then did nothing either. This hit clients at the worst possible moment, on their first ever study, often during a demo or a handover, and it affected three separate organisations over the past month, two of which never reported it because the symptom was quieter. New accounts can now start their first study straight away.
Fix
A participant removed after completing can rejoin
If you removed someone from a study after they had completed it, they could not re-enter using the study's starter phrase. Every message came back with "You have already completed this study". Removing someone only marks their enrolment as deleted and leaves the completed status underneath, and the survey engine was reading that as a live enrolment. The lookup now ignores it, and re-enrolling starts a fresh active enrolment rather than an already completed one. This applied to any study on any account, and no data repair is needed: anyone affected fixes themselves the next time they send the starter phrase.
Fix
The builder could stop saving without telling you
Clicking Add Option on a multiple choice question could quietly stop the builder saving anything you did after that, for the rest of that session. Edits looked applied on screen, nothing errored, and none of it was reaching the database, so somebody could spend an hour editing a study and lose all of it with no warning. That is fixed, and if a save is ever rejected now you are told exactly which question has the problem rather than silently losing work.
Fix
Edits to a campaign could quietly revert
Two ways a change you made could disappear, both now closed. If you changed a setting in the Build tab and then renamed the campaign in the same session, or the other way around, one of those changes could revert to its old value with no error shown, because the app was holding two slightly different copies of the campaign in memory and one could overwrite the other's save. And renaming an AI Interview campaign while a colleague had it open, or while you had it open in a second tab, meant the next save from the other session could put the old title back with no warning; a save from the interview builder now sends only the fields you actually changed, so it cannot overwrite someone else's edit. One more in the same family: changing a draft survey's delivery mode to Live Form just after editing its WhatsApp Flow settings could quietly turn Flow back on a second later, leaving the survey set to Live Form but flagged as a Flow underneath, which the settings screen could not display properly.
Fix
Bulk download from the Media Library respects your filter
If you filtered the Media Library to one media type, say just the photos, and hit Download Selected, you still got everything, voice notes and videos included. Filtering then downloading is the normal way to get one kind of media out of a study, so researchers were getting a zip full of files they had deliberately filtered out and sorting through it by hand. Worth flagging because it is not the first time: this was fixed in May, accidentally undone two days later inside an unrelated change, and has been broken in production for about three and a half months without anyone spotting it. We fixed every place the same mistake had been made this time, not just the one that was reported.
Fix
Opening a participant's chat from Table Data
Opening the chat drawer for a participant in Table Data said "request failed with status code 404". No conversation, no explanation, and only on some rows, which made it look random. It was never a permissions problem: the screen was asking for the person by their phone number while the system files them under an internal id, so it looked for a person whose id was a phone number and found nobody. You can read a participant's conversation again, including the people it was silently failing on, and the same fix covers the Media Library and Insights drawers. Phone numbers also no longer appear in web addresses behind the scenes, so they stop being written into server logs.
Fix
The Test Simulator no longer traps you on one question
In the Test Simulator, when a question asked you to pick from options, the message box at the bottom stayed active. If you typed an answer instead of tapping one, the system rejected it and asked the same question again, and nothing stopped you doing it again, so you could sit there answering the same question forever with no idea why it would not move on. Anyone previewing a survey could reasonably have concluded the survey itself was broken. The message box now switches off while options are showing and tells you what to do instead. Tapping and sending work exactly as before and ordinary typed questions are untouched.
Fix
Ask Yazi will not delete a question on a live study without asking
Ask Yazi already asked before editing a question on a live survey, but deleting one slipped through and happened instantly with no confirmation. That is how a question disappeared from a live study while real people were answering it; the person running the study saw an error, could not tell what had changed, and had to stop and ask for help. Every change that could affect people mid survey now has to be shown and approved first, and the underlying gap is closed so a new capability added to Ask Yazi in future cannot end up unprotected the same way.
Fix
Broken skip logic is now caught before you publish
Surveys use rules like "if they answer No, jump to question 12". If question 12 was later deleted or renamed, the rule still pointed at it and nothing checked. The survey engine then quietly sent the participant back to the question they had just answered, looping them, with only a line in a log nobody reads. Those broken rules are now rejected when you publish, with a message telling you which rule is wrong, instead of being discovered by a participant going in circles. We found 22 existing surveys carrying rules like this. All are dormant and none are currently collecting answers, so nobody is stuck today.
Fix
The Share tab tells you what participants are actually seeing
When you were editing a live form, nothing on screen told you what participants were getting. You could make changes and have no way to tell whether they had reached anyone, or whether people were still answering the older version. The Share tab now states plainly whether participants are seeing your published version, whether you have unpublished changes sitting in draft, or whether nothing has been published at all, and if there are unpublished changes it links straight to where you fix them. Two smaller faults went with it: the setup guide was silently discarding your topic and delivery mode settings on save, and the layout broke at tablet width.
Fix
Upload screens now tell you when the file is the wrong type
If you dragged the wrong kind of file onto an upload card, a PDF instead of a CSV say, the screen did nothing at all. No message, no error, nothing moved. On one screen it complained that your file had no phone number column, which sent people looking for a problem in the wrong place. Three of the four upload screens behaved this way. All four now say plainly that the file type is not supported and which types to use, the rejected file no longer sits there looking like it uploaded, and the reminder of which columns your file needs stays on screen while you fix it.
Fix
Hidden questions on a shared results link stay hidden
When you hid a question from a study's public results link, the change saved correctly, but if you navigated away and came back within about ten minutes the question looked like it was showing again. The setting was always right and the page was showing you a stale copy, so what you saw no longer matches what viewers of the link actually get.
Fix
The dashboard's status filter works in card view
On the dashboard's card view, filtering by Status was partly broken. Active and Completed returned nothing at all, and for anyone using the platform in Portuguese every Status option came back empty, with no error, so it just looked like there was nothing there. The dashboard shows campaigns and studies side by side and the two label their statuses differently underneath, and a recent change to how statuses are displayed left the card view matching against the old labels. The filter now matches on the underlying status whichever the record is, and its options use exactly the wording on the status pills. The table view was already working and is unchanged.
Fix
Gaps in the audit trail
Every change to study and campaign data is meant to be written to the audit trail with a before and after snapshot, and that record is what answers "who changed this, and what did it look like before". For certain kinds of update the snapshots were not being taken and the audit entry was skipped entirely. The change itself always saved correctly, so nothing looked broken from the outside, and the failure was logged as a low level warning nobody reads. Over one week alone that was 638 missing entries across seven types of record. An audit trail with silent gaps is worse than an obviously broken one, because you cannot tell "nothing was changed" from "we failed to record the change". Those gaps are closed. Testing against a real database while fixing it turned up a second, unrelated cause affecting six further types of record, which would otherwise have kept quietly dropping entries after the first fix shipped.
43 changes
New feature
Live Rooms: run a group discussion on WhatsApp
Until now a Live Form was a one to one conversation, one participant and one thread. Live Rooms lets several people talk to each other in a shared room they open from a link in their own WhatsApp, with a researcher moderating from the web console. It is the asynchronous equivalent of a focus group and nobody installs anything. Creating one is a single step now rather than a wizard: pick Group Discussion and you land straight in the room, invite people whenever you like, and publish it from the same Publish button every other study has. The room screen uses the same two pane layout as the transcript screen you already know, with a people panel that shows each person's last message and status, a search box, and Remove as the only action. Closing the room closes the campaign, so the two can never disagree about whether the study is running. There is also an Export button so a moderator can pull the discussion to Excel or CSV while it is still going, room media lands in the Media Library with captions from both sides, and there is a full screen image viewer with zoom and download. Two things to know: a welcome message only fires for someone who joins by link, not for a participant a moderator adds to the roster directly, and Ask Yazi does not know Live Rooms exists yet, so asking it whether a Live Form can run a group discussion will get a confident no until that lands.
New feature
Arabic is now a full platform language
Participants can take a survey or an AI interview in Arabic and get every system message in Arabic too: the prompts, the validation errors when an answer arrives in the wrong format, the menu, the consent card and the completion message. Arabic was half present before, so even where it could be selected a participant would have received a mix of Arabic and English. This opens Arabic speaking markets properly rather than partially. Worth stating plainly because it was found while doing this: eight languages we already offer, Sesotho, Setswana, Tsonga, Swati, Venda, Ndebele, Northern Sotho and Welsh, are still missing from most of the AI interview system messages and quietly fall back to English today. That is unchanged by this work and is being fixed separately.
New feature
Test a survey in every language it supports
The Test Simulator could only ever run a campaign in its default language. If you built a survey in English and Zulu, you could preview the English and the Zulu version was untestable in the app, so the only way to check a translation was to run a real WhatsApp conversation. The simulator now asks which language you want the same way WhatsApp does, as the first message of the conversation with a tappable answer, and the rest of the survey runs in whichever you pick. On Flow campaigns the question is asked first and the Flow view then opens in the chosen language. You can proofread a translation before a single participant sees it. It also caught four places where English was leaking into non English surveys, including a progress counter reading "33% complete" in the middle of an Arabic conversation.
New feature
Screener questions now work in WhatsApp Flow surveys
Screener questions were never asked in a Flow survey. They simply did not appear, and because they never appeared, nobody who should have been screened out ever was, so unqualified participants went through the whole survey and counted as completes. Screening is how a study makes sure it is talking to the right people, so a Flow survey with screeners was silently delivering neither the screening nor a clean sample. Screeners are now asked first, and answering with a disqualifying option ends the survey there with a clear message, exactly as it already worked for chat surveys. Relevant to anyone piloting the Flow format.
New feature
Participants can send a document inside a WhatsApp Flow
The question builder let you add a Document question to a Flow survey, but publishing that survey always failed and there was no obvious reason why. You can now ask participants to send a PDF, Word doc, ID document, receipt or similar without leaving the survey. Photos already worked this way and documents were the missing half. A related tightening shipped with it: if a question type genuinely cannot be built as a Flow screen, publishing now fails loudly and names the question, rather than quietly shipping a screen with a question on it, a Next button, and nothing to answer with.
New feature
Location questions work on a Live Form
A location question was impossible to answer on a Live Form. Sharing your location failed with "Could not send your location" and typing an address failed with "Search failed", so any study that asks where someone is had to go out over WhatsApp instead. Both are fixed, and researchers can now add a Location question to a Live Form in the first place, which the builder was previously hiding. Answers save with coordinates and a readable address and appear in results like any other answer.
New feature
Pipe answers into and out of a matrix question
Two related pieces of piping landed this week, both driven by agency questionnaires that could not run on Yazi before. A matrix question can now take its rows from an earlier single or multi select, so each participant is only asked to rate the options they themselves picked. And a matrix can now be the source: a later single select, multi select or matrix can be piped from it, with an "Only rows rated" control to choose which rating columns qualify, so you can ask "which of the brands you rated Excellent or Good is your favourite" and the question is skipped for anyone with no qualifying rows. Results and SPSS exports show one column per possible row. Scope, stated plainly: this is in-chat surveys only. Piping into matrix columns is not included, and Flow surveys and Live Forms cannot resolve a per participant list yet, so the builder says so rather than accepting the setup and dropping it at send time.
New feature
Participant photos are now analysed inside the EU
Photos participants send were being sent to the United States to be analysed. Voice notes were already handled in the EU, but images were not, and those photos routinely show faces, homes, receipts and locations, so identifiable personal information was leaving the region. Photos are now analysed in the EU, in the same region as everything else, and nothing about the feature changes for users. This matters for contracts rather than for workflow: POPIA and GDPR both ask where data is processed, our data processing agreements commit to the EU and UK, and this was the last remaining gap of its kind. We can now answer that question honestly, which we could not do a week ago.
New feature
Publish a product announcement from inside the app
The release spotlight that opens on the dashboard can now be written and published from Settings, Global Admin, Product announcements, with no developer involved: write it, upload a video and thumbnail, preview it, publish it. A published announcement opens once for each person on their next dashboard landing, and there is a stats view showing reach, the median time the pop-up stayed open, and viewings over time. Two rules are worth knowing because they are enforced by the design rather than by convention. Only one announcement is live at a time, so publishing a new one archives the current one and a user returning after months meets the latest rather than a backlog. And each person sees an announcement exactly once ever, following them across devices, so re-publishing the same announcement will not reach anyone who has already seen it. To reach them you need a genuinely new one.
Settings, Global Admin, Product announcements, showing the announcement list with draft and archived items and the New announcement buttonNew feature
The partner API can be paged and retried safely
Two things were fixed on the API partners integrate against rather than using the dashboard, both found by testing it properly against production before handing over documentation. If a partner's system timed out sending a WhatsApp message and retried, nothing stopped the respondent receiving it twice, which is worse on a broadcast where one retry re-messages a whole group. And asking for the first two studies returned all 211 while claiming there was nothing more to fetch, so anyone building a page-through loop would have silently pulled the whole table every time and believed it was correct. Both are closed, and there is now a machine readable API spec so an integrator's engineers can generate their client instead of hand writing it from prose.
Improvement
Translations keep themselves up to date, and your export respects the language you picked
Translation only ever ran as a one-off job covering the answers that existed at the moment a study was set up. Nothing re-ran it, so every answer that arrived afterwards stayed untranslated permanently. On one reported study the job ran on 14 August and the first response arrived on 23 August, so all 158 answers were missed. This was not one study: 42 campaigns and roughly 3,500 answers were affected. Translation now keeps itself current, so answers arriving after setup are covered automatically. Two related faults went with it. Translations written by the job sat underneath a cache that nothing cleared, so opening the responses tab and reloading gave you the same untranslated data unless you happened to press the table's Refresh button, which nothing tells you about. And on any study small enough to load in one page, the export's "Translate to English" or "Leave as written" choice was being thrown away and you got the same file either way. Both are fixed, for CSV, Excel and the status filtered export.
Improvement
Completion now means one thing across the whole platform
Whether a participant had completed was never stored anywhere. Six separate places worked it out on the fly and disagreed, which is how one diary study came to report more Day 5 completions than Day 4, which is impossible in a sequential study. On that study the Participants funnel read 6 for Day 4 where the dashboard read 15. Completion is now recorded once, at the moment a person finishes, and backfilled to 95,633 participants, and every screen that counts reads the same recorded fact. Surveys, recurring studies and diaries did not move at all, verified campaign by campaign. All the movement is on Interview campaigns and it splits two ways: participants who took the action that deliberately skips the AI interview were being dropped by the funnel and are now counted, and people who finished only the screener without ever answering an interview question were being counted by the campaign page and now are not. Worth knowing if a number looks different: on an Interview campaign the campaign page may show a lower figure than before. That is the definition tightening to match what the dashboard and Participants tab have always shown, not data loss. Two related corrections shipped with it in the participant drawer, where the reliability score was counting campaigns the person was never actually messaged on, and the outcomes bar was counting a diary participant's 30 sessions as 30 campaigns.
Improvement
The numbers on a campaign agree with each other, and the labels say what they mean
Three fixes to make a campaign's reported figures trustworthy. Graph Data was quietly counting the practice responses we create while building a campaign as real participants, while the table underneath was correctly leaving them out, so the two disagreed by exactly the number of test runs. We checked 20 live campaigns and 6 were affected. Separately, the rule for "people who actually answered something" had been copy pasted into seven different places and had drifted, so the same person could be a respondent on one screen and not another. That is now one shared definition all seven read from. And the labels themselves were misleading: the dashboard said "Started" and Graph Data said "TOTAL REACHED" for what looked like the same thing but was not, and "Reached" sounds like everyone you contacted, so people expected it to be the larger number when it was the smaller one. Two correct figures looked like a bug and got reported as one. Started is now Opened, people who opened the survey and began, and TOTAL REACHED is now RESPONDED, people who actually sent an answer, on all seven screens including the mobile views. One more small thing in the same family: a campaign in Testing status now shows its own test data by default, which is the one state where test data is the whole point and was the one state that hid it.
Improvement
The builder now warns you before WhatsApp drops an option or a row
Two limits were being enforced silently. A "select all that apply" question can only carry 10 choices on WhatsApp, and anything past that was binned before the message went out, so the participant never saw it and it never appeared in the results. There was a sting in the tail: switching on "Other", "All of the above" or "None of the above" each uses one of the 10 slots, so the real limit could be 9, 8 or 7 and nothing on screen explained why an option had vanished. A matrix question has the same 10 row ceiling, and an eleventh row was quietly dropped, with the only trace a line in a server log. The builder now warns while you type, states the real limit for your settings, and blocks publishing until it is fixed. The matrix warning also catches two cases that are easy to miss: clearing the text of a row in the middle still costs you a row further down, and turning on Randomize Rows means the row that gets dropped changes with every send.
Improvement
AI interviews now use every question you give them
If you set an AI interview to ask 6 questions, it was only ever planning 5 of them around your topics. The sixth went out unguided, with the interviewer picking whatever it felt like, and on shorter interviews it was worse, because one of your key topics could be dropped entirely and never asked with nothing in the results saying so. The builder was also under-reporting, telling you the interview was one question shorter than it actually ran and attributing the missing one to "required questions and the wrap-up" on studies that had neither. The cause was a slot held back at the end for must-ask questions, reserved even when a study had none. That slot is now only reserved when you have actually added required questions, the builder's summary line matches what the interview really does, and where a slot genuinely is reserved it says what for. Running studies simply get the extra question back, no action needed.
Improvement
Study creation now tells you the truth about when activities go out
If you set up a study with several activities, a "3 day" study for example, the setup screens made it look like each one would go out a day apart. In reality all of them were sent within about five minutes of each other with no warning, which makes the collected data effectively useless, and nobody found out until participants had already answered everything at once. Study creation now counts activities rather than implying a day by day schedule, and every screen in the flow, the setup step, the AI assisted proposal and the final review, states the real delivery timing. The "Manual" progression option has been removed from study creation as well, because it had not changed how activities were delivered since an earlier redesign, so leaving it there was misleading rather than a real choice. Genuine day apart scheduling is separate work and is not done yet.
Improvement
Screens that used to hang now load in about a second
A run of database work this week turned several of the slowest screens in the product from unusable into instant. The four stat boxes at the top of the People screen took 90 to 117 seconds on a large organisation and never got faster on a second visit, which is long enough that most people would reasonably assume the page was broken. They now load in under a second with every number unchanged, and the list underneath them dropped from about a second to a quarter of a second. Opening a participant's transcript went from about three seconds of database time to under three milliseconds, roughly a thousand times faster, because it had been reading through all 138,759 participants on the platform to find the one person you asked for. The rewards and incentives approval screen went from about 18 seconds on a large campaign to effectively instant, which matters because that screen is where real money is approved and an 18 second wait is the kind of thing that makes someone refresh or double up on an action. Enriching a participant CSV went from 9 seconds to 5 milliseconds, and deleting selected survey results, loading AI interview results and opening a transcript on an anonymised study all got the same treatment. Underneath all of it, eight missing database indexes were added, a planner setting that had been telling the database it was running on a spinning hard drive since the instance was created was corrected, four tables that had never once been tidied up were tuned, and a de-duplication table that had grown to 1.16 million rows when it only ever needed a day's worth now clears itself nightly. None of these were the direct target of any one screen, so screens nobody was working on got faster too.
Improvement
One file upload design across the whole app
Every place you attach a file now uses the same upload box and the same attached-file row: feedback screenshots, CSV imports, campaign briefs, broadcast header media, logos and question media. There were seventeen separate upload areas, each built one at a time and drifted apart. Several of the differences were real bugs rather than styling. Nine of them said "drag and drop" while having no drag support at all, including People, Import, one of the most used, so dropping a file on them did nothing. If a customer ever said they dragged a file and nothing happened, they were right. The Feedback page never showed your image thumbnail on any browser and always fell back to a grey document icon. In most places, removing a file and then picking the same file again did nothing, so you had to choose a different file or reload. You can now tab to an upload box and press Enter to open the picker. And a few file-type lists were simply wrong: the campaign brief accepted.doc without ever saying so, and the campaign import said "CSV or Excel" while rejecting.xls files. Dragging a contact file onto the broadcast upload card now uploads it as well, where before the browser just downloaded the file into your Downloads folder.
The People, Import dialog showing the shared upload box with working drag and drop and an accurate CSV, XLSX or XLS file-type lineImprovement
The Dashboard and Broadcast Messages tables scroll instead of paging
Both tables have moved onto a new shared table. The Page Size selector and the "1 to 20 of 37" footer are gone: the list just scrolls and the row count shows live, so you can see at a glance how much is there. Global search now matches what you can actually read in a cell, including formatted dates, so "Sep", "Aug 10" and "2025" all find rows where before they found nothing. The filter builder with its AND and OR chains, sorting, chips, row actions and row selection all work exactly as they did. This was deliberately a like for like replacement rather than a redesign, so it should look very close to what was there, with slightly lighter chip fills and a header tint that now spans the full scrollable width. It covers Dashboard activities, Broadcast Messages All broadcasts and Send History, and the broadcast detail panel's recipients table.
Improvement
A proper calendar on every date field
Date fields across the app now use a Yazi calendar instead of whatever popup your browser happened to provide, which looked different on every operating system and could not be styled to match anything else. Dates read as "3 Sept 2026" rather than "2026/09/03", and clicking a field opens a calendar with month and year dropdowns. It is on the Scheduled Messages reminder start date, the study unlock rule, participant date of birth, and the billing "Live from" fields. Nothing changed about what gets saved. Two faults were closed with it: a stored date of birth was rendering as an empty placeholder even though it had saved correctly, a long standing gap that the old browser control had too, and clicking today in the Start Date calendar silently emptied the field so you could not confirm today as a start date.
Improvement
Clearing the search on the Dashboard actually clears it
Clearing the search on the Dashboard studies list emptied the search box but left the table still filtered, so you saw a shrunken list with nothing obviously filtering it and the only way back to all your studies was a full browser refresh. Switching to another menu item and back did not help. Clearing now restores the full list, there is a new cross inside the search box so you can clear just the search without touching any filters you have added, editing an existing search now searches all your studies again instead of only inside your previous results, and the "X of Y" count beside the box always matches what the table is showing. On tablet width screens the search box could disappear while the table was still on screen, which is closed too.
Improvement
Four rough edges gone from the question builder
The first question you added to a new study always came out as a plain Text question with no way to pick anything else, so researchers were creating a question of the wrong type and switching it afterwards. Attaching a photo to a question gave you no way to click it and check it was the right image, and a long caption got clipped down to the last few words with no way to see the rest. Dragging a question to reorder it would not scroll the list, so anything past the first screenful meant drag, drop, scroll by hand, then drag again, and on the Research Objectives list it had never worked at all. All three are fixed. Two more editing faults went with them: the cursor could land in the wrong place while typing, most noticeably after making text bold or italic, and renaming a survey or study could save a partial name if you typed quickly, or roll the title back to a stale value if a save failed.
Improvement
Live Forms: broadcasts, test resets and a stray rejoin prompt
Three fixes on the browser version of a survey. Send broadcast opened on a Live Form campaign but could not be completed, because the campaign you were standing on was not in the "Campaign or Study" list at all, so the Next button stayed greyed out and there was no way to finish the send. Inviting people over WhatsApp is the main way anyone joins a Live Form, so the only workaround was to give up on the broadcast. The same problem on the Templates page and the scheduled message form is fixed too. Adding -TEST to a starter phrase, which is how you wipe your own test answers and start clean, deleted nothing on a Live Form while reporting success in the logs, so old answers leaked into every retest. It now really clears that number's session, and as a bonus a participant who reopens their link, or opens it on another phone, carries on where they left off. And the "I have a rejoin code" prompt, which is meant to appear once at the start, was leaking into real question cards and showing up underneath things like "Question 2: Upload a photo" as though it were part of the question.
Improvement
Every photo in a participant's transcript, not just the first
When someone answered a photo question by sending several photos at once, the transcript showed only the first one. The others were never lost, they were saved correctly the whole time, but nobody could see them on screen or in an exported PDF. So a researcher reviewing or quoting that transcript was working from a fraction of what the participant actually gave them: if a respondent sent four photos of a shop display, you saw one and had no hint the other three existed. This comes up most on diary studies. All of them now show.
Improvement
You can now see why participants are getting stuck on a question
When a participant answers in a way the survey cannot accept, we ask them to try again and record the reason. There are twelve different ways an answer gets turned down and we were only saving the reason for two of them. The ten we were missing are the everyday ones: tapping an option that is not on the list, or choosing four when the question allows two. Anyone counting these was seeing a small fraction of what actually happened. All twelve are recorded now, so a question where people keep picking too many options shows up as a question that needs rewording, which was previously invisible.
Improvement
Voice note transcripts are readable on a public share link
Voice note transcripts were being replaced with "[transcript hidden]" on public share links. The redaction was protecting nothing, because the audio itself is served and playable on the same link, so hiding the text withheld nothing a recipient could not already hear and simply deleted the answer. On a qualitative study where every microphone question is answered by voice, that meant the share link delivered a page of unreadable waveforms. Transcripts now render. Identity redaction is untouched: participants are still masked and no phone numbers are in the payload.
Improvement
Every switch in the app tells a screen reader what it controls
Every on and off switch in the app had lost its label, so someone using a screen reader through Settings, the study review panel or the share visibility list heard only "on" or "off" with no idea which setting they were changing, and on a screen with several switches in a row they were impossible to tell apart. They announce properly now. Related fixes went with it on buttons, where an accessible label written on the tag was silently not reaching the control a screen reader queries. This was invisible to anyone testing by eye: the screens looked normal, the build was green and nothing errored.
Improvement
NeuralHub's Portuguese console has four more English surfaces closed
Four places where English was still reaching a white-label customer whose contract says they never see it. The screen that lists what needs fixing when a study will not launch was appearing fully in English at exactly the moment the user most needs to understand what went wrong, and is now Portuguese throughout, heading, error labels, guidance and the success confirmation. The Add People modal, the CSV import and the broadcast screens, five surfaces all one click from a tab that had already been translated, went from 112 hardcoded English strings to none. Sign-up errors came back in raw English from the login provider no matter what language the workspace was set to, so a Portuguese user hitting a wrong password or an expired code got an English technical sentence, and six old sign-in code paths that could do the same thing are now gone with a test that fails if anyone adds them back. A second, quieter fault went with it: someone invited to a workspace who already had an account used to dead-end on the sign-up page and is now sent to login with the invite still attached.
Improvement
Locations and photos sent between activities are stored properly
When a participant sends a WhatsApp message outside an active survey, for example between two days of a study or before they are enrolled in anything, we save it so the answer is not lost. If that message was a location pin we were keeping only the coordinates as a line of text and leaving the proper location field empty, and photos and other media had the same gap. Both are now saved in full. Nothing was ever being lost, but it was stored in a form nothing could use: with the location stored properly you can filter answers by area, plot them on a map or join them against other location data, where before someone would have had to pull the numbers back out of a sentence by hand.
Improvement
The shared component set now covers buttons, alerts, badges and type
The long sweep to put the whole app on one component library carried on this week across four fronts. Every alert and warning banner in the app is moving onto one component, about 40 of them so far with roughly 60 hardcoded colours deleted. Buttons are following, with around 150 migrated so far, which fixed a real problem along the way: several groups of buttons had been rendering as raw unstyled browser chrome, a grey slab with black text, because the style they asked for had no rule anywhere in the app. The study review panel had 16 of those, which is why it may have looked slightly unfinished, and the Delete button in Panel Recruitment has been grey all this time when it was always meant to be red. Every status pill in the app now comes from one badge component, all 14 participant funnel colours preserved exactly. And about 3,700 hardcoded font sizes across roughly 200 stylesheets moved onto one shared type scale, which is presentation only: sizes and weights are preserved, with slightly more generous line spacing on dense labels. A handful of small visual faults surfaced and were fixed in passing, including page headings on Dashboard and Scheduled Messages rendering at 14px instead of 20px, a filter bar that looked like it faded out across its own width, and a mobile problem where an alert's action button could sit on top of its own title and make it unreadable.
Fix
Graph Data was hiding the whole survey section on interview campaigns
On one campaign the Graph Data tab showed 22 reached and 0% completion against a list of AI interview probes, with all 26 survey questions missing. The real numbers were 245 reached and 184 completed. Graph Data was treating the survey results and the AI interview results as either/or: the survey half only ran as a fallback when the AI half came back empty. Every Interview campaign has a survey section before the AI takes over, so a single AI multiple-choice question was enough to hide the entire survey, questions and respondents both, and the completion rate read 0% for the same reason because session status lives on the survey side. Both halves are now aggregated and merged, survey questions first, then the interview questions in the right order with the right labels. A PowerPoint export fault went with it, where interview slides were colliding with survey slide numbers. The flaw had been dormant since June and only surfaces on campaigns with "allow multiple choice" switched on, which is three platform-wide. No data was lost at any point, this was purely a reporting read.
Fix
An AI interview could be skipped when the last survey question was optional
If the final survey question on an Interview campaign was Optional, tapping Skip closed the participant out with "Thank you for completing the survey" instead of handing them to the AI interviewer. The same happened on the "Other" free-text path. The wrong status then deleted the participant's message route and stamped the completion record, so nothing ever retried and the bug hid itself. On one study 36 people were reported as completed but only 16 had actually done an interview, and 8 of the other 20 replied afterwards into a route that no longer existed. Verified live on production after the fix by driving a real WhatsApp conversation through it. Not fixed by this: the participants already affected. Their routes are gone and they are several days cold, so reopening a conversation with them needs a template message, which is a decision for the study owner rather than something we can do quietly. A related gap closed with it, where a block rule labelled "End of survey" was skipping the interview on an Interview campaign, meaning there was no way to reach the interview from a block rule at all. That one was latent, no participant was ever affected.
Fix
Broadcast schedules could switch themselves off, and a failed send could block a recipient forever
Three faults in the same area, all found from one incident. Meta declines a send in two ways, and only one of them carried an error code. The uncoded case slipped past the guard that pauses a schedule for ten minutes and went straight into the circuit breaker, which deactivates a schedule after three failed ticks. So when Meta held sends for one organisation for about fifteen minutes, which at a five minute poll is exactly three ticks, three schedules were permanently deactivated by something that cleared a minute later, and roughly 1,300 recipients sat unsent for over four hours. Separately, a failed send was being recorded in a way the "has this person already been messaged?" check counted as a real message, so any recipient with a failed attempt was silently skipped from then on, permanently, with no log and no retry. That morning's fifteen minute hold produced 365 such rows and blocked all 365 people. And a schedule that claimed recipients but dispatched none of them was indistinguishable from an idle tick with nothing to do, so it was recorded nowhere: one campaign sat in that state for sixteen days with 52 recipients never messaged and no alert. All three are closed. A short outage now costs a ten minute pause rather than a dead schedule, failed sends can be retried, and a schedule making no progress deactivates itself within about fifteen minutes with a reason posted rather than going quiet indefinitely.
Fix
A participant messaging in before enrolment could be shown another organisation's name
When someone messages one of our WhatsApp numbers and is not enrolled in anything, we reply telling them who we are and where to find us. On the shared number that 539 organisations use, the system was picking one of those 539 at random, so a participant could be shown a completely unrelated organisation's name and website. That is a client confidentiality problem as much as a confusing experience, and it was happening every time rather than occasionally. The reply is now branded from the campaign the participant was actually trying to reach, and where there genuinely is not one to go on it shows the Yazi default rather than guessing. Organisations with their own dedicated WhatsApp number were never affected. Two related gaps closed the same week: an organisation's AI instructions could be saved against a different tenant's WhatsApp account when two organisations share a name, which now refuses rather than guessing, and the internal alerts that name an organisation when a message fails now use the send record for that exact message rather than picking a name from the shared pool.
Fix
Photos sent in a batch could go missing without anyone being told
When a participant sends several photos at once we hold them briefly so they are treated as one answer. If the machine that came to process them could not reach the queue holding them, it found nothing and moved on, so the photos vanished silently even though they had been saved correctly. No error, no message, nothing in the conversation to suggest anything had gone missing, and the participant believed they had sent them. Those photos are the research data, and losing them quietly is worse than failing loudly because nobody knows to ask again. The system now rebuilds the answer rather than giving up, retries a bounded number of times, and only asks the participant to resend once it has confirmed the photo really is gone. If it cannot tell either way it holds on rather than guessing. A related annoyance went with it, where a participant could be asked to resend the same photo twice.
Fix
The apology after a photo batch no longer sounds like a rejection
When one stray item in a batch of photos arrived in a format WhatsApp could not hand to us, we replied "Sorry, we couldn't read that last message. Your other answers came through fine, please send it as a normal photo", and it went out after the answer had already been saved and the survey had moved on. It read as though we had refused their photos. It was also making a claim we had no way to check. The message now says only what we actually know: one part of that message could not be opened, and if it was your answer, send it again. Updated in all 18 languages.
Fix
Deleted and unpublished studies could still take participants
Two doors were open. Deleting a study removed it from the dashboard, but the code deciding whether a study was open only checked its status, which deletion does not change, so five deleted studies on production still had working joining codes and anyone holding one from an old message or a shared link would have been let into a study that no longer exists. And an unpublished study still handed out working WhatsApp links for each of its activities: the main "start here" link was correctly locked with a "publish the study first" message, but the per-activity links right underneath it were live and copyable, so a real participant could be dropped into a study with no questions in it, skipping the schedule entirely. Both are closed, and the system now turns people away with an explanation if they arrive on a link copied earlier rather than going silent. We checked the live records before changing anything and nobody had actually been let in either way. Paused, closed and draft studies still resolve deliberately, so a participant messaging one is told the study is paused rather than hearing nothing, and Testing mode works exactly as it did.
Fix
Cross-organisation gaps in the AI interview service are closed
A sweep of the AI interview service found around 50 endpoints that checked who you were but never which organisation you belonged to, and one that asked for no credentials at all. The five that mattered most are fixed. One endpoint needed no login whatsoever and could disconnect a live agent conversation in any organisation. Another let a logged-in user of one client take over a participant's live WhatsApp conversation belonging to a different client and read the full history. Two more could deactivate another client's participant mid-interview, and the test simulator could read, write into or delete another client's messages. Nothing suggests any of it was used, and we found it ourselves rather than being told about it, but the exposure was real. A related fix landed on the signature check that proves an incoming WhatsApp message genuinely came from Meta, which could pick the wrong organisation's key when two share a phone number.
Fix
Saving and deleting questions broke for about two hours on 2 September
Between 08:38 and 10:20 SAST on 2 September, anyone editing or deleting questions on a study got an error and lost their edit. Saving a set of questions, deleting a question, deleting a campaign, deleting a study and duplicating an activity were all affected, 135 failed requests across 11 campaigns and organisations. Study building was effectively blocked for anyone who hit it. No data was lost or damaged: every failed request rolled back cleanly, so nothing was half saved and the only cost was unsaved edits people had to redo. The cause was a database function carrying the wrong version of its code on production for four months, which our integrity check could not catch because it only ever confirmed the function existed by name. It now compares what the function actually does against what the migration declared, on every change.
Fix
Removing people from a multi-day study looked like it had deleted everyone
Removing a group of participants from a multi-day study was taking around 50 seconds. Browsers give up at 30, so you got an error even though the removal was quietly finishing in the background, and the screen then kept showing the people who were already gone, so the next click looked like it had wiped the whole list. It now takes about a second and a half, you get a clear result, and the list updates itself. Three smaller things were fixed with it: a failed action was showing its error message in the green success colour and leaking raw technical text, the Broadcast button was the wrong colour, and on a phone the last button in the bar was cut off the screen.
Fix
The status menu on a study could freeze the screen or open behind the sidebar
Clicking the status pill on a study's Build screen could freeze the whole screen instead of opening the menu, and the only way to recover was to reload the page. Separately, on the study page the same menu opened underneath the ACTIVITIES rail, so the options were unreadable and partly unclickable. Both are fixed, and the menu now also dismisses properly on Escape and on an outside click and clamps itself to the viewport, which were hand-rolled or missing before. The same duplicated menu on the campaign page was fixed in the same change.
Fix
A raw code appeared instead of the participant's own answer on Flow surveys
Researchers can write a question that quotes back an earlier answer, for example "Why do you like {{Q8.answer}}?", which should read "Why do you like Western Cape?" once someone has answered. That worked in chat surveys but had never worked in surveys delivered as WhatsApp Flow screens, where the participant would have seen the raw code instead. Quoting someone's answer back to them is a large part of why a survey feels like a conversation rather than a form, and a raw code breaks that instantly. It now behaves the same way in both delivery modes, so nobody has to remember which one silently drops it. Worth saying plainly: nobody was ever shown a broken question. We found this on a study that had not been published yet.
Fix
The Panel Recruitment tab was stuck on "Loading…" and never finished
Campaign, Share, Panel Recruitment hung on a loading spinner indefinitely, in production and everywhere else, so the tab was unreachable. The data was always fine, the page just never painted the result. It renders again.
28 changes
New feature
Airtime rewards now reach Côte d'Ivoire, DR Congo, Togo and Benin
Airtime incentives were Nigeria only. Four more countries are now selectable in campaign settings, which opens francophone West Africa for studies that pay participants in airtime rather than vouchers. Côte d'Ivoire, Togo and Benin pay out in XOF. DR Congo pays out in US dollars rather than Congolese francs, because every operator there settles airtime in dollars, so 14,000 FC needs to be configured as roughly $6.10. Two things tightened up with it. Airtime is now one country per campaign, because the provider detects the mobile operator within a single country and a multi-country airtime campaign was silently paying out only for whichever country sorted first. And the currency override is hidden for airtime, because the provider ignored it while the credit ledger did not, so an override could bill an organisation 3,500 in the wrong currency for about $6 of airtime. Reward amounts are also range-checked against the detected operator before sending, so an out-of-range amount fails with a readable reason. Togo is live but unverified: both operators are active with our provider, but operator detection returned nothing for every Togolese prefix we probed on the test tenant, so check it against a real payout before promising it to a client.
New feature
Matrix questions on WhatsApp fit on one screen
A matrix question asks people to rate several things on the same scale, and on WhatsApp it used to render every scale option as its own row of radio buttons. Three items on a five-point scale meant fifteen stacked rows. Participants scrolled a long way and could never see the items together to compare them, which is the whole point of asking a matrix question in the first place. Each row was also labelled "Statement 1", "Statement 2" rather than what it actually said. Each item now shows its real wording with the scale as a row of tappable chips underneath, so a five-point scale takes one line instead of five and each answer is a single tap. Where the scale wording is long enough that WhatsApp would cut the chips off mid-word, those questions switch to a dropdown per item instead, and the builder tells you which layout your question will use while you are still writing it. We separately confirmed that long attribute statements are safe: WhatsApp wraps the statement as a full-width heading up to 80 characters and we already trim at exactly 80, so brand-tracking statements like "This brand offers good value for money" arrive whole.
New feature
Match your own column names when you import people
The People import used to guess your spreadsheet's columns from a fixed list of header names and never showed you what it had decided. Anything it did not recognise, like Mobile, Given Name, Province or Household Income, silently became a custom field instead of the real column it belonged in, and a file whose phone column was not named one of four exact things was rejected outright. Import is now three steps: upload, match your columns, import. Yazi auto-matches what it recognises and then shows you every column with a sample value and where it is going, so you can re-point anything that is wrong. A field already claimed by another column is greyed out. A file with an unusual phone column now reaches the matching step and imports fine once you point at the right column. Worth knowing: unmatched columns still become custom fields on the person rather than being left out, and they are hidden by default on the People table, so switch them on in the Columns control if you want to see them.
New feature
The builder warns you about a hand-typed question counter
Researchers sometimes type a progress counter straight into their question text, like "Q5 of 12". It reads as helpful, but it is a snapshot of the question count at the moment it was typed and nothing ever updates it, so adding or removing a question quietly turns it into a lie told to every participant. Of the 22 hand-typed counters live on production, 20 state a total that does not match the real number of questions in their survey, across 7 campaigns and 6,426 participant sessions. The two that are right are only right by luck. The builder now warns as soon as you type that shape and points you at the progress indicator the platform already generates and keeps correct on its own. Being straight about the limit: this is a nudge, not a block, it covers the three places a person types question text by hand, and it does not correct the counters already out there or catch text that arrives from the AI generator or from duplicating a campaign.
New feature
Correct a project's rate after it has been set
A rate could only ever be set on a project that had never been priced. If the wrong one went on, wrong tier, wrong category, or a negotiated price typed in error, there was no way to fix it from the app and the project carried on billing at the wrong price. Plan and Usage now shows a Change rate option on any project that already has a rate, and it opens on the rate the project is currently on so it is clear what you are changing from. For organisations on a bundle there is also an explicit tick to return a project's drawn value to the pool. It only appears where it genuinely makes a difference and it says what it will do before you commit, because bundle value is otherwise spent for good. Platform admins only, nothing changes for customers.
New feature
A warning when an organisation's reward credits run low
Campaign, Participants, Reward Approvals now shows an inline warning when an organisation's incentive credits are running down, with the remaining balance. It appears at 75% of purchased credits used or at a zero balance, and only while approvals are still pending. Advisory only: nothing is disabled and approving works exactly as before.
Improvement
The shared component set reaches dialogs, radios and the last of the dropdowns
The sweep that moved the app's inputs, dropdowns and toggles onto one shared component library carried on this week and is now essentially done. Every confirm and alert dialog in the app, around 55 of them across roughly 38 files, comes from one component instead of each screen having its own icon, buttons and typography. Radio groups joined the set across campaign quotas, export options, API keys, panel recruitment and MFA setup. Three visible faults the earlier sweep had left behind were fixed with it: dropdown text was cutting the tails off the letters g, j, p, q and y, most obviously on "English" in the language pickers, across all 158 dropdowns and every multiselect; the Create Schedule modal drew a double border around seven dropdowns; and the activity and campaign name field did the same. Fifteen orphaned components, about 4,800 lines, were deleted along with a control in the brief upload step that turned out never to have rendered at all.
The Create Schedule modal, showing the Select Broadcast dropdown now drawing a single border in line with the text inputs and toggle below itImprovement
Notifications all come from one place now
Every notification in the web app renders through one toast component, bottom right, sliding in from the right, click anywhere to dismiss. Around 640 call sites moved onto it, along with the export progress banner, the categorisation banner, the report-generation banner and the translation progress banner. That last group matters more than it sounds: several of those banners sat in the toast's exact corner at a lower layer, so a toast simply covered them. The same was true of incoming WhatsApp message notifications, which were being drawn underneath any toast that happened to be up and now arrive as a toast with a "View chat" action. The look and position were picked by a team vote.
Improvement
The database is meaningfully faster
Our production database is small, only 3.8GB, and should sit almost entirely in memory. It did not, because several of the tables we read most often had no index on the column every query searches by, so the database was reading them front to back over and over. One 8MB table was scanned end to end 4.4 million times. A separate setting had been left on its default since the instance was created, telling the database it was running on a spinning hard drive when it is actually on SSD, which pushed it further toward the slow approach. Nine missing indexes have been added and that setting corrected, with no downtime and nothing locked. Fetching messages for a busy campaign went from 2.2 seconds to 2 milliseconds. The inbound WhatsApp de-duplication check, which alone accounted for about a third of all query time on the database and two thirds of every physical disk read, now runs in a fraction of a millisecond instead of occasionally taking five minutes. Everything on the platform shares that database, so screens that were never the direct target benefit too. Groundwork for the slow People and results screens, which are next.
Improvement
Transcripts say when a question has been deleted
When a survey question was deleted or edited after someone had already answered it, the transcript could no longer look that question up, and instead of saying so it simply left the question out. You were left reading an answer with no idea what it was answering. On the worst example in production one transcript had five answers in a row with no visible question at all. Where the question can no longer be found, the transcript now shows a clear "This question is no longer available" marker in its place, so the gap is visible rather than invisible. Answers, timings and any images attached to the question are all kept. This affects about 6,200 answers across production today.
Improvement
The Transcripts list is readable on a big screen
The list of conversations a moderator can open was breaking phone numbers across two lines mid-digits, so a number rendered as 2772129 on one line and 7313 on the next. A phone number split in half stops being readable as a number, and that number is how a moderator identifies who they are talking to. The list was also pinned to a fixed width whatever the screen size, so a large monitor got the same cramped column as a laptop with the rest of the window sitting empty. Numbers now stay on one line, the list grows with the window up to a sensible limit, and the space freed goes to the participant's name and the campaign label.
Improvement
Deleting a transcript tells you what else it will do
Deleting one participant's transcript on a multi-activity study also wiped their study progress behind the scenes: completed activities cleared, and any messages already queued to go out to them cancelled. The dialog only asked whether you were sure you wanted to delete the transcript, so there was no way to know. The reset itself is intentional, it is what gives you a clean slate when you are retesting a single participant. What was wrong is that nobody was told. The dialog now spells out exactly what the delete will do before you commit to it.
Fix
A phone number typed the local way no longer goes to the wrong country
When someone entered a number the local way, starting with a zero, the system assumed it was South African and put 27 in front of it. So a Kenyan number written as 0712345678 became a perfectly valid South African number. It passed every check, the send reported success, and the message went to a stranger in another country. The person who was supposed to receive it never did, and nothing on screen showed it. A wrong-country delivery is worse than a failed one, because a failure is visible and a misdelivery is not. If a number does not say which country it belongs to, Yazi now asks you to pick one instead of guessing, and tells you plainly which numbers need attention. The same fix covers Nigeria, Uganda, Tanzania, Ghana and everywhere else we run research. A second half shipped with it: when WhatsApp refuses to deliver a message, the screen used to show an internal code, `REQUEST_ERROR`, next to the number while WhatsApp's actual explanation was received and thrown away. The downloaded error report had the same gap. Operators now see the real reason both on screen and in the export, so "this number is not registered on WhatsApp" can be told apart from "something is broken". Worth correcting the record: this was originally filed as a Kenyan phone-validation problem after an error code was read as evidence the number was invalid. Kenya was delivering normally that day, 100 invites sent and 70 delivered.
Fix
Study exports no longer leave activities out
On a multi-activity study the results page loads activities in waves and the Export button goes live as soon as the first one lands. Export then skipped any activity with no campaign attached, but an activity that has not loaded yet is indistinguishable from one with no data, so exporting during that window produced a file silently missing whole activities with no warning. One study exported two of its segments with only days 1 to 3 of 5 and the client began analysis on the short files. No data was ever lost, days 4 and 5 were always in the database. Every export path now waits for the activity load to finish, re-fetches anything unresolved, and refuses with a named error rather than writing a short file. Re-exporting returns all days.
Fix
A participant who sends a photo is no longer told we do not support reactions
Participants who had just successfully sent a photo were getting an apology back saying we do not support reactions. On one study this happened 50 times in a week across 39 people. They reasonably concluded their upload had been rejected and that they had done something wrong. No data was lost, but a confusing apology mid-survey is exactly the kind of thing that makes someone re-send or give up. WhatsApp tells us a message was unreadable but never tells us what it was, so naming "reactions" was a guess and usually the wrong one. The reply no longer names a message type and reassures the participant that their other answers came through. A genuine thumbs-up now gets no reply at all, since reacting to a question is not a failed answer.
Fix
French, Portuguese and Spanish messages have their accents back
Ten of our WhatsApp messages had the accents stripped out, so participants were reading things like "Ola! Voce nao esta atualmente inscrito" and "plus tard dans la journee". To a native speaker that reads the way "later in the dav" reads to us, on a surface where we are asking people for their time and attention. The affected messages included the one we send when someone is not enrolled in a study and the ones telling participants when their next activity opens. All corrected, Spanish also got its opening inverted exclamation mark back, and there is now a check that fails the build if a stripped string is ever added again.
Fix
A message from someone not in a study is no longer thrown away
When someone messages us who is not enrolled in any study, we reply to them politely and then discarded what they said. It never reached the database. Measured on production before the fix: roughly 1,206 messages a week, from about 1,055 different people, all dropped. Some of those are a stray "hi", but some are people telling us something real about a study they were part of, or asking why they stopped receiving questions. Their messages are now stored, the same as we already do for people who go quiet mid-study.
Fix
A shared tracking code can no longer send someone into the wrong study
A campaign's tracking code is the short code a participant texts to join a study. Three live client campaigns turned out to be sharing a code with an old Yazi campaign that had been deleted, and nothing in the lookup was excluding deleted campaigns, so which study a participant landed in was decided by whatever order the database happened to return rows in. Nobody was misrouted, but only by luck: that ordering changes on its own during ordinary database maintenance, and had it flipped, someone texting a client's code would have been dropped into a deleted campaign belonging to a different organisation. Deleted campaigns are now excluded everywhere a campaign is looked up, and the result is deterministic rather than incidental.
Fix
A photo sent as an answer is no longer lost between two machines
When a participant sends photos we hold them briefly so several arriving together are treated as one answer. The machine that receives a photo is not the one that processes it, and the message waking the second machine only carried a pointer to where the photo was held rather than the photo's own details. So if the processing machine could not reach that holding area, it found nothing and moved on, and the photo was gone silently even though it had been saved correctly. The message now carries the details itself, so a worker that finds nothing waiting rebuilds the answer from the message instead of giving up. Roughly 5,954 media batches went through this path in the last week.
Fix
A WhatsApp Flow can no longer be published with a question it cannot render
Some surveys run as WhatsApp Flows, which are form-style screens inside the app rather than a back-and-forth chat. The survey builder let researchers pick two question types for those screens, Document and Location, that the Flow builder had no way to actually build. What a participant got was a screen with the question written on it, a Next button, and nothing to answer with. Nothing errored and nothing was logged, so nobody found out unless a participant said something. That can no longer be published: picking a type we cannot build now fails at build time with a message naming the question, in front of the researcher rather than in front of the participant. Nothing currently live is affected.
Fix
Ending a moderator takeover now ends the chat you are looking at
When a moderator takes over a WhatsApp conversation they hold that chat until they end it, and the participant cannot receive their next survey activity while it is held. If you were holding one chat and clicked on a different one, the red "this conversation has been idle" banner stayed on screen over the new chat. Reading it, you would think it was about the chat in front of you. It was not: pressing "End session now" ended the chat you had left behind, released that participant, and left the one on screen untouched, with nothing telling you it had happened. So a moderator could end a live conversation they were still working on without knowing, and the participant on the other side got handed back mid-conversation. The button now only appears when the idle chat is the one you are looking at, and ending a chat always targets the chat you meant. The same fault was found and fixed in four other places on that screen, including one where a reply typed into one chat was saved as a draft on another.
Fix
Ask Yazi finishes the whole list of changes you asked for
Ask Yazi would apply the first of several requested changes and then hang for about twelve minutes before failing. It was not a timeout and not a length limit: the assistant had produced all the requested changes intact, but one of them needed your approval on a live campaign, and it stopped for that mid-way through carrying out the others. The rest were left unanswered, which put the conversation in a state it could never recover from, so the run burned through its retries and died. 39 runs had failed this way since the end of June. All the changes in a round are now proposed, approved and carried out as one group, one card and one click, so this cannot happen rather than merely being less likely. Verified live: a run that previously died at 1 of 9 now applies 9 of 9.
Fix
Filters show what they are filtering by again
Across the platform, filters with an "All" or "None" option were displaying a blank box instead of the selected option: the project filter on Plan and Usage, the type and status filters on the Dashboard, Templates, Scheduled Messages, and several results screens, 12 filters in total. Opening a filter showed the correct option ticked and the filtering itself worked correctly the whole time, so nothing was ever filtered or counted wrongly. But with the box appearing empty there was no way to tell at a glance what a screen was filtered by, which made it easy to misread a screen as showing everything when it was not. A side effect of the recent dropdown redesign, which treated "All" as though nothing had been chosen yet.
Fix
A demo campaign now shows the people in it
The onboarding seed created a new organisation's demo participants, their answers and their AI transcripts, but never added them to the campaign's participant list. So a new organisation opened their demo campaign, saw "10 completed" on the dashboard, and found an empty Participants tab. 105 demo campaigns across about 53 organisations were in that state and a new one appeared with every signup. The seeded participants are now on the roster, so opening a demo campaign shows all ten people with their progress, their answers, and a full transcript on the interview one. 1,046 participants restored. Nothing was fabricated, the data already existed and simply had nowhere to appear. If anyone reported their demo data as missing or broken after signing up, it should look right now.
Fix
The Portuguese console is Portuguese in three more places
Three surfaces on a Portuguese white-label account were still hardcoded English. The Progression menu on a study's participants screen, where you push, pause, resume or reset a participant, along with its activity picker, its reset confirmation and the message you get after each action, and a failure message that was printing our internal action code so a failed push read "set_activity falhou". The modal that lists problems when you publish a campaign, which is the worst possible moment to hand someone a language they may not read, along with all 13 of its validation messages. And the login, sign-up, password-reset and verification screens, where a wrong password or a bad verification code came back in English, so the people most likely to be stuck got the least helpful message. Two related login problems went with that last one: users whose account was not verified yet were told exactly that, but the button to resend their code silently did not appear, leaving no way forward, and a failed Google sign-in sometimes showed a raw code like `access_denied` instead of a sentence. One gap stated plainly: if a publish failure comes from deep inside WhatsApp's own Flow service, that text still arrives in English.
Fix
Publishing a study no longer fails with an unexplained error
Every study gets a unique WhatsApp starter phrase, the short code a participant sends to join. The database requires those to be unique, but the code that saved one had no handling for the case where the generated phrase was already taken, so if two ever landed the same, publishing failed with a generic error and nothing to act on. The equivalent code for campaigns already retried with a fresh phrase, so the two halves of the platform disagreed about a rule they both had to follow. It now retries with a fresh phrase and the study publishes normally. The odds were low, roughly half a percent even at a hundred studies in one organisation on one day, but the failure mode was bad out of proportion to its likelihood.
Fix
The Past Usage chart no longer freezes the tab
Opening Settings, Plan and Usage, History rebuilt the usage chart continuously instead of leaving it alone. On some machines that made the page unresponsive and you had to close the tab. It also meant that moving across the chart's monthly bars with a keyboard lost your place after every step, so the chart was effectively unusable without a mouse. It looks and behaves exactly as before, it just stays put.
Fix
A bundle message no longer says money is gone when it is not
Organisations that had used up a bundle were told on Plan and Usage that their bundle value was "spent permanently" and that finishing a project would not give any of it back. That stopped being true when admins gained the ability to correct a project's rate, which returns the value it used to the bundle. The message now says only the part that is still accurate. Left alone it would have told a customer their money was lost when it was not, which is the kind of thing that turns into a billing dispute. Wording only, nothing about how anyone is charged has changed.
44 changes
New feature
Put a participant on hold, then put them back
Hold used to be one-way. Once you held someone on a multi-activity study there was no way to return them to their original schedule: your only exits were Push, which sends immediately, or Reset, which wipes their progress. Held participants were also invisible, with no pill, no filter and no count, so you could hold someone, forget, and strand them with nothing on screen explaining why. And Hold reported success even when it had held nothing at all. There is now a Resume action that restores the original schedule without sending, a "Held" pill on the row with a filter and a count, and an honest message when there was nothing to hold. The "next activity" date also stopped counting held, failed and skipped jobs that will never fire.
New feature
One media viewer, used everywhere, and it works on a phone
Opening a photo or a voice note used to depend on which screen you found it on, because each screen had built its own version. A voice note opened a big empty box with a plain browser player, a photo sat in a fixed window that did not fit it, nothing told you which question the answer belonged to or who sent it, and on a phone you could not open media at all. There is now one viewer everywhere. The photo or video fills the screen with the question and the respondent above it and the transcription or image analysis below, multiple photos in one answer page through with arrows or your keyboard, voice notes get a proper player with a waveform, and a genuinely missing file says so instead of spinning forever. Clients opening a share link get the same experience rather than a stripped-back one.
New feature
Copy a join link in each of your study's languages
When a campaign supports several languages the Share tab is supposed to let you pick a language and copy the matching join link, each with a country flag. That was built a while back and it never actually appeared. It was only offered to campaigns using the newest join-code format, and the large majority of real campaigns still use the older one, 1,756 of 1,988, with 1,412 of those live right now. One campaign we checked ran in French, German, Portuguese and Spanish with no English at all and still showed a single English option. There was a second problem underneath it: even once the languages were offered, a participant sending the translated phrase would have been met with silence. Both are fixed, so you can now copy the right link per audience and trust it works.
New feature
Ask Yazi gets out of the way
The Ask Yazi button used to sit in the bottom-right corner of every screen as a full-size pill that never moved, so whatever the page put in that corner it covered. That produced seven separate bug tickets over time, including one on mobile where it sat on top of the only link to respondents' photos and made them unreachable. It now introduces itself for three seconds when you land on a screen, then tucks away as a small tab on the right edge. Hover and it slides back out, click and the chat opens, and there is a labelled Minimise button inside to send it back. Pagination, footer buttons and page controls are usable everywhere again, and the next new screen does not have to be taught to dodge it.
New feature
Reminder schedules get the controls broadcasts already had
Picking Reminder under Add New Schedule used to give you a much thinner form than a CSV broadcast: a frequency dropdown, a fixed list of hours, and a campaign picker. There was no start date, no sending window, and no way to choose which days it could go out on. Those controls existed on the CSV broadcast side and the reminder side was never brought along. You can now say "start this on the 1st", "only Monday, Wednesday and Friday", or "only between 9am and 5pm so nobody gets pinged at 11pm". Everything is optional and reminders that already exist keep sending exactly as they do today.
New feature
Choose which columns show on the People list
The People table now has a Columns show/hide control next to Add filter, and any custom metadata fields on your organisation appear there. They are hidden by default and you switch on the ones you want. A search now shows skeleton rows while it runs, with the input still usable, the dead band under the pagination is gone, and the "25/25" label that could only ever say 25/25 has been removed. Sorting and filtering on custom fields are not built yet, they are the next piece.
New feature
The completion message is now visible in the builder
Every study sends a closing message when someone finishes, and there is a sensible default if nobody writes one, but that message only ever lived in the settings panel under "After completion". It now appears as a locked row pinned to the bottom of the question list, styled to read like one of the questions above it, and you can edit it there without leaving the builder. It cannot be dragged, reordered or deleted, because it always has to come last, and a study with the completion message switched off simply does not show the row. A follow-up the same week made the row honest about the other endings: a study can instead finish with a closing broadcast, a redirect to another survey, or a reward, and the row was showing the default completion text in those cases, quietly telling the researcher the wrong thing. It now shows whichever ending is actually configured, read-only where that ending is set elsewhere, with a line underneath saying what kind of ending it is and how it reaches the participant.
New feature
Clearing results now asks what you actually want
Clearing old results is routine and it is meant to just delete answers. It was also quietly wiping participants' study progress on a multi-day study, cancelling their queued next-activity message and sending them back to day one. On one study in July that cost two real testers their Day 4 message, and the client noticed before we did. The delete now gives you a choice. "Clear results only" is already selected, so clicking straight through keeps everyone's progress. A full reset is still there when that is genuinely what you mean, and it tells you how many people it affects. There is also a "remove simulated respondents only" option for safe cleanup before go-live, which cannot touch a real participant even if one is selected by mistake.
New feature
Price a once-off project at a negotiated amount
Until now the only pricing options were the four rate-card tiers at their set prices. If a deal had been agreed at any other number there was no way to record it, so the project either got priced at the wrong amount or was left unpriced, which also meant no usage caps and no billing at all. You can now enter a custom amount when setting a rate. The tier is still chosen and still decides the project's usage limits, only the price changes, and the project card shows the negotiated figure so a custom-priced project is never mistaken for a standard one. Once-off projects only, bundle and pilot projects are unchanged.
New feature
Plan & Usage explains what its labels mean
The billing summary at the top of Settings, Plan & Usage showed labels like "Billing mode", "Your tier" and "Projects" with nothing to say what any of them meant. Each now has a short plain-English line underneath, and a "What do these mean?" link opens full definitions, including the rule people get wrong most often: a project collects one kind of response, so a survey and AI interviews need to be run as two projects. The wording works for once-off, bundle and monthly customers alike.
New feature
See when a broadcast was created
The Broadcast Messages list showed name, category, type, language and status but never when a broadcast was made. In an account with over a hundred of them there was no way to tell this morning's from last year's, and no way to sort by age. There is now a Created column you can sort on, newest or oldest first, and it shows on phones too where the list turns into cards.
New feature
Ask Yazi can apply a translation brief you paste in
You can now paste a translation brief into Ask Yazi in chat and have it write those question translations directly, with the organisation, language and question all validated before anything is written. Useful when a client sends corrections back as a document rather than editing them in the platform themselves.
Improvement
Moderator takeover is finally live rather than nearly live
Taking over a live WhatsApp conversation had a websocket built specifically so messages arrive the instant they land, and it turned out that fast path had never worked in production. Every message any moderator saw during a takeover arrived on a slow background refresh instead, up to 60 seconds later. Measured on production before and after: 20.4 seconds down to 0.22 seconds. Four more things in the same area were fixed with it. The "Active Chats" badge kept saying you were holding a conversation for hours after it ended and its arrow opened onto nothing, so it now counts correctly and lists the chats you are holding, one line each, clicking through to the conversation. A participant's message could draw itself on screen six times when only one had been sent. And the box you type into was three boxes stacked inside each other, using WhatsApp's colours rather than ours with hardcoded English placeholder text, throwing away your line breaks and never shrinking back after a long message. It is now one clean control that resets itself after every send.
Improvement
Study tabs load ahead of you and remember what they loaded
Opening a study lands you on Build and nothing else used to start loading until you clicked it, so every tab paid its own cold start even though the study had been on screen for a minute. The participant list, the chart and the media library now warm themselves quietly in the background while you are still on Build, gently, one request at a time. Switching between tabs also used to throw everything away and re-fetch it from scratch, so flicking between Share and Results meant waiting for the same data two or three times. Those tabs now hold what they already loaded. The careful part was making sure it never shows you something stale: approve a reward, add or remove people, change trust, delete test data or republish a study and the affected screens drop what they were holding and fetch again.
Improvement
Form fields, dropdowns, toggles and tooltips now come from one shared set
A large sweep this week moved the app's inputs, textareas, dropdowns, multi-selects, toggles and tooltips onto one shared component library, replacing dozens of hand-rolled and one-off versions across roughly a hundred files. Mostly this is invisible, and that is the point: a field now looks and behaves the same wherever you meet it, and a fix applies everywhere at once instead of in one screen at a time. Two visible changes came with it. Input fields now show a neutral grey focus outline rather than a blue one, following a team vote, and multi-select values show as comma-separated text in the control rather than overflowing pill chips. Being straight about the cost: the sweep introduced a run of its own faults over the week, including number fields submitting text and breaking the Request Incentive Credits form, auto-growing textareas clipping their own content, several double borders, and one bug that removed the visible border from every default input in the app. All of those were found and fixed within the week.
Improvement
Response Trust is on by default for new campaigns
Creating a campaign now switches Response Trust on, with all five signals up and sensitivity set to Balanced, so you turn it off if you want it off rather than having to remember to turn it on. New campaigns and duplicates only. Existing campaigns are untouched, anything that was off stays off, and you can still switch it per campaign under Study configuration, Response quality.
Improvement
The People list is faster, and the Started column is now right
The People list worked out Started, Completed and last activity by reading every message row for every participant, so the default sort had to chew through all of them before it could pick 25. It now reads a table that holds one row per person per campaign. Measured on 13,204 participants: 386 to 722ms down to 243 to 254ms, and far steadier. Worth knowing: the Started column will read higher than it used to. We diffed it against real data before shipping, 1,373 participants gain a higher count, nobody's number goes down, and 1,052 people who had begun a survey were showing "Started 0".
Improvement
Removing someone from a study now actually removes them
Removal used to leave a participant's completed activities behind, so the study carried on reporting them as having completed things, and their enrolment record was never deleted at all. Adding them back could drop them straight into an "already completed" state. Removal now clears their responses, completed activities, any scheduled messages they have not received yet, and their enrolment, across the whole study. They stay in your People pool and can be added again, starting fresh, and the confirmation dialog says plainly what will be deleted. This matters because a study's participant count and completion numbers are what researchers report to clients.
Improvement
The Share tab and the guided tour now speak Portuguese
On a Portuguese white-label account most of the Share tab was still coming out in English: table headings, status labels, filters, the export menu, every tooltip, the participant panel and all the confirmation messages. An earlier ticket had translated the top of that page and left the rest. The guided onboarding tour had the same gap, with Skip, Next, Back, Done and the "Step 2 of 5" counter written into the code in English. Both are now translated, and nothing changed for English users. The CSV and Excel exports are deliberately left in English, because those files get opened in analysis software and people have scripts reading the column names.
Improvement
Once-off billing means one active project at a time
515 organisations moved from monthly billing to once-off project billing. In practice that means each of them can have one active project at a time, where previously there was no limit. If a customer says they cannot create a new project, this is almost certainly why, and they need to complete or archive the current one first. Nothing existing was broken: only one organisation had an active project at the time and it was within the new limit, so nobody lost access to work in progress.
Improvement
A bundle now reserves a project's value when you assign it
Buying a bundle buys a pot of money that projects draw from as they go live. Assigning a project to a bundle only ever checked whether the pot could afford it, it never set the money aside, so several projects could each be approved against the same money and the extra ones went live unbilled. Assigning a project now reserves its value immediately, and anything that would take a customer past what they have paid for is refused at that point rather than quietly going through later. Plan & Usage changes to match: it used to show the full pot, which could read "R39,000 remaining" while most of it was already promised, and now leads with what is actually still available and shows how much is allocated. No customer had been under-billed by this, so there is nothing to correct retroactively.
Improvement
Small things in the question builder
Pressing Enter on a Single or Multi Select option now moves you into the option it just created, rather than leaving your cursor behind. The question-type dropdown has thirteen or more options and gave no sign there was more below the fold, so it now has a real scrollbar that appears when the list overflows. A first attempt at that used chevron arrows, which was replaced the same week after feedback that it was not the right answer.
Fix
Scheduled study activities now send their invite
On a multi-activity study each activity is meant to arrive with an invite message, the one you pick and get approved in the builder. The job that opens the next activity was never sending it. It opened the session and stopped. Forty study activities in production had an invite configured and none had ever been used, so a participant who agreed to a multi-day study simply got nothing when the next day opened. No prompt, no explanation, nothing to tap. Measured over 30 days: of 460 scheduled hops with an invite configured, 35 produced no message to the participant at all. Worth correcting a common assumption while we are here. The ticket, and most of our own thinking, blamed WhatsApp's 24-hour messaging window closing before the job ran. Of those 35 silent cases, 32 still had the window wide open. The window is a real edge case but it was never the main problem.
Fix
Coming back to a survey picks up where you left off
Three related problems, all fixed. If someone left a survey partway and came back, we sometimes lost our bookmark of where they were and started them at question one, even though every answer they had already given was safely stored. Someone seven questions in had to answer all seven again. We now work that out from the answers they already gave and carry on from the next unanswered question. Separately, whether they could carry on at all depended on the kind of question they happened to be sitting on: plain text worked, but on a rating grid or a multi-select their tap was silently thrown away and they stayed stuck, with no way out except a plain text message that nothing invited them to send. On production 9,322 paused participants were sitting on exactly those question types. Being straight about the first one: it was announced as done last Thursday and it was not. Testing on a real phone showed it only worked on one of the two ways a participant returns, and the way people actually use, tapping Continue on the Welcome back message, still sent them to question one. It is now fixed on both paths and confirmed on live traffic, with a real client survey resuming a participant at question 8 this week instead of restarting them. A looping question, one that repeats per item, now restarts rather than guessing, because guessing could skip the rest of the loop silently.
Fix
A participant stranded mid-interview gets put back into it
When someone is partway through an AI interview and their conversation loses its internal routing, there is a safety net meant to find their live interview and put them back. It was looking up the wrong thing and could only ever rescue about 2 in every 100 people it was built for. Everyone else fell through to the generic "welcome, pick an option" menu, mid-interview, as though we had never met them. It now finds 99.9% of them. One thing worth saying plainly: the first version of this fix, which we did not ship, would have been worse than the bug. It looked up the participant's organisation, a value that quietly changes to whichever organisation last messaged them, which meant one participant's message could have been routed into a different client's interview. Review caught it and reproduced it against production data before it went anywhere. The version that shipped uses the study's organisation instead, which cannot drift.
Fix
A participant's message between activities is no longer thrown away
On a multi-day study there is a gap between one activity finishing and the next opening. If a participant sent something in that gap, often a real answer, a photo or a location, we replied to them and then discarded it. It was never stored anywhere. Measured on production: 172 participants are mid-study right now and roughly 119 messages a week were being dropped this way. That is research data quietly disappearing from someone who took the time to tell us something and got answered as though we had heard it. A related fix came with it: location messages were being reduced to the word "[location]" instead of the actual coordinates, which were already parsed a few lines away in the code.
Fix
Photos sent as an answer are no longer silently dropped
When someone sent photos as a survey answer we queued them and handed the job to a second process. If that queue write failed we carried on as if it had worked, the second process found nothing and gave up, and the photo was gone. No error was raised and the participant was still thanked for sending it. This is the fourth time this class of bug has been fixed: once before, a participant sent six photos and only two were saved. We now check the queue write actually succeeded, process the photo immediately if it did not, and tell the participant if we genuinely cannot recover it.
Fix
WhatsApp messages that failed once now get retried
When a WhatsApp send fails we park it in a queue and a background job retries it a minute later. Before running, that job checked the queue was reachable, and it remembered a negative answer forever. So if that single check landed at a bad moment, a brief database hiccup or a deploy arriving just ahead of its migration, that server stopped retrying messages for the rest of its life. Silently, with nothing in the logs after the first line, until it happened to be replaced. Undelivered WhatsApp messages are invisible from our side: nobody gets an error, the dashboard looks fine, and the participant simply stops hearing from us. The check now only remembers a yes and re-checks after a no, so recovery takes seconds. The same flaw sat on the table that records why an answer was rejected, which is what feeds "11 people got stuck on Q4", and that is fixed too. Both copies of the check have been folded into one shared piece of code so this cannot be fixed twice again.
Fix
A grid answer given in Portuguese is stored in Portuguese
On a grid question we show the answer scale in the participant's own language. Someone taking a Portuguese survey sees, and taps, "Concordo". We were saving their answer as "Agree". What they read and what we stored disagreed, so a researcher exporting a survey that ran entirely in Portuguese got English values back. Reports bucket grid answers by matching stored text against a list of English labels, so fixing the storage alone would have broken every report for non-English surveys. The companion fix was built, shipped and confirmed live first, and only then was this one merged, so there was no window where reports were wrong. This is a forward fix, not a backfill: exactly one historical answer in production carries the old behaviour, and rewriting stored answers would change the meaning of reports already sent to clients.
Fix
Text is no longer cut in the middle of an emoji
WhatsApp limits how long an option or button label can be, so we shorten anything that runs over. The way we were doing that could slice an emoji in half, and what is left is not a character at all, so WhatsApp either rejects the message outright or the participant sees a black diamond where the emoji should be. Emoji are everywhere in survey options. The ticket named four places doing this by hand and there turned out to be nine, each written out separately with the length limits repeated about a dozen times. All nine now go through one shared helper.
Fix
An oversized logo is refused when you upload it
WhatsApp will not accept an image over 5MB, and our logo upload accepted anything. A too-large logo saved happily and then failed weeks later when a template tried to send it, surfacing as a "template format" error that sends whoever is debugging it looking in the wrong place. That is exactly what happened on one production organisation with a 12.5MB logo. The ticket named one place and there were six: four upload paths had no size check at all, and two had written the 5MB limit out separately. All six now share one check.
Fix
Transcripts no longer show raw formatting marks
Our transcript and reporting screens were showing raw WhatsApp formatting, so a message meant to read as a bold "Q5 of 12" appeared literally with asterisks around it. The obvious worry was that participants had been receiving those stray asterisks too. They had not, and we verified that properly before changing anything. Researchers reading transcripts now see messages exactly as the participant saw them, consistently across all 13 screens that display participant messages. The verification did find a separate and genuine issue: on 4 live campaigns belonging to one account the question counters were typed into the question text by hand and 8 of 10 now state the wrong total, telling people "Q5 of 12" on a 13-question survey. That affected 3,059 real participants and is tracked separately as a content problem, not a formatting one.
Fix
Opening a participant's details on one activity no longer freezes the tab
On a study with several activities, narrowing the Participants list to one activity and then clicking into a person locked the browser tab up entirely. You got "Page Unresponsive" and had to close the tab and start over, with no error message to explain it. It hit at least two client workspaces. Checking one person's progress on one activity is the everyday reason to open that screen, and it was the exact thing that broke. That screen now opens instantly, and the more activities a study has the bigger the difference.
Fix
Join links follow an organisation onto its own WhatsApp number
Every new organisation starts out sharing Yazi's WhatsApp number and moves onto their own WhatsApp Business number once they are set up. When that happened, campaigns and studies they had already created carried on pointing at the shared number, so their respondents were messaging a different company's WhatsApp business, seeing that company's name at the top of the chat, and never reaching the organisation that invited them. Links now move across automatically on upgrade, and the organisations already affected have been corrected, so nothing is left on the wrong number today. This came from a customer asking how to change the name shown at the top of their WhatsApp chat. That name is not something they can change, it belongs to whichever business is being messaged, and they were simply being sent to the wrong one.
Fix
A manual translation correction is no longer overwritten
Two related problems on a multi-language study, both reported by a client. Publishing could capture a half-written translations snapshot while a background auto-translate job was still mid-write, leaving a question's translation blank on the live version. And auto-translate overwrote every translation on every run, including ones somebody had corrected by hand. The same gap sat on the discard and restore-from-published path and was closed with it.
Fix
The dashboard shows your studies straight after you log in
Logging in took you to the dashboard and it looked empty. No studies, no campaigns, just the "Get started with your first campaign" screen, as though the account had nothing in it. Refreshing brought it all back. On an account with hundreds of campaigns that is alarming, and the only way to find out it was fine was to know to hit refresh. The dashboard was starting to load your data the moment the page opened and something else running at the same time was cancelling those requests before they finished. The data was never missing, it just never arrived.
Fix
Creating a broadcast no longer hangs on "Sending to Meta"
The screen sat on "Sending your broadcast message to Meta..." with a greyed-out button and never moved on, even though Meta had accepted the request within a few seconds. People assumed it had frozen, closed the window, and in some cases created the same broadcast twice. You now get a green tick, "Sent to Meta for approval", the broadcast name so you can find it again, and a working Close button.
Fix
A reminder schedule that cannot work is now refused when you save it
One client had a nightly reminder schedule where the message mapping did not match the template it was sending. It could never have worked. Every night it tried, every night it failed, nothing told anyone, and 25 people were queued who never received a message. It only came to light because a monitoring bot spotted it in the logs two days later. Two things are different now. A schedule that cannot work is refused the moment you save it, with a message explaining exactly what is wrong. And a schedule that starts failing later switches itself off after three consecutive nights of getting nowhere and raises an alert, resetting the moment a send succeeds.
Fix
Exports and downloads were briefly broken and are working again
For a few hours on 26 August, downloading a dataset gave an error page instead of a file. It was not only the CSV and Excel buttons on Table Data: every export download was affected, including reports and PowerPoint, scheduled broadcast CSVs, media archive ZIPs, and the media links embedded inside spreadsheets that had already been exported. It is fixed at the source rather than patched over, so links that were already generated and had gone dead work again on their own. Nobody needs to re-export anything.
Fix
An active team member no longer shows as "invited"
In Settings, Members, someone who had joined the organisation through an access code rather than an invite link stayed under "Pending invites" forever, because the access-code route never marked their invite accepted. Accepted invites are also now excluded from the pending list. This was the display half of the ticket only. Being able to remove a member's access is a separate piece of work and is not built.
Fix
Opening a participant's WhatsApp history no longer overloads the platform
On 26 August, opening WhatsApp history on a participant in the People drawer took the production database read replica from 8% CPU to 99.99% and nearly exhausted its connections. The drawer was calling the transcript endpoint once per campaign, in parallel. The participant had 118 campaigns, another in the same organisation has 152, so one click fired 118 requests. It now makes one request instead. The route to do that already existed and had been deployed for some time, it had simply never been called. Where a participant exceeds a 200-campaign ceiling the screen says "Showing the N most recent campaigns of M" rather than quietly giving you a partial history.
Fix
A removed participant's interview transcript is now deleted too
Removing a participant was only soft-deleting their structured survey answers. Their AI interview messages are keyed differently and were being skipped, so a removed participant's interview transcript stayed live and readable. It is now cleared with the rest.
Fix
An interview is no longer marked finished just because someone went quiet
The interview engine ran a background job on every restart that looked for interviews quiet for an hour and marked them finished. People go quiet and come back, so that assumption was wrong, and marking someone finished is not a harmless status change: it also delivers their next activity and can approve their panel payment, so on a paid study it could pay someone who answered one question. It caused real problems three separate times, most recently cutting off three live participants mid-survey, and each previous fix narrowed which interviews it touched while leaving the wrong assumption in place. The whole job is now gone. Interviews finish when the conversation actually ends, which is already how 96% of them behaved.
Fix
Audit records that were being thrown away are now saved
Three pieces of the audit trail were quietly failing. Anything done with an API key rather than by a logged-in person was discarded before it was saved, because "API key" was missing from the list of who is allowed to be recorded as an actor, and the events being lost were the security-relevant ones: an invalid key presented, a valid key reaching an endpoint it should not, and successful API requests. Two services, incentive and reporting, did not have permission to write to the audit trail at all, and the refusal was caught and discarded so nothing ever showed as an error. For incentives that meant approvals and declines of payments to participants, which are financial decisions, had no record from that service. Separately, production media was being served through the staging content delivery network and signed with staging keys, so production was quietly depending on staging infrastructure. All three are fixed and confirmed on production.
24 changes
New feature
Decide how many interview questions go to each topic
AI interviews used to split questions evenly across your key topic areas, so three topics always got roughly a third each whether or not that matched what you cared about. There is now a Topic weighting row in the Study configuration panel where you set the split yourself, for example 6/2/2 instead of 4/4/4, and the interview follows it proportionally. Change the interview length or the required questions afterwards and the counts rescale on their own, so the split you asked for stays intact without you redoing the maths. Even split stays the default, so a study that never touches this setting behaves exactly as before.
New feature
Only show a question if a condition is true
You can now gate a question on entry rather than routing around it. Set an "Only show if" condition and the question is skipped for anyone who does not meet it, without you having to build a chain of skip rules from every question that could reach it. The Logic Map shows the gated question with its own badge and entry edge so you can see at a glance which questions are conditional. Verified on a real WhatsApp send, not just in the builder.
Improvement
One send flow for broadcasts, wherever you start from
Sending a WhatsApp broadcast from the Templates page and sending one from a study's Share tab used to open two different screens that had been built separately. They are now the same four-step flow, so it looks and works the same either way and anything we improve in it improves in both places. The screens after you hit send, the job progress and the results, also got a cleaner receipt-style layout. The duplication was the cause of a recurring class of bug that had already been hand-fixed twice in two places, so this stops that coming back as much as it tidies things up.
The unified four-step Send broadcast flow, reached from either the Templates page or a study's Share tabImprovement
WhatsApp replies come back faster
Two spots on the messaging path were doing far more database work than they needed to. Every WhatsApp Flow screen a participant submitted re-ran a full study-and-questions lookup from scratch, and every single message re-fetched a study's settings a second time just to read its translation flags off a row it had already loaded. Both are now served from cache. Nothing changes in how a study behaves, participants just wait less between questions. Found by us watching the numbers, not reported by anyone.
Improvement
Study Configuration opens closed
The Study Configuration panel now opens with every section collapsed instead of everything expanded at once, and opening one section no longer closes another or scrolls the panel around underneath you. Landing on a wall of expanded settings made it hard to see what was even available. This is one of four things Tim raised about that panel on 28 July. The other three, nesting Screen-Out Message inside Completion and Follow-up, and defaulting the drawer to Settings rather than Blocks, are still open.
Improvement
Media Library filters now cover every activity
On a multi-activity study, the Media Library's "+ Add filter" question filter only ever offered Activity 1's questions, so you could not filter media down to an answer given on any later day. Every activity's questions now appear, each labelled with its own activity name, and filtering on a specific single or multi-select option works on all of them. The "Question" media-group dimension had the same gap and is fixed too, and the redundant "Which question" label is now just "Question".
Improvement
Multi-select questions on WhatsApp show your real option text
Multi-select questions delivered as a WhatsApp Flow were showing "Option 1", "Option 2" as the heading of each row with your actual wording pushed into the grey line underneath. That was a deliberate fix for long options being cut off, but it made short, readable options worse. Now the real option text is used as the heading whenever it fits, and the numbered fallback only kicks in on a question where at least one option is too long, applied to every option on that question so the list stays consistent rather than half one style and half the other.
Improvement
A heads-up when a question has more than 10 options
Option-based questions now warn you in the builder once you go past 10 options, so you find out while you are writing the question rather than from the way it lands on a participant's phone.
Improvement
The recipient list on a sent broadcast opens straight away
Opening the recipient list for a broadcast with a lot of people used to take a very long time and could feel like it had hung, because it fetched every single recipient in one go with no index to help and then ran two more lookups per person on top. For a broadcast with thousands of recipients that is thousands of extra lookups every time anyone opened the panel. It now shows the first ten almost immediately and fetches the rest quietly in the background.
Improvement
"Update Study" greys out when there is nothing to publish
On a multi-activity study the Update Study button stayed dark and clickable even when every activity was already published with no pending changes, so there was no way to tell whether you still owed the study a publish. It now shows "Published" with a checkmark and is unclickable once everything is live, matching what ordinary survey and interview studies already did.
Improvement
Participants hear back even when the vouchers run out
On an incentivised study where vouchers are capped, a participant who finished the interview after the cap was reached got nothing at all: no voucher and no message. They now get a thank-you either way, whether the vouchers are exhausted or the delivery itself failed, so nobody is left wondering if their answers went through. The wording is configurable without a deploy.
Fix
NPS and rating scale questions were recording the wrong answers
A run of separate problems on 0 to 10 scale questions, all fixed this week. Answers were being shifted down by one, so somebody tapping 2 was recorded as 1, and the top of the scale, 10, was dropped from the list entirely. An 11-point scale was too long for WhatsApp's tappable list, so it fell back to asking people to "reply with the letter", and then rejected both the letter and the number they sent. A bare digit could be scored against a question that had only ever shown letters, and out-of-range replies like "11" were being stored as raw text instead of being rejected. And when a number was genuinely invalid, the reprompt was a generic "that is not a number" rather than telling the person the actual range. All of that is now correct: the scale sends as a plain number prompt, only the identifier the participant was actually shown is accepted, anything else is rejected and re-asked, and the reprompt names the range in the participant's own language. If you have run an NPS question on WhatsApp before this week, the recorded scores are worth re-checking.
Fix
Choosing a language on a non-English study now changes the language
On a study authored in a language other than English, a participant picking a different language got the campaign's original language anyway. Several translation checks in the system assumed that a study's base text is always English, which is fine until somebody writes their study in Spanish. Those now check the study's actual default language instead. A related problem is fixed with it: in a multi-activity study, a returning participant's explicit language choice was being overwritten by the study default on their next activity.
Fix
AI interviews no longer drift into the study's authored language
Two ways an AI interview could answer an English-speaking participant in the language the study was written in. The interviewer was copying example phrases embedded in the study's objective text word for word into its questions, so a Spanish example produced Spanish questions in an English session until enough English conversation built up for it to correct itself. And the participant's completed survey answers, which get handed to the interviewer as context, always carried the question text in the study's authored language even where a translation already existed. Both are fixed, and the fix is general rather than specific to any one study or language pair.
Fix
"Other, please specify" behaves properly
Two problems with the "Other, please specify" option on single-select questions. On WhatsApp it let a participant move on without typing anything in the box, so you got an "Other" with nothing attached. And in the Build tab's Test Simulator the option did not appear at all, so you could not check the question the way a participant would see it. Both fixed.
Fix
Statement questions wait for the participant on every study type
A Statement is meant to send, then wait for the person to tap Continue before the next one goes out. That only ever worked on Interview studies. On Survey, Diary and Recurring Survey studies a run of Statements all fired at once, so a participant got a burst of messages instead of reading them one at a time. Now every study type waits.
Fix
A typed letter no longer counts as an answer to a tappable list
Two related problems where a stray text reply was silently recorded as a real answer. A native WhatsApp list never shows A/B/C or 1/2/3 to the participant, only tappable rows, but a typed "a" or "1" was still being decoded as a deliberate choice and saved as whatever option happened to sit in that position. And a multi-select sent as a Flow accepted a plain text reply instead of requiring the person to actually open and complete the form. Both now require an answer that matches what the participant was really shown, and anything else is rejected and re-asked. The letters fallback, which is a legitimate path when a Flow cannot be built, is unchanged.
Fix
Graph Data was showing everything as "Other" after an edit
On one study a question's chart showed 100% "Other" instead of the real answers. The cause was worse than the symptom: the AI question-editing tool was generating fresh IDs for every answer option any time the options were edited, which cut every already-recorded response loose from the option it belonged to. Both the display and the underlying ID behaviour are fixed. If you have edited answer options through Ask Yazi on a study that was already collecting responses, it is worth a look at that question's chart.
Fix
Highlight reels now pull from every activity
On a multi-activity study the highlight reel generator was only ever looking at Activity 1's voice and video clips, so everything from day two onwards was invisible to it. It now reads every activity. On the study this was reported from, the pool of candidate clips went from 69 to 513 across 11 activities, and the regenerated reel drew from five activities that had never been eligible before. A first attempt at this fix quietly did nothing in production and was hotfixed the same day, so this is the version that actually works.
Fix
Deleted responses stay deleted in the results table
After a study reset or a deletion, soft-deleted messages were still turning up in the Table Data response table. The same class of problem had already been fixed in Graph Data, the Media Library and transcripts, and this one query was missed. Fixed, with a test in place so it cannot quietly come back.
Fix
A "Flagged" badge no longer outlives the transcript it came from
A participant could show as Flagged with reasoning quoting answers from an attempt that had already been deleted. Two paths caused it. Removing a participant never cleared their trust score, so a stale risk rating silently reattached if they re-enrolled or the study was restarted. And the Delete Transcript button in the moderator takeover panel bypassed the removal path entirely, so it never cleared the score at all. Both now go through the same route.
Fix
The last day of a multi-day study sends its completion message
On a multi-day study, the completion message at the end of the final activity was never firing on WhatsApp, so participants finished the whole thing and heard nothing back.
Fix
Broadcast history was showing impossible percentages, and would not page
Two problems on the broadcast history panel, which is where you go to check whether a broadcast actually reached anyone. Read and start rates were being turned into percentages twice by two different bits of code, so a real 25% read rate displayed as "2500% read" and the whole panel read as broken data. And on the Send History table, the floating Ask Yazi button sat exactly on top of the page controls, so clicking "Next Page" did nothing: production has 760 broadcasts across 38 pages and only the first page was ever reachable. Both fixed. Two smaller things in that same panel, batches labelled with internal codes rather than readable names and an unlabelled minus figure next to the counts, are logged separately and are not fixed yet.
Fix
Small things that were quietly wrong
The Insights tab was flashing "No insights yet" on first click before the data had finished loading, so a study with plenty of insights looked empty until you switched tabs and came back. The participant profile side drawer was rendering with no styling at all, the avatar showing as a full-width red bar with no card sections or timeline. And the Rating Scale and NPS question builders were showing a raw internal key as their heading instead of a title, because two pieces of text were never added to the translation files.
41 changes
New feature
Ask Yazi can tell you how a study is going and who is stuck
On a study running over several days you can now ask Ask Yazi "how is my study going" or "is anyone stuck" and get a real answer: where every participant has got to, who has gone quiet, and why. The why is the useful part. Instead of "twelve people are inactive" it says something like "this participant is on question 6, which asks for a video. The last thing they sent was a photo, and they have not moved for five months." Where somebody is genuinely stuck it also drafts a message you could send them. It only ever drafts, and the tool can only read: nothing reaches a participant unless you send it yourself.
New feature
Answer quality checks now work on written answers and voice notes
Question Actions lets you put a quality rule on a question so the platform checks an answer as it arrives and asks the participant to try again if it does not meet what you asked for. Until now that only ever worked on photos. Rules on text questions saved happily and then never ran, so weak answers went straight into your results and you found out at analysis. Voice notes were worse: the audio was being handed to the part of the system that reads pictures, so every voice note was rejected with "please try uploading the image again" and the participant could never get past that question. Both now work. A voice note is transcribed first and judged on what the person actually said, and a rambling or off-topic answer gets a reply naming what was missing. We also fixed three settings in that menu that saved and then quietly did nothing, and a retry limit that had never taken effect, so a participant could in theory be asked forever. Studies that do not use answer checks are unchanged.
New feature
Change a study from one type to another without losing anything
You can now convert an existing campaign from one type to another, from the type picker in the campaign header or by asking Ask Yazi to do it. Until today Ask Yazi told you campaign types could not be changed and offered to build you a fresh copy instead, which would have cost you the campaign's link and every answer already collected. It now makes the change on the campaign itself, keeping the questions and the responses, shows you what it is about to do first, and explains what the change actually means in practice, for example that an AI interview stops asking your written questions one by one. Two deliberate limits: it will not convert a campaign that has already gone out to people, because anyone part way through would be stranded. Converting into a recurring survey also now sets up the repeat schedule, which it never did before, so three live campaigns that had quietly stopped repeating are fixed.
New feature
Complete someone after the survey without pushing them into the AI interview
Question Logic's "Complete" action has been split into two. "Complete" now genuinely finishes a participant at that point and skips the AI interview entirely. "End of survey" is the new name for the old behaviour, which ends the survey section and hands off to the interview. Until now there was no clean way to let somebody finish who only wanted to do the scripted part: they were routed onward and stalled, and they never counted as complete. You can now build a study where a "no" on an opt-in question closes the person out properly, and where survey-only and survey-plus-interview participants both land in your results as completes.
New feature
The participant progress indicator is now a percentage
The WhatsApp progress indicator shows a combined survey-plus-interview percentage that does not reset when a study hands off from the scripted survey into the AI interview. The old counter jumped from "10 of 10" straight to "1 of 3", or showed no denominator at all once the interview started, and a study that advertised ten questions and then asked thirteen read as a bait and switch. A percentage also handles question logic properly: somebody routed past a section simply moves further along the bar instead of watching the numbers skip.
New feature
Matrix results now chart in Graph Data
Matrix questions used to show "No visualization available for this question type" on the Graph Data tab, so the one question type designed to compare several items on one scale was the one you could not see a chart of. It now renders with per-row and per-column counts, plus a "View as table" toggle if you would rather read the grid than look at it.
New feature
Media questions now tell participants how to answer
When you set a question to a media or special-input type, the platform now automatically adds a default instruction line telling the participant exactly how to reply, for example "Please reply with a video." Before this, unless you remembered to write that yourself, people answered with plain text and you spent the study chasing them for the thing you actually asked for.
New feature
Survey conversations now show when an answer was not accepted
If somebody answers with the wrong kind of thing, say a photo when you asked for a video, we tell them it was not accepted and ask again. None of that used to appear in the conversation history, so the transcript on file did not match what the person saw on their phone, and answering "why did this participant get stuck" meant an engineer reading system logs. The conversation view now shows both halves of that exchange in the right place. These are deliberately not stored as answers, so results, exports and counts are unchanged. One caveat: this only appears on new conversations, not historic ones, and the recording step itself was broken for its first day live, so 35 rejections on 1 August were never saved and cannot be recovered.
Improvement
Voice notes are now transcribed inside Europe
Participant voice notes used to be sent to a Google service hosted in the United States to be turned into text. That audio is personal data and should not have been leaving the region. It now goes to Amazon Transcribe in Europe, and there is no longer any setting that can route it anywhere else. If a transcription fails, nothing else is tried and the voice note stays untranscribed, which is deliberate: we would rather show you a gap than quietly send someone's recording out of region. Two things not to over-read. This covers audio only, so please do not describe the service as fully EU-resident yet: participant photos still go to a US provider and receipt scanning still uses Google, both tracked. And Amazon Transcribe has no language code at all for Xhosa, Sotho, Tswana, Tsonga, Venda, Swati, Ndebele or Northern Sotho, so studies in those languages cannot be transcribed today.
Improvement
Side panels work the same way everywhere
Every slide-out panel in the platform, participant profiles, broadcast history, message recipients, results filters, is now the same panel. You can drag any of them wider and each one remembers the width you chose, so if you like a lot of room for reading transcripts you set it once. You can close any of them three ways: the close button, clicking the greyed-out area, or pressing Escape, which previously worked on only three of nine. The most practical win is the recipient list inside a sent broadcast, which used to be cut off on the right with the failure-reason column and the page controls out of reach. Screen reader users are now correctly told these are dialogs rather than page sidebars.
Improvement
Less clutter on the reporting and study-settings screens
Three things Tim raised. The AI written summary above the Graph Data charts can now be folded down to a single line, and the app remembers how you left it, so on a phone you are not scrolling past 400 pixels of text before you reach any actual results. The "When it unlocks" schedule card on a multi-day study now flips above the row when there is not enough space below it, instead of running off the bottom of the screen where you could not read or click it. And the dividers between sections in a study's settings are now clearly darker than the lines between individual settings, so you can tell where one section ends and the next begins.
Improvement
You can dismiss the "participants are stuck" banner
The red banner at the top of a study ("398 participant(s) are stuck and need attention") had no close button, so it sat there permanently. You can now close it, and it stays closed for you specifically, saved to your account rather than your browser, so it survives a reload and follows you to another device. Your colleagues still see theirs. It comes back only when the number actually grows, and then it tells you what is new rather than the whole total again.
Improvement
You can turn a Statement back into a question
The Build tab could turn a question into a Statement but not the other way round, so if you mis-tagged a question you had to delete it and retype the text. That conversion now works in both directions. While opening it up we found and fixed three things it had been hiding: converting a Statement to a select question left "Continue" sitting there as the only answer participants could pick, and converting to a Scale or a Matrix silently left the card as a Statement. Those two conversions were also broken for ordinary questions, so they are fixed for everyone.
Improvement
A warning before a type change deletes your answer options
Changing a single-select or multi-select question to a text, audio or video type deletes the answer options, because they no longer apply. That used to happen silently, and rebuilding a long option list from scratch is miserable. You now get a confirmation that names the actual stake, computed from the real question: "Changing to Text will delete 5 answer options and 2 branching rules. This can't be undone." It only fires when there is something real to lose. A freshly added question with one blank placeholder changes type silently, and conversions that keep their options, single to multi-select, or multiple choice to Matrix, are never prompted.
Improvement
Matrix questions can have routing logic, and land properly in Table Data
Two Matrix follow-ups. You can now attach routing and skip logic to a Matrix question in the survey builder, which was blocked by a leftover interface guard rather than anything real. And Matrix answers now split into one Table Data column per row, for example Product Texture, Scent and Colour each getting their own column with a plain value, instead of every row bundled into a single unreadable cell.
Improvement
The Test Simulator now shows Matrix and multi-select the way WhatsApp does
The Simulator was falling back to the old lettered "reply with the letter of your choice" rendering for Matrix and Flow-eligible multi-select questions, so what you tested was not what your participants would get. It now renders the real "View question" button and native Flow form, matching what WhatsApp actually sends.
Improvement
Clearer picture of which activity a participant is on
On the study participants grid, the confusing "no longer current" state is gone. A session that is technically still open but is not somebody's most recent one now looks the same as "not yet reached", instead of a third visual state nobody could explain, which was making participants read as active in two or three activities at once. The "Last activity" column is now "Last active" and names the activity it refers to, so you get "Activity 2 · 6d ago" rather than a bare "6d ago".
Improvement
WhatsApp invites with a large picture now send
If a broadcast template had an image at the top and that image was too big for WhatsApp to accept, the message went out without it, WhatsApp then refused the whole message, and the error pointed at the template rather than the picture. The results view just said "request error". Oversized images are now resized automatically so the message goes out with its image, and if one genuinely cannot be sent, only that recipient fails and the reason says so. Worth knowing: a very large image will lose quality when it is shrunk. A warning at upload time is planned separately.
Improvement
Messages WhatsApp rejects now fall back to plain text
When Meta rejects a template send, for example because the template is still pending approval, the participant used to receive nothing at all. We now fall back to a plain text message with a button, so the person still hears from you.
Improvement
Clearer WhatsApp account banners
Two banner fixes. The "account restricted" banner was misreading a Meta business-verification flag as a full messaging block, so accounts that were sending perfectly well were shown as restricted. And when messaging genuinely is limited, by the rolling 24-hour limit or a low quality rating, the banner now says plainly that messaging capability is limited instead of the vague "delivery may be affected".
Improvement
Error messages now say what actually went wrong
When a request failed anywhere in the app you got axios's generic "Request failed with status code 500" instead of the real explanation the server had already sent. The app was reading the error from the wrong place. Every failed request across the whole platform now shows the real message.
Fix
Scheduled study days now actually reach participants
On a multi-day diary study, when the system moved a participant to the next day it sent that day's first question as ordinary WhatsApp text. Because the unlock is a fixed clock time rather than "24 hours after their last reply", that regularly landed outside WhatsApp's 24-hour messaging window, and Meta silently rejected it. The participant received nothing at all: no message, no error, no sign anywhere except an internal log. A scheduled activity now always sends its approved broadcast template first, which respects the window whatever the timing, and free text is only a fallback if no template is configured. Verified end to end on a real study with a real WhatsApp number.
Fix
Coming back to a half-finished survey no longer starts you over
If somebody left a survey part way through and returned later, we put them back on question one and threw away everything they had answered. That is fixed. It turned out to be nine separate problems, not one. The worst: resuming only looked for surveys marked in progress, so a set-aside survey started over; an ordinary answer containing a word like "started" or "fresh" was read as a request to restart and wiped the whole thing; Portuguese speakers could not restart at all because we only recognised the English wording; and if a client had shortened the "start over" button to "No" to fit, then answering "no" to any question erased everything. The scale is bigger than the original report suggested. Production has 9,641 half-finished surveys waiting for someone to come back, some of those people 59 questions deep, and before this every one of them would have been sent back to question one. About 5 percent have lost track of which question the person was on and still restart, with their previous answers kept either way; resuming those properly is filed separately.
Fix
Share links that went nowhere
When someone clicked a study's share link, WhatsApp sent the study's passcode to the bot and for some studies the bot simply never replied. It looked completely dead. The passcode starts with the first three characters of the account name, and if any of those was not a plain letter or number, an underscore, a space, an apostrophe, an accent, the bot did not recognise it as a passcode and treated the message as ordinary chat. This hit 11 studies across 7 client accounts, 9 of them live and taking participants, and everyone who clicked those share links hit a wall. Every place that reads a passcode now accepts what the platform actually creates, so those studies work again with nothing to do at your end, and every place that creates one now cleans it first. This was the fifth time a version of this has come back since February, so this time we checked every passcode in the system against every check that reads one, which is what turned up the other broken cases including one wrong since February.
Fix
Error text and invented transcripts in media answers
A client flagged transcripts in their export and results dashboard showing error text instead of the participant's answer, mostly on video responses. The old pipeline sent whole video files to a service that only reads audio, so larger ones were rejected and the error message was saved into the transcript field, where it read like an answer. Verifying that turned up a worse second problem: on quiet recordings the transcriber was inventing transcripts, because nothing told it which language to expect, producing hallucinated Korean video sign-offs and English answers written out as fake Swahili across 300 rows and 66 campaigns. Fabricated text is more dangerous than an obvious error because it reads as a genuine participant quote and could reach a client report. The move to Amazon Transcribe fixed the root cause, every transcription job is now pinned to the study's configured language instead of guessing, and the affected rows were reprocessed. One study is at 614 of 618 media answers transcribed with zero error strings and zero fabricated text, the remaining four being recordings with no discernible speech.
Fix
Photos and videos are no longer silently dropped mid-survey
The bot could drop a participant's photo or video part way through a survey with no trace anywhere. Reported and fixed this week.
Fix
The reporting toolbar is back on multi-day studies
On a multi-day study's Reporting and Graph Data screen the entire toolbar above the charts was hidden: Export PPT, Cross-tab, Filter, "Set questions to" (bar, table, pie) and Copy tables. Ordinary surveys showed it, studies did not, so the PPT export looked broken when nothing was actually wrong with the data or the export. All of those controls are back on every activity, including AI interview activities. The "copy share link" button on the same screen was disappearing for the same reason and is also fixed.
Fix
The results table pages past 100 again
Clicking through the responses table counted up 20, 40, 60, 80, 100 and then dropped back to 20 and would not go further. If one page request came back empty or timed out, the retry ran on top of half-finished bookkeeping and asked for a small page from the wrong position, so a single server hiccup collapsed a full table back to 20 rows and skipped everyone in between. Paging now carries on as you would expect, and the count shows where you are in the whole campaign ("Showing 101 to 200 of 1524") rather than only counting the rows currently loaded. Separately, the toolbar buttons above the table were being clipped at the bottom and now render in full, including on a phone where the row wraps. Survey, Recurring Survey and AI Interview get the full fix; Diary and Multi-Activity build their list rather than paging, so they get the button fix.
Fix
The Data Actions button in Table Data works again
Clicking "Data Actions" on the Responses screen did nothing at all, no menu and no error, on more than one study. The toolbar is built twice on the page, once for desktop and once for the phone layout, and the two copies were sharing a single label, so the menu kept attaching itself to the hidden copy while the button you could see had nothing connected to it. It came in with the phone-friendly card view on 26 July. Each toolbar now has its own label, and two other menus in the same toolbar had the same weakness and were fixed at the same time. Affects all four study types.
Fix
Media Library folders on multi-activity studies
On a multi-activity study the Media Library was merging different activities' same-numbered questions into one mislabelled folder, because each activity numbers its own questions from one, so Activity 1's Q1 and Activity 3's Q1 collided. No media was ever lost, it was purely how folders were grouped and labelled. One reported study went from 9 folders to 45 correctly labelled ones. Separately, campaigns with no media at all were showing a grid of populated-looking empty folder cards next to a "No media yet" message; they now show only the empty state.
Fix
Completion messages no longer send from the wrong number
Two related routing problems. An AI-interview completion message could go out through a completely unrelated organisation's WhatsApp number if that participant's number had more recently messaged a different organisation, because the lookup was by phone number alone with no campaign or organisation scoping. And resuming a paused session with "Continue" never refreshed the stored WhatsApp number, so a later completion message could go out from a stale one. Both now use the campaign's own number.
Fix
The completion message now appears in the transcript
When a participant finished a survey or a study day, the closing message ("That's all for today, thanks a lot! Talk again tomorrow.") was sent to them on WhatsApp but never recorded, so the transcript looked like the conversation ended one message earlier than it did. It is now written to the transcript as it is sent.
Fix
Big surveys no longer freeze the builder
Opening a survey with 50 or more questions in Build mode could blow memory past 2GB and freeze the tab.
Fix
Matrix questions on WhatsApp and in the builder
Three Matrix problems fixed together. Answer text was being cut off on WhatsApp, on the row statements, the answer scale and the row heading. The ✕ icon on Dropdown controls looked like a delete button. And a false "exceeds 80 characters" error was blocking campaign launch on normal-length Matrix rows.
Fix
Question types no longer show blank or revert
Two builder problems. A question type could revert to NPS after a page reload. And on a Statement question the type box showed an empty box with an arrow instead of reading "Statement", which looked broken and left it unclear what the question actually was. Nothing was ever saved wrong and no answers were affected, it was purely what the box displayed. The same underlying issue could blank the type box on Ranking, Scale, Location and Document questions if a campaign's settings were changed after the question was created, and those are fixed by the same change.
Fix
"None of the above" appears in multi-select forms again
The "None of the above" toggle was not rendering in the WhatsApp multi-select Flow, so a question configured with it went out without it.
Fix
The Insights screen is back to the layout you know
A change earlier on 5 August replaced the Insights tab under Reporting with a different design while fixing a separate problem where Insights came up blank on survey campaigns. The old layout is restored, the campaign overview written out in full at the top with themes down the left, and the blank-screen fix stays. Two other things sorted at the same time: the screen now explains what is happening when a campaign has not been analysed yet instead of going blank, and the response count on each theme shows the real number rather than a much smaller one.
Fix
Moderator takeover now shows every reply
During a human moderator takeover, a participant's repeated replies were not all appearing on the moderator's screen. Four identical "Okay" answers showed as one, and anything sent in the first few seconds after a moderator connected could go missing. The messages themselves were always stored correctly and the participant saw nothing wrong, but a moderator could be looking at a conversation and not know an answer had come in. Two causes: identical answers were being treated as duplicates and hidden, and loading the conversation history wiped out anything that arrived while it was still loading. Both fixed, on all campaign types.
Fix
Routing no longer breaks when an earlier activity completes
A participant manually advanced to a later activity in a study could have their message-routing pointer deleted when a different, earlier activity later completed on its own schedule, leaving them with nowhere for their next message to go.
Fix
Passwords were being written into our logs
When one of our services called an outside service and that call failed, we were writing the password for that service into our logs in plain text. This was happening on the live system, 54 times in the past week alone, across six different credentials. The two that matter most to clients are the ones behind "Sign in with Google" and "Sign in with Microsoft", and the temporary passes that keep someone signed in. Every place that records an error now writes only the plain description of what went wrong, and an automatic check now fails the build if anyone reintroduces this. Anyone who could read our logs could have seen these; there is no sign anyone did.
Fix
Small things that were quietly wrong
Video answers were labelled "Image Analysis" in the results view, when that text is actually what the person said written out, so it was telling researchers the wrong thing about their own data. It now reads "Video Transcription". A soft grey strip ran down the right edge of the Graph Data view, cast by two slide-out panels whose shadows kept painting about 50 pixels of grey while the panels themselves were parked off-screen. And stock backdrop thumbnails were showing as broken images in the reel editor's "Pair backdrops to clips" screen whenever a clip was paired with a video backdrop.
35 changes
New feature
Matrix questions: rate a whole list of things on one scale
You can now ask a Matrix question: give participants a list of items and one shared rating scale (1 to 5 by default, and you can relabel every point), and they rate the lot in one go. On WhatsApp it arrives as a proper grid the participant fills in rather than a long string of separate questions. Building one is a spreadsheet-style grid in the study builder, rows down the left and the scale across the top, with drag-to-reorder and in-place editing. You can randomise the row order per participant, translate the column labels, and the WhatsApp confirmation now names each row so it reads "Street food: 5, Home-cooked: 3" instead of "Rating: 5, Rating: 3". It works across Survey, Recurring Survey, AI Interview and Multi-Activity studies. This was the single biggest capability gap clients kept running into.
New feature
"Select all that apply" questions arrive as a tappable form
Multiple-choice questions that let people pick more than one answer used to reach participants as a plain text list they had to reply to with letters ("reply A, C, E"). They now arrive as a clean WhatsApp form with tappable checkboxes, the same format as Matrix questions, including any "pick at least or at most N" limits and a Back button for changing an earlier answer. Studies that don't have the form set up keep working exactly as before with letter replies, so nothing breaks mid-field. Single-select multiple choice is unchanged.
New feature
17 ready-made interview briefs, and an assessor that reviews yours
The Research objectives step of an AI interview now has two new things. A template gallery of 17 interview briefs, written from studies that actually ran well in production: browse by category or search, preview the full brief, and start from it instead of a blank box. And an objective assessor that reads your brief back to you when you've finished writing it, with a quality rating, a plain-language summary and specific fixes you can apply in one click. It can also fill in your target audience, key topics and required questions, and anything it changes can be undone. The assessor is advisory only. It never changes your campaign settings on its own.
New feature
Yazi now works properly on a phone
We spent the week making the web app usable on a phone rather than a shrunken desktop site, and the whole batch is live. Pop-up dialogs slide up as full-width sheets from the bottom instead of stranding a thin card mid-screen. Responses arrive as readable cards, one respondent per card with their answers stacked, plus a Cards/Table switch if you'd rather compare across people, and your choice is remembered. The dashboard campaign list, broadcast history, Share screen and broadcast send flow all stack one item per row instead of squeezing into columns. The study title and the Build/Share/Responses/Reporting tabs are readable and scroll cleanly. The navigation drawer has a close button and responds to Escape. Adding a question opens the card fully expanded, and the per-question actions sit behind a labelled menu instead of running off the edge. And the floating Ask Yazi button no longer sits on top of the main Continue button, which was making the primary action partly untappable. Desktop is unchanged throughout.
New feature
Export results as numeric codes, not just answer text
Quant teams working in Q or SPSS can now choose how a CSV or Excel export is written. Answer values can come out as labels, as numeric codes, or as both in separate columns. Column headings can be the full question text or short variable names (Q1, Q2). Multi-select questions can be split into one 0/1 column per option, matching the SPSS export. A small options screen appears when you click Export and it remembers your choice, so you don't set it every time. It's on Survey, AI Interview and Recurring/Diary results. This is presentation only: the raw data and the existing SPSS (.sav) export are unchanged.
New feature
Pipe someone's earlier answers into a later question's options
A question's answer options can now be built from what the participant picked earlier, instead of being typed out by hand. Ask which brands someone uses, then have the follow-up show only those brands. You set it up in a Piping panel next to Question Logic in the builder, and the options are resolved at send time from that person's actual prior answer. It handles the awkward cases properly: if the source question was skipped, answered with "none of the above", or left unanswered, the piped question is skipped forward rather than sent with nothing in it.
New feature
Retry a reward payment that failed
Reward Approvals now has a Failed tab listing every payment that didn't go through, why it failed, and how many times it was tried, with a Reprocess button on each row. Some failures happen for reasons that go away, for example the airtime float being topped up a few minutes later, and until now a failed payment was simply stuck. Reprocess now genuinely gives a payment a fresh set of attempts. It also can't accidentally pay someone twice: before sending again it checks with the provider whether the earlier attempt actually went through, and adopts that result if it did.
Improvement
Reward payouts now wait for credits instead of getting stuck
If a participant finished a study at a moment when the account had run out of reward credits, their payout used to get stuck and never go out, even after the account was topped up. Someone had to re-approve each one by hand, and in practice people were being left unpaid. Those payouts now park in a clear "waiting on credits" state and send themselves automatically the moment the balance is topped up. The rewards screen shows that state plainly instead of spinning.
Improvement
Big studies open twice as fast and no longer freeze
Clicking "Load all" on a study with hundreds of responses could lock the browser tab for minutes and sometimes looked like a crash. The cause turned out to be our own session-recording tool trying to capture the entire results grid every time it redrew, which on a 1,523-respondent study was 91 percent of all the work the browser was doing. That recorder now skips results grids, and the results page no longer builds a hidden second copy of the whole table for phones when you're on a laptop. On the study that reported it, Load all went from roughly 18 minutes to 18 seconds. Opening a large study's responses went from about 22 seconds to about 11, and the page stays usable throughout. Three places that were only ever looking at the first 100 responses are fixed too: adding data to a study, downloading photos and voice notes, and approving participant incentives, which previously meant you couldn't see the answers of the 150th respondent you were paying.
Improvement
Shared results links show the whole study, and no longer carry participant details
The public shared-results link got a redesign: a proper header with your logo, the study name, who shared it and a "view only" pill, cleaner white cards, and a Bar/Table/Pie toggle the viewer controls. It also closed a real privacy problem. The public link previously exposed participant phone numbers and demographic details in its underlying data; respondents now appear as "Respondent 1", "Respondent 2" and that data is stripped before it leaves our servers. Separately, a shared link for a multi-activity study used to show only the first activity. It now shows the whole study, every activity's charts stacked under the study title, with a per-activity picker for transcripts. Existing links get all of this automatically, so nothing needs resharing.
Improvement
A readable phrase to start a study on WhatsApp
The message a participant sends to begin a study used to be a bare code, which people mistyped, edited or deleted, and then hit a dead end. It now reads as a sentence, for example "Send to start #4F9A1", and the Share Link modal offers the phrase in each language the study runs in. Campaigns already launched are unaffected, since a phrase is only ever finalised once at go-live.
Improvement
Change how every question displays in one click
The results toolbar now lets you switch every question to Bar, Table or Pie at once, instead of setting each one on a large study, and the toolbar itself is icon-first so it stops crushing the stats row on a laptop. In Table Data you can also hide or show a whole family of columns at a time (Survey answers, Themes, Transcriptions, Translations) rather than toggling columns one by one to reach the transcripts.
Improvement
Turn the participant progress counter on or off
The "Question X of Y" counter that participants see is now under your control on every study type. The Hide Message Count setting, previously only on AI Interviews, is now on Surveys, Recurring Surveys, Diary studies and Live Forms, and a bug where the setting didn't actually take effect on surveys is fixed. Newly created campaigns hide the counter unless you switch it on. Anything already running is unchanged.
Improvement
Question images now show in the transcript
When a study attaches images to a question, for example asking people to rate a logo or a pack shot, those images go out to participants on WhatsApp but were missing from the transcript on the Responses screen. You'd see the question and the answer but not the thing the participant was actually looking at, which made responses hard to read. The transcript now shows each question's images, with captions, in order, exactly as the participant saw them, across all four study types.
Improvement
Activity schedules now explain what they actually do
A setting called "Only send once the previous activity is completed" was saving fine but nothing in the platform ever read it, so switching it off changed nothing. On one live study that meant 19 people were expected to get an invite and 3 did, with nothing on screen explaining the gap. We removed the switch rather than leave it promising something the platform can't do, and put a "How this schedule works" section in its place that explains the real behaviour: each participant moves at their own pace, the time you pick is the earliest an invite can go out after they finish the previous activity, people who haven't finished wait rather than being skipped, and if the time has already passed when they finish, the next activity opens straight away. Second fix on the same screen: if you hadn't picked a broadcast or written an invite message, Save still looked clickable and silently did nothing. It's now properly disabled and tells you which field needs filling in.
Improvement
Create a broadcast template without leaving the send flow
Sending a broadcast from the Share tab used to bounce you out to the Broadcast Messages screen if you needed a new template, and you'd lose your place. There's now a "+ New template" button inside the send wizard that opens template creation on top of it, so you land back in the same flow with your template ready. Works across all campaign types, in English and Portuguese. Related: extra columns in an uploaded recipient CSV, for example surname, category or group, now appear as selectable message variables. Previously anything beyond phone and name was silently dropped from the variable list, the preview and the outgoing file.
Improvement
Ask Yazi understands Matrix questions, and speaks in names not IDs
Ask Yazi didn't know Matrix questions existed. If you asked for one it said it couldn't, and if it drafted a study that needed one it quietly substituted an ordinary open-text question, so you got a weaker questionnaire than the one you described with no indication anything had changed. It now suggests, builds and converts Matrix questions properly, and tells you when one won't work on a given campaign. Separately, when it proposes a change the confirmation card now shows the campaign's name and the question number ("Q1") with the answer options as tags, instead of a long internal ID and a key like "iXjCCMn".
Improvement
Filter media by the answer someone gave
The media library filter that lets you pull voice notes and photos from people who gave a particular answer has been in the product for a while and, it turns out, never matched anybody. It's now fixed end to end, including the case where option wording was edited in Build after respondents had already answered, which used to break the match. The filter list has also been reorganised into a Questions folder split by with-media and without-media, instead of one long flat list.
Improvement
The Share tab now speaks Portuguese
Every piece of wording on a campaign's Share tab now comes from our translation files rather than being written into the page, so the Portuguese white-label build stops showing English on that screen. Nothing changes for English users. We also added an automatic check that fails the build if any of this wording goes missing, because when a translation is absent the system quietly prints its own internal label on screen instead of raising an error, which normal testing never catches.
Improvement
Better test-run coverage in the Simulator
The Test Simulator's Run Simulation view was reworked, with logic-path coverage so you can see which routes a test run exercised, and detail on past runs. Separately the workflow canvas got a usability pass (edge routing, click handling, drawer navigation and the embedded logic-rule editor), and "Decision Map" is now called "Logic Map" throughout the builder.
Improvement
LSM bands calculate automatically on the Ipsos panel
LSM, the 1 to 10 Living Standard Measure band worked out from a participant's household answers, used to be calculated only as a side effect of a Tivian webhook, so any study without that webhook attached never produced a band. It now calculates whenever a participant finishes a survey and is stored on the participant, so quota logic and per-band broadcasts can read it. No change for any organisation other than Ipsos.
Improvement
Security and privacy hardening across the platform
Another round of hardening shipped ahead of the upcoming audit. The parts worth knowing about as a client: participant answers, voice-note transcriptions and the AI interviewer's replies are no longer written into our logs word for word, so a survey answer containing a name, a location or a health detail can't be read out of a log; the AI interviewer is now protected against instructions hidden inside an uploaded participant list, with uploaded details clearly marked as information to read and never as commands to follow; we send the AI less personal data, with surnames removed entirely and names shortened to a first name, which matters for POPIA and GDPR because those prompts are processed outside South Africa; two paths that create and update AI interview records were missing an ownership check and now confirm you belong to the organisation that owns the interview before anything is written; and the production database has stopped accepting connections from a broad whole-network rule, so only the specific services that need it (plus the team VPN) can reach it, with a watchdog that checks every five minutes. No customer data was changed and we found no sign any of these gaps were ever used.
Fix
Broadcast "Started" counts were reading zero
If you sent a broadcast from a multi-activity study, Send History showed Started: 0 even when people had plainly begun, which made the whole table look untrustworthy. Two things were wrong: broadcasts sent from a study were filed against the study while the count looked them up against each individual activity, so it found nothing; and someone only counted as "Started" once they had replied, so anyone partway through was invisible. Both are fixed. Across the platform this recovered 1,175 participants who were being under-counted, 155 broadcasts now report higher, correct numbers, and not one went down. The page also loads about five times faster.
Fix
Failed reward payouts no longer show as if they were fine
On the Incentive Approvals screen, a reward payment that failed was displayed as a plain grey "Not required", visually identical to one that had been paid. The "Failed" counter at the top was structurally incapable of ever showing a number, so it always read zero. On live data that meant 61 rewards which genuinely failed to reach participants were invisible on that screen, with 50 of them counted under "Approved". A failed payout now shows as a red "Failed", the counters add up to every reward in the list, and a failure is never counted as approved. Reward Approvals also gained a search by participant ID and a CSV export of the visible list.
Fix
PowerPoint downloads work again on multi-activity studies
Downloading a PowerPoint from a study activity had been failing since 13 July with a red "Generation Failed" banner that only said "Network Error", so no study-level PowerPoint had been generated in that time. The report was never the problem: the request was being sent to the wrong one of our two APIs and rejected before anything started, and a browser reports a missing endpoint the same way it reports a lost connection, which is why the error pointed at the network. That's fixed, and we've added an automated check that verifies every request the app makes actually points at an API that can serve it, since this same mistake has reached production eight times over the past months. Campaign-level PowerPoint export was never affected.
Fix
The completion message setting now stays where you put it
Switching on "Send a completion message" wouldn't stick: it looked saved and then quietly reverted after publishing, and once a study had the closing message off there was no way to switch it back on from the platform at all. The closing message is where clients often put payment instructions or a link, and two of the affected client's live surveys were finishing without one. The reverse case is fixed too, where publishing could wipe a deliberately switched-off setting. Applies to every organisation and all four study types, and nothing anyone had written was lost.
Fix
Participants mid-study are no longer told they aren't enrolled
Someone partway through a multi-day study who sent a message in the gap after finishing one activity and before the next one opened could be told "you're not enrolled in any interviews at the moment", which reads like being removed from the study. They now get a proper reply saying they're still taking part and we'll message them when the next activity is ready, in whichever language they're already being spoken to in. Related: a participant who finished an activity later than planned used to have the next activity start cold without the invite message the researcher had written, and that invite is now sent first. The Opt out button on those invites also wasn't actually opting anyone out, and on Portuguese studies it would have restarted the study rather than ending it. Both fixed.
Fix
Messages WhatsApp rejects are no longer lost
When someone answers very quickly, WhatsApp sometimes refuses the next message because it limits how fast one business number can message one person. That message used to be thrown away, leaving the participant waiting for a question that was never coming, with nothing recorded. Rejected messages are now saved and automatically resent a few seconds later, and if one still can't be delivered after several tries it stops and raises an alert rather than disappearing quietly. Surveys aren't any slower: the first attempt is still sent immediately and nothing is saved or retried unless it has already failed. Nobody gets asked the same question twice.
Fix
Answers and photos that were being silently dropped
Four separate ways a participant's answer could go missing are fixed. Photos sent at the moment a survey was expecting a button answer were being discarded while the participant still saw a "thanks for your images!" message, so nobody knew data was lost; they're now held and attached to the upload question. A participant removed from a study and then re-added had their new answers written but permanently hidden from the transcript, Table Data and every export. People recruited through a Facebook ad were answering the consent question and never getting the button through to the actual survey, because the redirect was sent using the wrong WhatsApp number's credentials and Meta rejected it. And participants tapping a click-to-chat link sometimes had the whole link pasted as their message, which our system couldn't read as a survey code, so they were told they weren't enrolled in anything.
Fix
Round selfie videos now get a reply
If someone answered a question with one of WhatsApp's round "instant video" selfies, our bot said nothing back. The message looked delivered on their side, no answer was recorded, and the study appeared to have gone dead, so people simply stopped. WhatsApp doesn't pass those videos to us at all, it only tells us "unsupported type", and we were quietly accepting that. Participants now get told straight away that we can't accept that format and to send it another way, in whichever of the 17 languages they're being spoken to in, rate-limited to one notice per person every five minutes.
Fix
Duplicating a study no longer copies the original's routing
Duplicating a campaign left the copy's logic rules pointing at the original campaign's questions, which surfaced in the logic editor as blank or "Participant Language" rules defaulting to Q1. Fixed in both the Duplicate Campaign button and the study/activity duplication path, and the one live campaign affected has already had its data corrected. No participant was affected.
Fix
The question builder no longer loses focus while you type
When you were building a survey and typing an answer option, the text box was losing focus on almost every keystroke, so you'd type a letter and get kicked out. This was a large part of why people abandoned question setup partway through. Building questions holds focus properly again.
Fix
The Participants tab shows the right information
Three things on the Participants tab were wrong. "Last activity" was always blank even for people who had clearly started, because the information was being dropped before it reached the screen. "Source" said "Link" for people uploaded by CSV, because the rule was backwards and treated an inferred link as more trustworthy than a file someone deliberately uploaded. And people who'd already been sent a broadcast still showed "Ready to invite" on multi-activity studies. All three are fixed, along with the filter counts, which were under-counting in the same way.
Fix
Panel completes from PureSpectrum are credited properly
When someone from a paid panel finished one of our surveys, we sent them back to be marked complete and paid, and that handover has to be cryptographically signed. Ours wasn't signed correctly, so it was rejected, and silently: the respondent saw a "thanks, you're done" screen, so nobody had any signal anything had gone wrong. They just never got paid and we never got credited. Fixed end to end, and anything unexpected is now rejected outright rather than waved through as a complete.
Fix
Small things that were quietly wrong
A handful of smaller fixes worth knowing about. "Other" now appears as a selectable answer in Question Logic when its toggle is on, instead of being dropped from the routing rule builder. The Insights tab shows the survey analysis that already existed on studies set up as interviews but answered like a survey, and shows a proper "no insights yet" empty state rather than a blank section or a copy of Graph Data. Test-data deleted with "Remove all simulated" now disappears from results immediately instead of lingering for up to fifteen minutes. Publishing no longer reports false "empty text" errors against the wrong question number or creates phantom duplicate blocks on retry. The Test Simulator, which had been unable to run any survey since a protective change the day before, works again. You can finish signing up on a short browser window, where the Create Account button used to be out of reach with no way to scroll. And new organisations reliably get their demo survey data, which for accounts with AI switched off was being thrown away by a failing AI-interview step. In the agent takeover screen, a participant's first message after connecting no longer goes missing, and photos a researcher sends now display instead of showing as broken images.
20 changes
New feature
Participants can now see how far along they are
Survey questions on WhatsApp now show a running count ("Q1 of Q2", "Q2 of Q2"), and when a survey rolls into an AI interview the count keeps going ("Q3", "Q4") instead of restarting from one. We deliberately don't show a total for the AI-interview part, because the AI often wraps up early, so rather than promising "Q1 of 5" and stopping at three, it just keeps counting honestly. It works across every campaign type, and if you've hidden the counter it stays hidden. Nothing about answers, routing, data or reports changes: this is display only, so people are less likely to drop off wondering how much is left.
WhatsApp survey question showing a "Question 2 of 13" progress countNew feature
Group recurring-survey results by participant or segment
The Recurring Survey results table (Responses, Table Data) now has a Group by control: None, Segment or Participant. On a recurring or diary study a person answers over many waves, so the flat table ends up with hundreds of rows and one participant's answers scattered across all of them. Grouping folds that into tidy collapsible headers like "Participant X (9)" that you can expand or collapse, so the table is finally scannable. Grouping is a view preference only: your exports and charts still use the full underlying data.
New feature
A translated transcript column for AI interviews
AI-interview Table Data now carries a Translated Transcript column, so interviews run in another language show the translation alongside the original without you exporting and translating by hand.
Improvement
Reporting numbers now agree across every tab
A study's Graph Data, Report and Insights tabs used to show different headline numbers, single-choice answers could add up to more than 100 percent, the Insights text showed stray ** symbols instead of bold, and the raw-responses export couldn't be grouped. All of that is fixed. Single-choice percentages now total exactly 100 percent (multi-select still shows real per-option shares), the report's fieldwork dates, sample size and headline stat match reality with the hero number paired to the caption that describes it, Insights and the exported PowerPoint show proper bold text, the PDF renders cleanly, and the raw-responses CSV/Excel now carries a stable per-interview and per-question id so you can group it by participant or by question.
Improvement
Block routing now works in in-chat surveys too
Routing between blocks used to be a WhatsApp Flow feature only. It now works in in-chat surveys as well, and the rules are more capable: an Always-Go-To rule, multiple conditions combined with AND/OR in a single modal, and loop detection so you can't build a route that circles back on itself. Each Flow-enabled block also gets an eye icon that previews the whole block as a real WhatsApp Flow screen, with an all-at-once versus one-at-a-time toggle. We also fixed the "equals" condition, which could silently produce a rule that never matched.
Improvement
AI interviews always ask your required closing question
You can set a question to be asked at the very end of an AI interview, for example "please share the number for your incentive". The interviewer was sometimes hitting its message limit and ending without ever asking it. It now guarantees any required question is asked before it wraps up, word for word, on the last turn, translated automatically if the interview is running in another language. A genuine "I'm done" from the participant still ends things gracefully, and the study builder now explains that required questions are always asked near the end and lets you reorder them.
Improvement
Trust review is clearer, and now lives in Table Data
The Participants tab now splits the Trust column into a Verdict and a Reason (previously only visible on hover), and when you change a verdict you can add a note that shows under the AI reason with your name and the date. The same trust status and note are now available as columns on the survey and interview Table Data grid, with an "Approved" status filter and a bulk verdict-update popover so you can review and update many rows at once.
Participant table with a Trust column showing an Approved verdict and the survey-done funnel filter selectedImprovement
Broadcasts show the right status
Several broadcast status problems are fixed. Recipients could get stuck on "Pending" forever when a status update from WhatsApp arrived a second before we'd finished writing the message's tracking record; we now write the record as the message is sent and hold any too-early update briefly until it lands. Sends that can never go through because an account is billing-blocked now correctly show as Failed instead of Pending, and recipients left pending are aged to "unconfirmed" after 24 hours. So the dashboard reflects what actually happened.
Improvement
Panel completes from PureSpectrum now register
When someone recruited through PureSpectrum finished a survey, they were marked complete on the panel's side but Yazi never ticked them off, so the recruitment window sat on zero with an empty progress bar even though people had genuinely finished. On the study that flagged this, 20 people had completed and Yazi showed none. That handoff is fixed, and completions are now counted once and only once even if the same message arrives twice.
Improvement
Airtime rewards now work like the other reward types
Airtime rewards now get the same broadcast-selection experience as Tremendous vouchers, and reward confirmations send as an in-window message first, falling back to an approved template once WhatsApp's 24-hour session window closes. Separately, if an organisation doesn't have its own airtime-confirmation template approved with Meta, the confirmation now falls back to a plain WhatsApp text rather than silently never arriving. The reward itself was always delivered; this makes sure the participant always gets told.
Improvement
A cleaner study setup screen
Study settings now live in a floating panel on the right of the Build tab, with a quick switch between Settings and Blocks. Everything sits in the same place for every study, so there's nothing to relearn.
Improvement
Media in results loads faster
Audio, video and picture grids in the qualitative results card now load progressively instead of rendering everything at once, so studies with a lot of media open noticeably quicker.
Improvement
Ask Yazi no longer swallows the questions it drafts
When you asked Ask Yazi to propose a study or survey, it could end with an empty chat bubble under a false "changes applied" banner, dropping the questions you'd asked for. The proposal now renders as text you can read, and proposing a plan is no longer mistaken for a change that was applied.
Improvement
Recurring-survey results table matches the others
The Recurring Survey results table now has the same toolbar as Survey and AI Interview: a show/hide-columns button, a compact Export button, and a Shareable-link button aligned with the rest. While building show/hide columns we also fixed a subtle issue across Survey, AI Interview, Recurring Survey and Multi-Activity where hiding a column could quietly drop it from an export. Hiding a column is now purely a view preference and never changes what's in your download.
Improvement
Security and privacy hardening across the platform
We ran another security pass this week as part of pentest-readiness and shipped a batch of hardening to production. The parts worth knowing about as a client: our AI-interview chat servers now accept only modern encryption (TLS 1.2 and 1.3) and refuse the old, unsafe versions; every backend service now fetches its passwords and API keys from a secure store at runtime rather than holding them in plain configuration; all traffic to the production database is encrypted and the database now sits in a locked-down private network; fonts are served from our own servers instead of a third party; and the production firewall now inspects all traffic with no exceptions. Nothing was breached; these close gaps proactively, with no change to how anything works for you.
Fix
Rewards in local currencies are billed correctly
Rewards paid in a non-US currency (for example R35 of ZAR airtime) were being deducted from your credit balance as if the local-currency number were dollars, so R35 took $35.00 instead of about $2.12. Credit checks and deductions now convert the reward's local-currency value to USD at a live rate before touching your balance, and the participant results table shows the real reward amount rather than the converted figure.
Fix
Hidden phone numbers stay hidden, and shown ones aren't faked
An organisation that had never explicitly set its phone-privacy preference was being treated as "hide numbers", which masked every participant's number and surfaced as garbled fake numbers in the Media Library. Numbers now only hide when an organisation opts in, and the Media Library no longer formats a masked id as a fake phone number.
Fix
You can finish signing up on your phone
When someone created an account on a mobile phone, the welcome screen filled the display and the "Get Started" button was hidden behind the browser's address bar, so new users got stuck partway through signup. The screen now sizes itself to the visible area, so the button always stays in view. Signing up on a desktop was never affected.
Fix
No stray translation columns on single-language studies
Downloading Table Data for a study without translations turned on still included empty "Translation" columns in the export and the on-screen table. Those columns now appear only for studies that actually have translations enabled.
Fix
Broadcasts accept spreadsheets saved with semicolons
A recipient file saved with semicolons between columns (a common Excel regional setting) was read as having no valid phone numbers, so the broadcast failed with a vague error. Uploads now accept any common separator (comma, semicolon, tab, pipe), and when a send genuinely can't go ahead the screen shows the real reason instead of a generic message.
12 changes
New feature
Route between blocks in a WhatsApp Flow survey
Blocks group questions onto a single WhatsApp screen, and you can now set what happens after each screen: if the answer was X, skip ahead, screen the person out, or end the survey. Routing only ever moves forward, which is what WhatsApp allows, so you cannot accidentally build a Flow that Meta rejects. Each block also gets a show-all versus one-at-a-time toggle, so you choose whether the questions on a screen appear together or reveal one after another as the person answers. Grouping questions no longer wipes your existing skip logic, which was an old rough edge.
Improvement
One share link, all your results in tabs
Sharing a campaign's results externally used to mean sending up to three separate links: one for Table Data, one for Graph Data, one for Transcripts. It is now a single link that opens one page with tabs for all of them, so your client sees everything in one place. Shared Table Data and Transcript links also used to stop at the first 25 rows. They now return the full result set. Older links still work, and the Copy share link buttons sit exactly where they did.
New feature
Wire up event triggers yourself
When you set up an event-triggered schedule, the summary screen now shows your Configuration ID and Organisation ID with tap-to-copy, and the API returns them too. You can connect your own systems to a Yazi trigger without asking us to look the IDs up for you.
Improvement
The broadcast dashboard now shows real Started and Completed counts
Started always read 0 on the broadcast dashboard, even when people had genuinely begun the survey, and there was no Completed count at all. Both numbers were being read from WhatsApp's delivery status, which only knows whether a message was sent, delivered, read or accepted. They now come from the survey itself, and there is a new Completed tile alongside them. To be precise about the three: opted in means they accepted the WhatsApp invite, started means they began the survey, completed means they reached the end.
Improvement
Test data now behaves the same way everywhere
Test-simulator responses used to appear in some reporting views and silently vanish from others, so the charts, the table and the headline counts could all disagree while you were checking your setup. There is now one labelled control on a study's Reporting page. Switch it on and test responses appear consistently across the table, the charts, the media library and the response counts. Switch it off and they all disappear together, and the platform remembers your choice per study. Test data stays clearly labelled and can never end up in an export, a report or a shared link.
Improvement
Ask Yazi tells you what it did
When you ask Ask Yazi to make a change, it now shows a summary card at the top of the panel once it is done: "3 of 4 changes applied", with any failures or skipped steps called out, and the full step list if you expand it. It used to just go quiet and you had to ask whether it had worked. The count now reflects real changes only, so read-only steps like searching or reading a report no longer get counted as edits it failed to make.
Improvement
Study Simulations are about twice as fast
A Run Simulation with around 20 synthetic personas used to be slow and could freeze partway through, because only 4 personas ran at a time and the run hit an internal time limit. It now runs 8 at a time, so a 20-persona run finishes in roughly 9 to 10 minutes and completes reliably.
Improvement
Clearer "Screened out" on the Share screen
Participants who were screened out of a survey used to show a half-finished progress bar, which read as though they had dropped off mid-way. They now show a clean "Screened out" bar on both the campaign and study Share screens.
Improvement
Security and privacy hardening across the platform
We ran a full security pass this week and shipped a batch of fixes to production. The ones worth knowing about as a client: access to campaigns, panel campaigns, reports, participant lists and interview transcripts is now checked against the organisation that owns them, so nothing can be reached across organisations; sensitive data such as phone numbers, survey answers and tokens is no longer written to our internal system logs in plain text; our product analytics no longer captures on-screen text or identifiers from research screens; and our core web libraries are on their patched versions. Nothing was breached. This is us closing gaps proactively.
Fix
PDF transcript export now works
Per-respondent PDF transcript export had been failing since it launched, and the two earlier fixes were treating symptoms. The real cause was memory: image-heavy transcripts decode every image at full resolution during the render, which exhausted the export worker. That is fixed and exports run through, faster than before.
Fix
AI chart summaries no longer quote counts that contradict the chart
The AI summary under a chart used to quote a fixed respondent count, such as "5 out of 7", which could disagree with the total shown above it once you hid test data. Summaries now describe findings in words instead of quoting counts. Existing summaries keep their old wording until they next regenerate.
Fix
White-label participants no longer see English or the wrong brand
Three participant-facing surfaces still had English-only text or hard-coded Yazi branding: the in-app AI assistant panel, the WhatsApp survey fallback messages ("you've already completed this", welcome-back, completion), and the AI assistant's action cards. All three now follow the client's own brand and language. The default English experience is unchanged. One related fix, the screening web page, is ready but waiting on its deploy pipeline.
13 changes
New feature
Swahili is now a full platform language
Surveys, interviews and diary studies can run end to end in Swahili. Every participant-facing message, button and prompt is translated, and Swahili now shows up in the language pickers everywhere instead of only in some places. This opens up clean fieldwork in Kenya and the wider East African market. One thing to know: WhatsApp template approval for Swahili still needs to be submitted in Meta Business Manager before templated broadcasts go out in the language.
New feature
Turn AI off per account and per surface
You can now switch AI features off for a specific account, surface by surface. There are 14 toggles covering things like report generation, highlight reels, transcription and image analysis, plus an approval step so a change has to be signed off before it takes effect. This is built for clients whose own governance rules say certain data cannot be processed by AI. When AI is off for an account, those surfaces show a clear disabled state instead of running.
New feature
Send rewards as airtime or store vouchers
Participants can now be rewarded with airtime (via Reloadly) or store vouchers (via Yoyo / wiGroup), on top of the existing options. The reward amount shows in the delivery message so the participant knows exactly what they got. Handy for incentivised recruitment where cash is not the easiest thing to hand out.
New feature
Approve reward payouts before they go out
There is a new Reward Approvals drawer on the Share screen. You can see each pending payout with its delivery status, a per-person reward snapshot and the participant's trust score, then approve or decline before anything is sent. It puts a human check between a completed response and money leaving the account.
New feature
Restrict an API key to specific endpoints
When you create a Connect Gateway API key you can now scope it to specific endpoints instead of giving it full access. There are presets for trigger-only, read-only and full access, plus a custom option, and the limit is enforced at the gateway. Existing keys are untouched and keep working exactly as before.
Improvement
Open a survey with the participant's name
Surveys can now start with the participant's name, for example "Hi Thandi", using a new name variable in piping. Until now only the AI interviewer picked up the name. Worth knowing the name comes from the participant's WhatsApp profile, so it is not guaranteed for every person, and there is a sensible fallback when it is missing.
Improvement
Switching between accounts is now instant
Moving between organisations used to trigger a full page reload that could take up to two minutes. It now does a soft reset with a short loading screen, so the switch feels instant. This mostly helps anyone managing several client accounts from one login.
Improvement
One review step before you publish
All three builders now share a single pre-publish review panel that checks your study and flags anything to fix, replacing the old stack of publish pop-ups. You can also edit the incentive amount and response-quality settings right there before going live.
Improvement
Recurring survey graphs now cover every question type
Graph data on recurring and diary studies used to show only multiple-choice questions. It now includes every question type, so you get the full picture of what is changing over time.
Improvement
Smarter scheduling across timezones
The schedule picker now covers more timezones, shows GMT offsets and defaults to your own timezone, and the schedule tag is easier to find. Fewer chances of a broadcast going out at the wrong local time.
Fix
Flow settings now save reliably on surveys
Flow configuration (the CTA message, button text and welcome message) was in some cases not saving and reverting to English defaults on reload. That is fixed, so what you set is what participants get.
Fix
No more translation prompt on exports with nothing to translate
The "Translate before downloading?" pop-up was appearing on table-data exports even for campaigns that had no translations at all. It now only shows when there is genuinely more than one language in play.
Fix
New-account onboarding and demo restored
Fresh signups were in some cases missing the onboarding wizard and the demo campaigns. That is fixed, so a brand new account lands in the intended first-run experience.